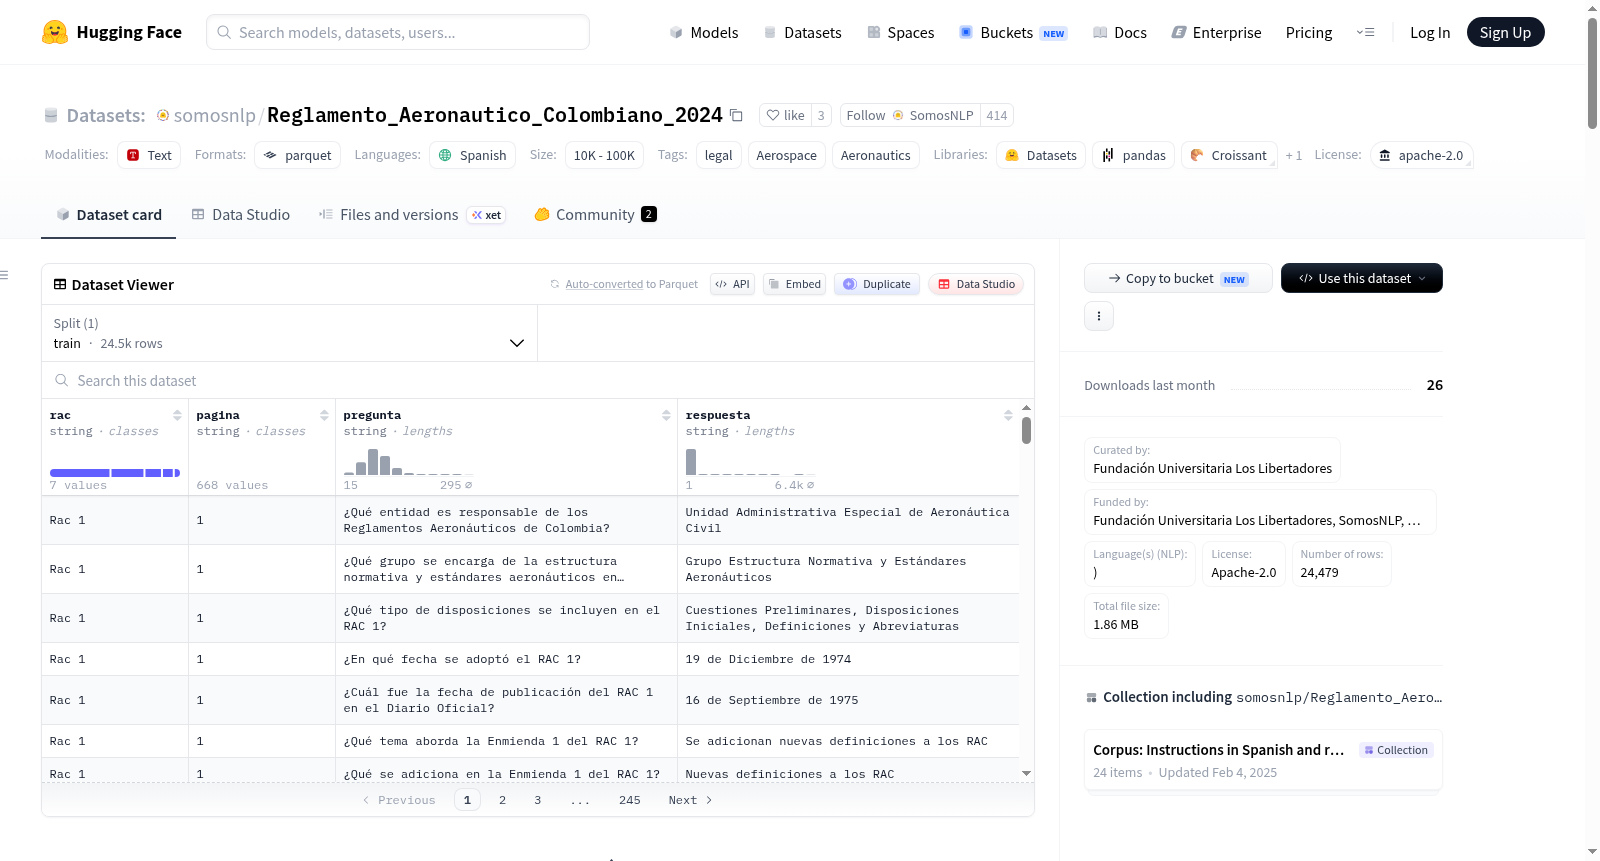
somosnlp/Reglamento_Aeronautico_Colombiano_2024
收藏资源简介:
该数据集包含来自哥伦比亚航空法规(RAC)的标注样本,涵盖了其所有章节。经过细致的标注和整理,数据集已达到100%的进度,相当于总共25,174个整理好的样本,可供使用。数据集设计用于文本生成和问答系统,以促进对哥伦比亚航空法规的导航和理解。它包括以下列:rac(法规文本)、pagina(页码)、pregunta(问题)和respuesta(答案)。数据集以Gemma格式提供,并优化用于语言模型的训练。数据集是通过自动化过程创建的,涉及PDF到文本的转换以及通过GPT API或类似的开源模型进行处理。使用Hugging Face环境中的Argilla框架进行整理,确保高质量的标注。数据集在Apache-2.0许可下分发,适用于与航空航天领域相关的NLP应用。
This dataset contains annotated samples sourced from the Colombian Aviation Regulations (RAC), covering all its chapters. After meticulous annotation and curation, the dataset has reached 100% completion, with a total of 25,174 curated samples available for use. It is designed for text generation and question answering systems to facilitate navigation and comprehension of the Colombian Aviation Regulations. The dataset includes the following columns: rac (regulatory text), pagina (page number), pregunta (question), and respuesta (answer). Provided in Gemma format and optimized for language model training, it was created through an automated pipeline involving PDF-to-text conversion and processing via GPT API or comparable open-source models. The dataset was curated using the Argilla framework within the Hugging Face environment to ensure high-quality annotations, and is distributed under the Apache-2.0 license, suitable for NLP applications related to the aerospace domain.
数据集概述
数据集基本信息
- 名称: RAC Corpus: Base de Datos del Reglamento Aeronáutico Colombiano
- 语言: 西班牙语 (
es-CO) - 许可证: Apache-2.0
- 大小类别: 10K<n<100K
- 标签: legal, Aerospace, Aeronautics
数据集内容
- 特征:
rac(字符串): 法规文本。pagina(字符串): 文本页码。pregunta(字符串): 关于内容的问题。respuesta(字符串): 提出的问题的答案。
- 分割:
- 训练集: 24,479个样本,大小为6,692,842字节。
- 下载大小: 1,844,154字节
- 数据集大小: 6,692,842字节
数据集来源
- 数据来源: 从哥伦比亚民航局网站(https://www.aerocivil.gov.co/autoridad-de-la-aviacion-civil/reglamentacion/rac)精心提取和整理。
数据集版本与格式
- 格式: Gemma,优化用于语言模型的训练。
数据集使用
- 直接使用: 设计用于文本生成和问答系统,以促进对哥伦比亚航空法规的理解和导航。
- 超出范围的使用: 在没有专家监督的情况下,可能不适合需要精确法律解释的应用。
数据集结构
- 总计: 25,174个样本
- 结构: 包含
rac,pagina,pregunta,respuesta四个字段。
数据集创建
- 创建过程: 通过自动化过程从RAC创建,包括将PDF文件转换为文本,并通过GPT API或类似的开源模型处理,以两页为单位迭代提取数据。
数据集标注理由
- 标注: 使用Argilla框架在Hugging Face环境中进行结构化标注,由Fundación Universitaria Los Libertadores的航空工程专家评估样本质量。
偏差、风险和限制
- 潜在偏差: 可能包含航空领域官方文件中使用的正式语言的固有偏差。建议谨慎推广基于此数据集的结果。
许可证
- 许可证: 本数据集根据Apache-2.0许可证分发,允许广泛使用和修改,限制较少。