amaai-lab/MusicBench
收藏资源简介:
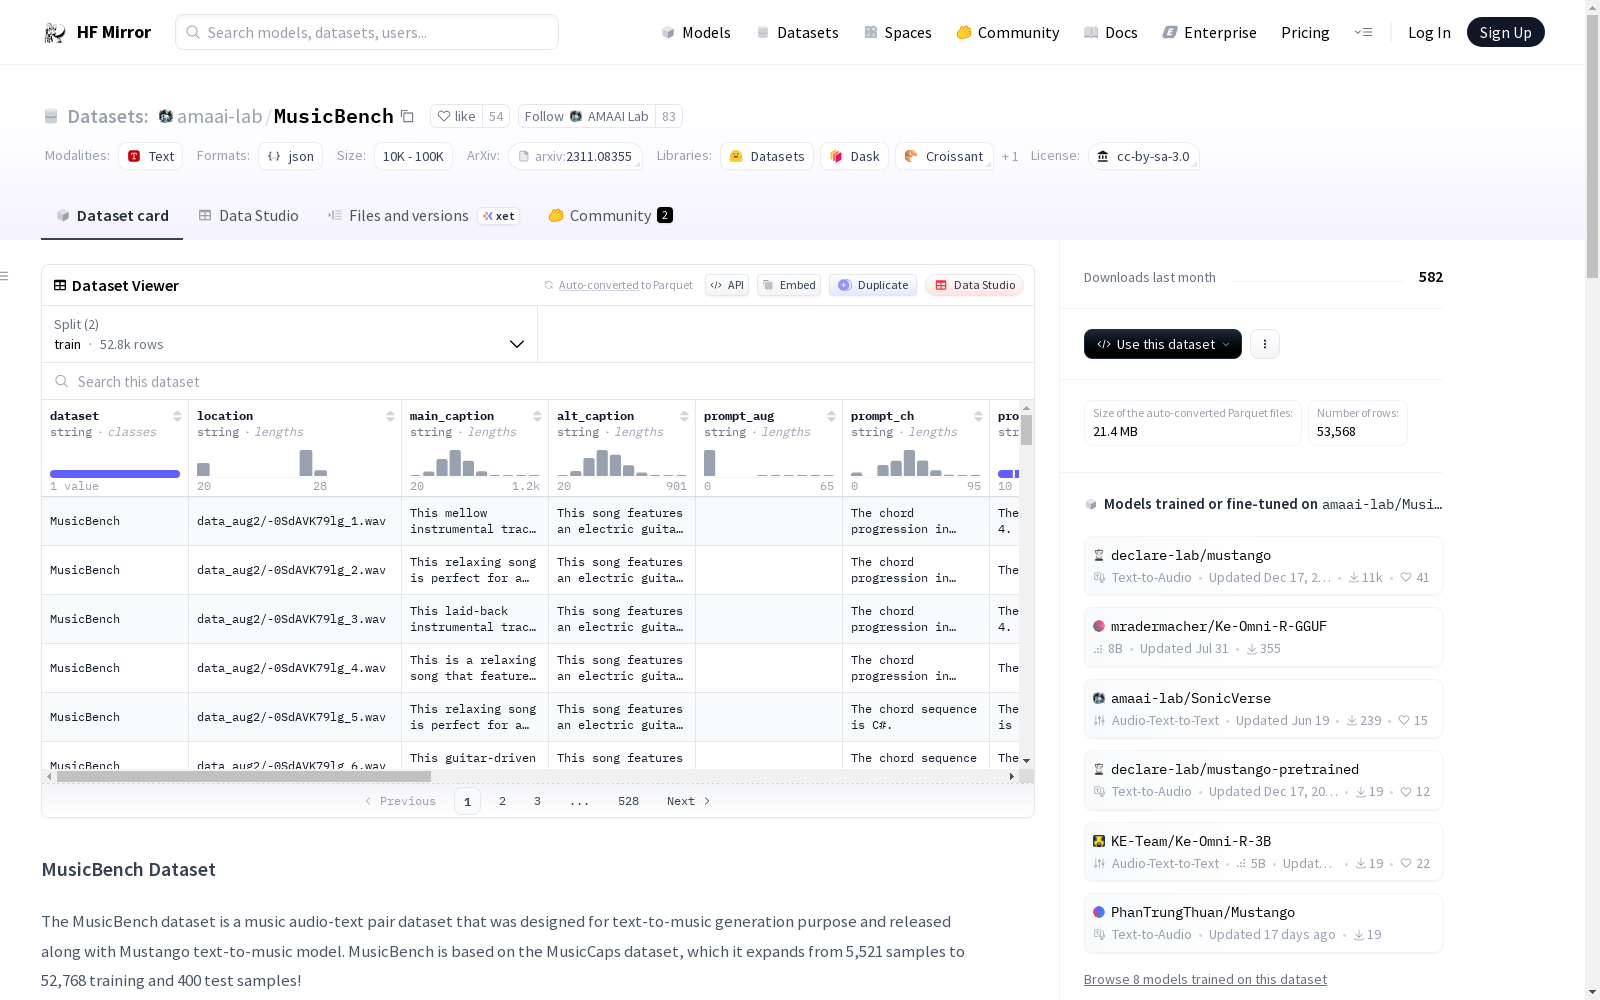
MusicBench数据集是一个音乐音频-文本配对数据集,旨在用于文本到音乐的生成任务。它基于MusicCaps数据集,通过添加音乐特征(如和弦、节拍、速度和调性)并使用文本模板描述这些特征,从而增强了原始文本提示。此外,数据集通过进行音乐上有意义的增强(如半音调音、速度变化和音量变化)扩展了音频样本的数量。训练集包含52,768个样本,测试集包含400个样本。数据集包含3个JSON文件和附带的音频文件(.tar.gz格式)。训练集包含音频增强样本和增强的标题,还提供了ChatGPT重新表述的标题。测试集分为TestA和TestB,TestB包含所有4种可能的控制句子,而TestA则不包含控制句子。FMACaps评估数据集由1000个样本组成,这些样本从Free Music Archive中提取,并通过伪标注生成。大多数样本长度为10秒,部分样本长度在5到10秒之间。数据集包含1000个音频文件和3个JSON文件,JSON文件的结构与MusicBench类似,但所有标题都位于“main_caption”列中。
The MusicBench dataset is a music audio-text paired dataset intended for text-to-music generation tasks. Built upon the MusicCaps dataset, it enhances the original text prompts by adding musical features such as chords, beats, tempo, and tonality, and describing these features using text templates. Additionally, the dataset expands the number of audio samples through music-meaningful augmentations, including semi-tone tuning, tempo variations, and volume changes. The training set contains 52,768 samples, while the test set includes 400 samples. The dataset includes 3 JSON files and accompanying audio files in .tar.gz format. The training set contains audio-augmented samples and enhanced captions, and also provides captions rephrased by ChatGPT. The test set is divided into TestA and TestB: TestB contains all 4 possible control sentences, whereas TestA does not include any control sentences. The FMACaps evaluation dataset consists of 1000 samples extracted from the Free Music Archive and generated via pseudo-annotations. Most samples have a duration of 10 seconds, while some samples range from 5 to 10 seconds in length. This dataset contains 1000 audio files and 3 JSON files. The structure of the JSON files is similar to that of MusicBench, but all captions are located in the "main_caption" column.
MusicBench Dataset 概述
数据集基本信息
- 名称: MusicBench Dataset
- 目的: 用于文本到音乐的生成
- 基础数据集: 基于 MusicCaps 数据集,从 5,521 样本扩展至 52,768 训练样本和 400 测试样本
数据集扩展内容
- 音乐特征提取: 包括和弦、节拍、速度和调性
- 文本描述增强: 使用文本模板描述音乐特征,增强原始文本提示
- 音频样本扩增: 通过半音音高移位、速度变化和音量变化进行音乐意义增强
数据集结构
- 训练集大小: 52,768 样本
- 测试集大小: 400 样本
- 文件格式: 包含 3 个 .json 文件和 .tar.gz 格式的音频文件
训练集详情
- 音频增强样本: 包含
- 增强标题: 包含
- ChatGPT 重述标题: 包含于所有音频样本
测试集详情
- TestA 和 TestB: 音频内容相同,但 TestB 在所有样本的标题中包含所有 4 种可能的控制句子,而 TestA 不包含控制句子
.json 文件结构
- location: 文件解压后的位置
- main_caption: 增强后的文本提示(TestB 包含控制句子,训练集包含 ChatGPT 重述标题)
- alt_caption: TestB 中不包含任何控制句子的标题
- prompt_aug: 与音量变化增强相关的控制句子
- prompt_ch: 描述和弦序列的控制句子
- prompt_bt: 描述节拍计数的控制句子
- prompt_bpm: 描述速度的控制句子
- prompt_key: 与提取的音乐调性相关的控制句子
- beats: 节拍和强拍时间戳
- bpm: 速度特征,以数字形式保存
- chords: 音轨中的和弦序列
- chords_time: 检测到的和弦时间戳
- key: 检测到的调性的根和类型
- keyprob: 检测到的调性的置信度分数
- is_audioset_eval_mcaps: 样本是否属于 Audioset (MusicCaps) 评估集
FMACaps 评估数据集
- 数据来源: 从 Free Music Archive (FMA) 提取的 1000 样本
- 数据大小: 1,000 样本
- 采样率: 16 kHz
- 文件包含: 1000 个音频文件和 3 个 .json 文件,分别包含不同控制句子的标题
数据集使用
- 训练 Mustango 模型: 使用 beats、chords 和 chords_time 作为输入
- 控制性评估: 使用 FMACaps_B 文件进行 Mustango 的控制性评估
- 音频质量客观评估: 使用 FMACaps_C 文件进行 Mustango 的音频质量客观评估