big-finance-benchmark
收藏资源简介:
BigFinanceBench Public Release 是一个用于评估金融研究智能体的基准测试数据集公开子集。其核心目标是确保金融答案的可审计性,要求智能体不仅生成数值答案,还需提供完整的工作流程轨迹,这些轨迹将根据详细的、带权重的评分标准进行评分,涵盖来源选择、周期、会计定义、假设、调整和计算等多个关键检查点。本公开版本包含从完整928项基准测试中分层抽取的50个问题,确保了在流程和难度上的代表性,使模型排名与完整集高度一致。每个数据样本包含一个唯一的稳定标识符、一个自然语言的金融研究任务查询、一个由专家撰写的参考答案,以及一个有序的评分标准数组。每条评分标准都包含描述文本和整数权重分值,最终得分通过累计获得分数除以问题总可能分数计算。数据集规模为50个问题,共包含793条评分标准线和1,931个评分点,平均每个问题有15.86条评分标准和38.62个评分点。此外,该发布还附带了多个前沿大模型在这些问题上的工作轨迹文件(包含工具使用和中间输出)以及由法官模型生成的评分结果。该数据集适用于开放领域问答、文本生成、智能体工作流评估、金融研究工具使用验证等任务,旨在推动可审计、可靠的金融分析智能体的发展。
The BigFinanceBench Public Release is a public subset of the benchmark dataset for evaluating financial research AI Agents. Its core objective is to ensure the auditability of financial answers, requiring AI Agents to not only generate numerical answers but also provide complete workflow traces. These traces will be scored against detailed, weighted scoring rubrics covering multiple key checkpoints including source selection, time periods, accounting definitions, assumptions, adjustments, and calculations. This public release includes 50 questions sampled via stratified sampling from the complete 928-item benchmark set, ensuring representativeness in terms of workflow and difficulty, such that model rankings align highly with those of the full dataset. Each data sample contains a unique stable identifier, a natural language financial research task query, an expert-written reference answer, and an ordered array of scoring rubrics. Each scoring rubric includes a descriptive text and an integer weight score. The final score is calculated by dividing the accumulated earned points by the total possible points for the corresponding question. The dataset comprises 50 questions in total, containing 793 scoring rubric lines and 1,931 scoring points, with an average of 15.86 scoring rubrics and 38.62 scoring points per question. In addition, this release also provides workflow trace files (including tool usage and intermediate outputs) for multiple cutting-edge large language models (LLMs) on these questions, as well as scoring results generated by judge models. This dataset is applicable to tasks such as open-domain question answering, text generation, AI Agent workflow evaluation, and validation of financial research tool usage, aiming to promote the development of auditable and reliable financial analysis AI Agents.
数据集概述
BigFinanceBench 是一个用于评估金融研究智能体(agent)工作流的基准测试数据集。其核心在于不仅评估智能体生成的最终数字答案,还通过基于点数的评分细则(point-weighted rubric)对其整个推理过程(包括来源选择、时间段、会计定义、假设、调整和计算)进行评分,以确保结果的可审计性。
基本信息
- 语言: 英语
- 许可证: CC BY 4.0
- 领域: 金融
- 任务: 问答、文本生成 (开放域问答)
- 数据集大小: 小于1K样本
- 数据来源: 原始创作
数据规模与版本
- 本次发布的是 BigFinanceBench 完整基准测试(928个问题)的一个 50个问题的分层子集。
- 该子集根据工作流和难度四分位数进行分层,使得模型排名与完整928问题集高度一致(Kendalls tau = 0.956)。
- 完整的基准测试项被保留,以减轻基准污染并保持评估有效性。
- 数据集统计:
- 总样本数: 50
- 总评分细则行数: 793行
- 总评分点数: 1,931点
- 平均每个问题: 15.86行评分细则, 38.62点
数据格式与字段
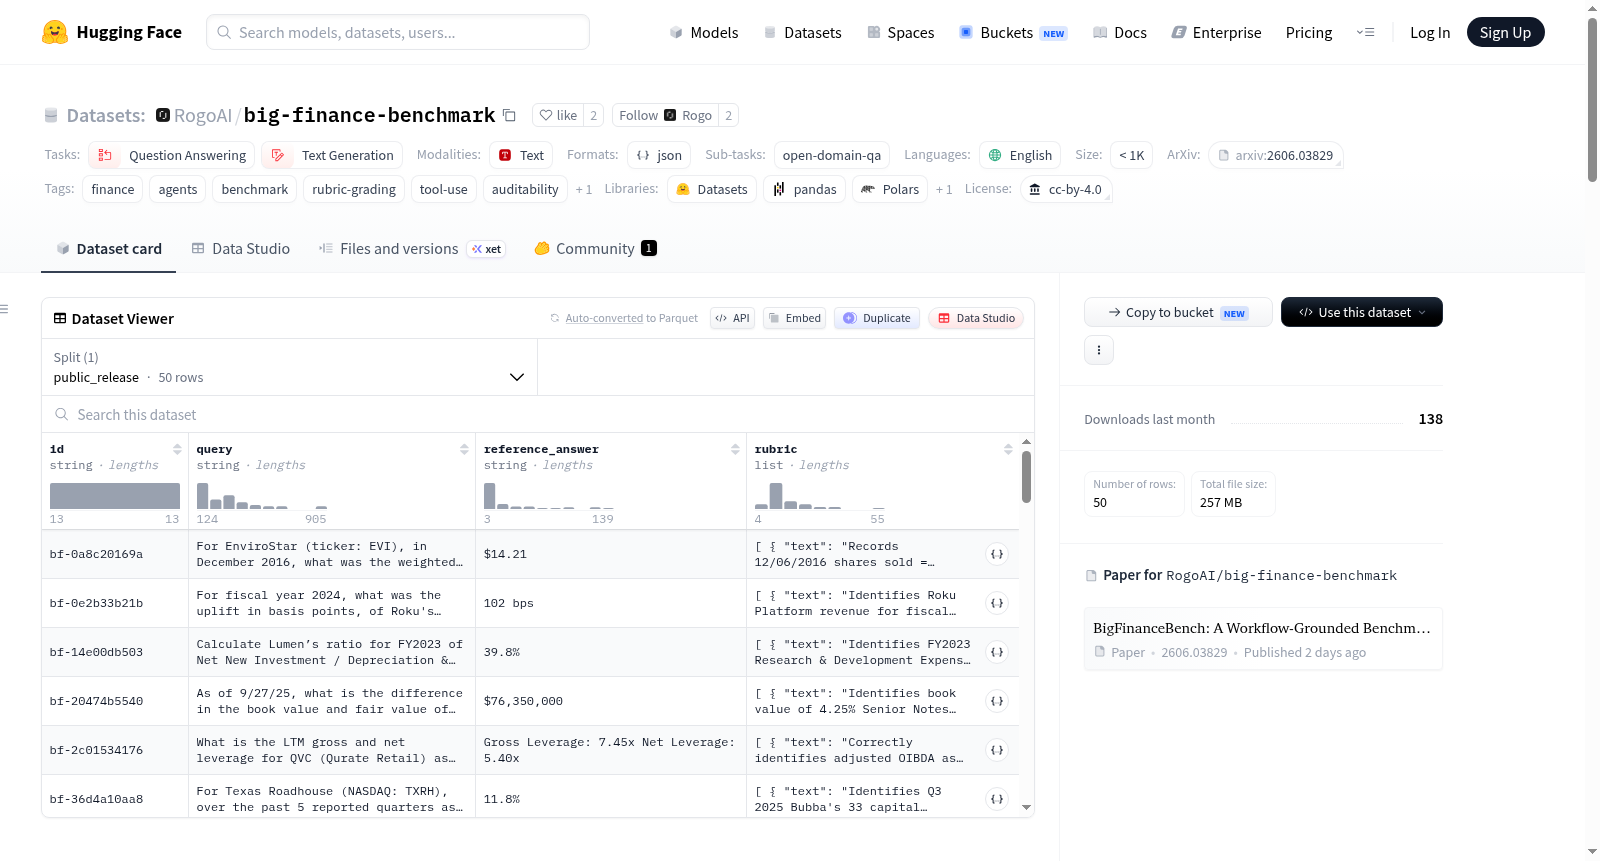
数据集以 JSONL 文件 (big_finance_subset.jsonl) 格式提供,每行包含一个基准测试项,包含以下字段:
id: 稳定的问题标识符。query: 自然语言的金融研究任务。reference_answer: 专家撰写的参考答案。rubric: 有序的评分检查点数组。每个条目是一个独立的评分细则行,包含:text(字符串): 对答案或推理轨迹的要求描述。points(整数): 该检查点的分值权重。
评分示例: json { "id": "bf-0a8c20169a", "query": "For EnviroStar (ticker: EVI), in December 2016...", "reference_answer": "$14.21", "rubric": [ {"text": "Records 12/06/2016 shares sold = 32,476.", "points": 1}, {"text": "Calculates weighted average sale price = $14.21 per share, when rounded to the nearest cent.", "points": 10} ] }
文件结构
big_finance_subset.jsonl: 包含50个公开基准测试项。traces/: 包含模型在被评估问题上的运行轨迹(包括工具调用、工具输出、最终答案和运行元数据)。grades/: 包含对上述轨迹的评判结果,包括最终答案正确性和每个细则行的得分。
模型与评判
- 已评估模型: GPT-5.5, GPT-5.4 Mini, Claude Opus 4.7, Claude Sonnet 4.6, Gemini 3.1 Pro Preview, Gemini 3 Flash Preview, Gemma 4 31B, GLM-5.1, Kimi K2.6, Qwen3.6 27B。
- 评判模型: Gemini 3.1 Pro Preview, Claude Opus 4.7。
其他信息
- 维护方: 由 Rogo 维护。
- 联系方式: alexwang@rogo.ai, georg@rogo.ai。
- 相关链接:
- arXiv 论文:
https://arxiv.org/abs/2606.03829 - 项目网站:
https://bigfinancebench.com/ - GitHub 仓库:
https://github.com/Rogo-Technologies/big-finance-benchmark - 博客文章:
https://rogo.ai/news/introducing-the-big-finance-benchmark
- arXiv 论文: