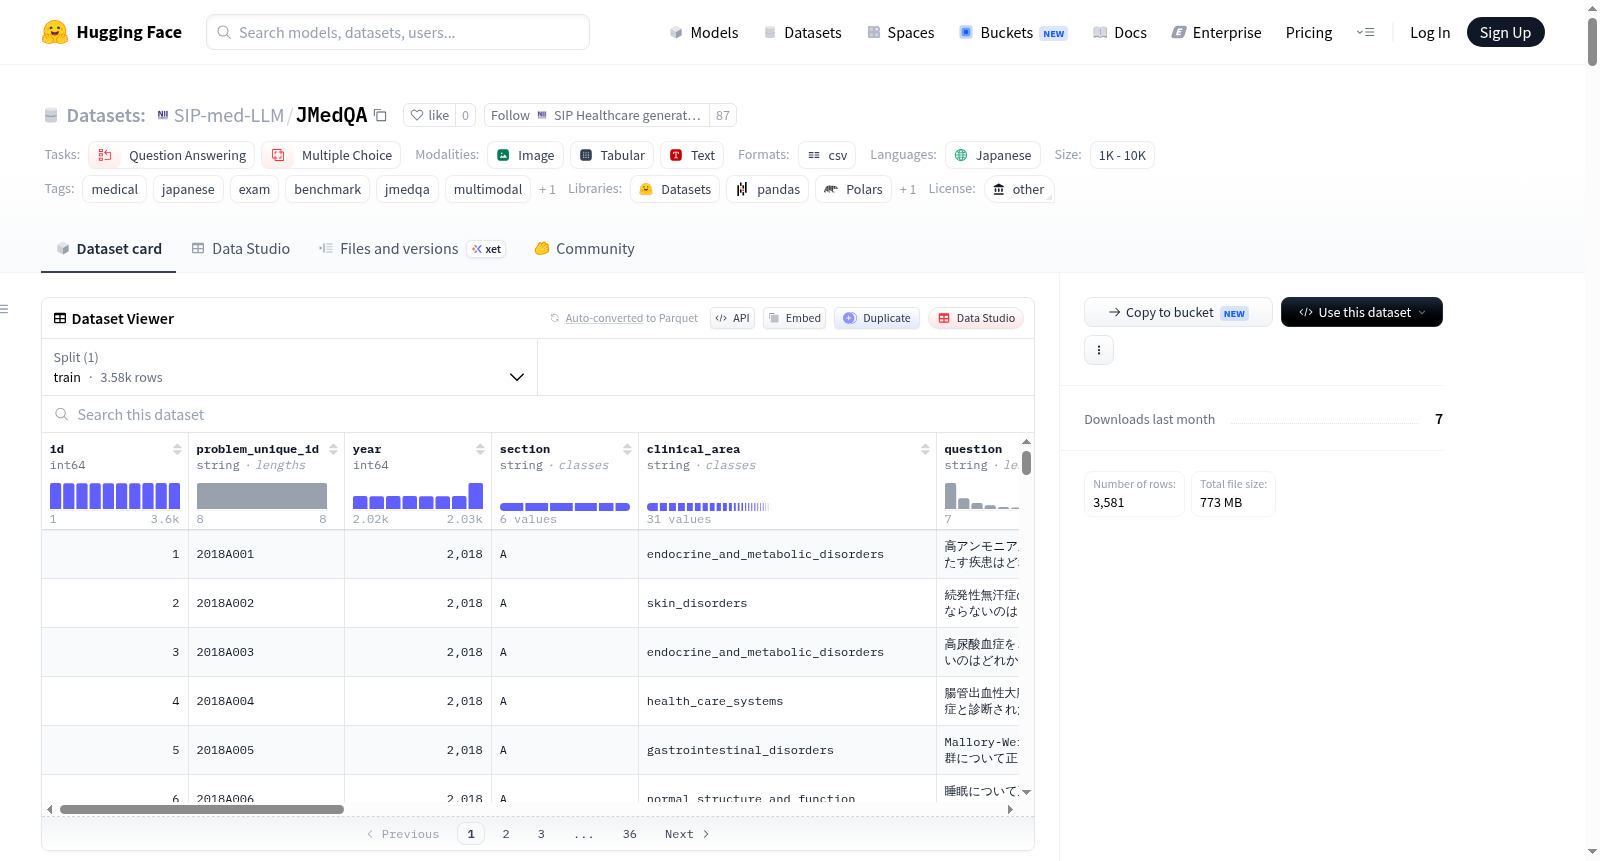
SIP-med-LLM/JMedQA
收藏资源简介:
JMedQA是一个基于日本厚生劳动省公开的医師国家試験资料构建的日语医学问答基准数据集,旨在评估大语言模型和视觉语言模型在医学领域的性能。数据集包含2018年至2026年的3581个问题,主要形式为多项选择题,少数为数值答案问题。每个问题提供结构化文本数据(如问题文本、选项、答案)和相关图像(PNG格式),并标注了图像依赖程度(如“无依赖”、“文本足够”、“文本不足”等),以支持不同评估设置(如纯文本评估、多模态评估)。数据集还包括元数据(如临床领域、年份、链接问题标志),并经过预处理以确保独立评估。图像路径通过JSON映射,部分图像因未公开而包含通知图像。数据集的统计信息包括问题类型分布、图像依赖分布和年度分布,适用于医学AI研究和模型基准测试。
JMedQA is a Japanese medical question answering benchmark dataset constructed using publicly available materials from the National Physician Licensing Examination released by the Ministry of Health, Labour and Welfare (MHLW) of Japan, designed to evaluate the performance of Large Language Models (LLMs) and Vision-Language Models (VLMs) in the medical domain. This dataset comprises 3581 questions spanning from 2018 to 2026, most of which are multiple-choice questions, with a small portion being numerical answer questions. Each question is paired with structured textual data (including question text, options, and correct answer) and associated PNG-format images, and is annotated with image dependency levels such as "no image dependency", "sufficient text only", and "insufficient text without images" to support diverse evaluation settings like text-only evaluation and multimodal evaluation. The dataset also includes metadata such as clinical domain, question year, and linked question flag, and has been preprocessed to ensure independent model evaluation. Image paths are mapped via JSON files, and some images are replaced with notification images as they are not publicly available. Its statistical summaries cover the distribution of question types, image dependency levels, and annual question distribution, making it suitable for medical AI research and model benchmarking.