biomap-research-ssp_q3
收藏资源简介:
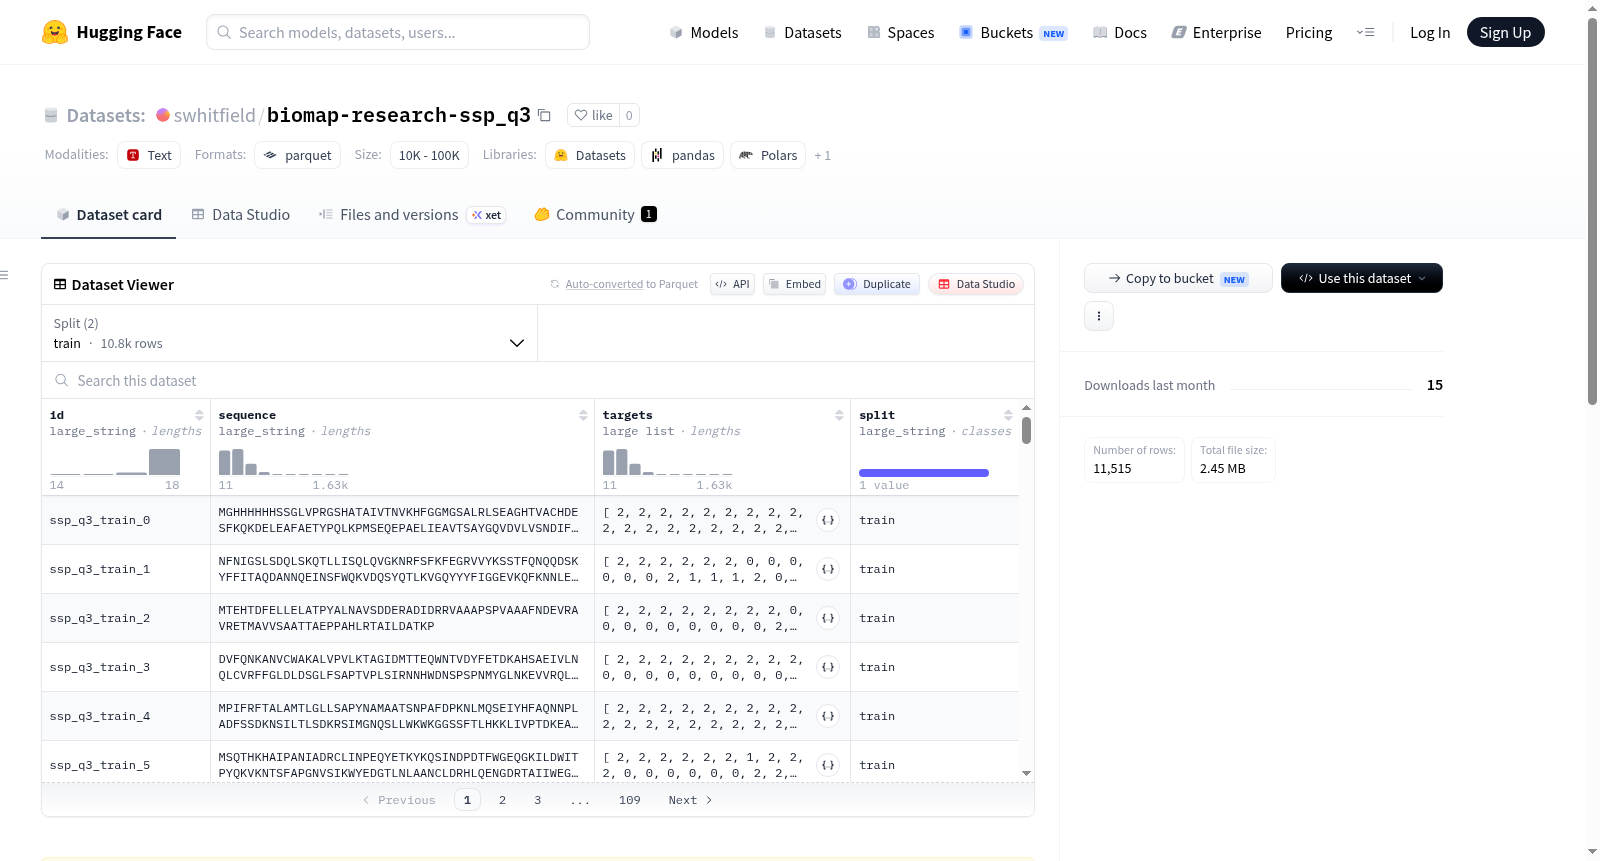
该数据集名为ssp_q3,源自biomap-research/ssp_q3,已适配Hugging Face数据集库使用。数据以Parquet文件格式存储,遵循标准分割命名约定,包含训练集、验证集和测试集。预处理模式为minimal,未应用最大序列长度过滤。数据规模方面,训练集包含10848行,测试集包含667行,验证集行数未明确说明。但数据集的具体内容、字段结构、背景目的、适用任务等信息在README中未提供,因此无法进一步详细描述。
The dataset named ssp_q3 originates from biomap-research/ssp_q3 and has been adapted for use with the Hugging Face datasets library. The data is stored in Parquet file format, following the standard split naming convention and includes training, validation, and test sets. The preprocessing mode is minimal without applying maximum sequence length filtering. In terms of data scale, the training set contains 10,848 rows, the test set contains 667 rows (the number of rows in the validation set is not explicitly stated). However, specific details such as content, field structure, background purpose, and applicable tasks are not provided in the README, so further detailed description is unavailable.
数据集概述:ssp_q3
数据来源
该数据集源自 biomap-research/ssp_q3,并经过处理以适配 Hugging Face 数据集的使用格式。
数据文件
- 数据以 Parquet 格式存储,位于
data/目录下。 - 文件命名遵循 Hugging Face 的数据集拆分约定,包括
train-*、validation-*、test-*等命名模式。
预处理说明
- 预处理模式为
minimal(最小化处理)。 - 未应用最大序列长度过滤。
数据集拆分及大小
| 数据拆分 | 行数 |
|---|---|
| test | 667 |
| train | 10848 |
加载方式
可通过 Hugging Face 的 datasets 库加载数据集,代码如下:
python
from datasets import load_dataset
ds = load_dataset("<owner>/<repo>") print(ds)