MultiFinBen-JapaneseOCR
收藏资源简介:
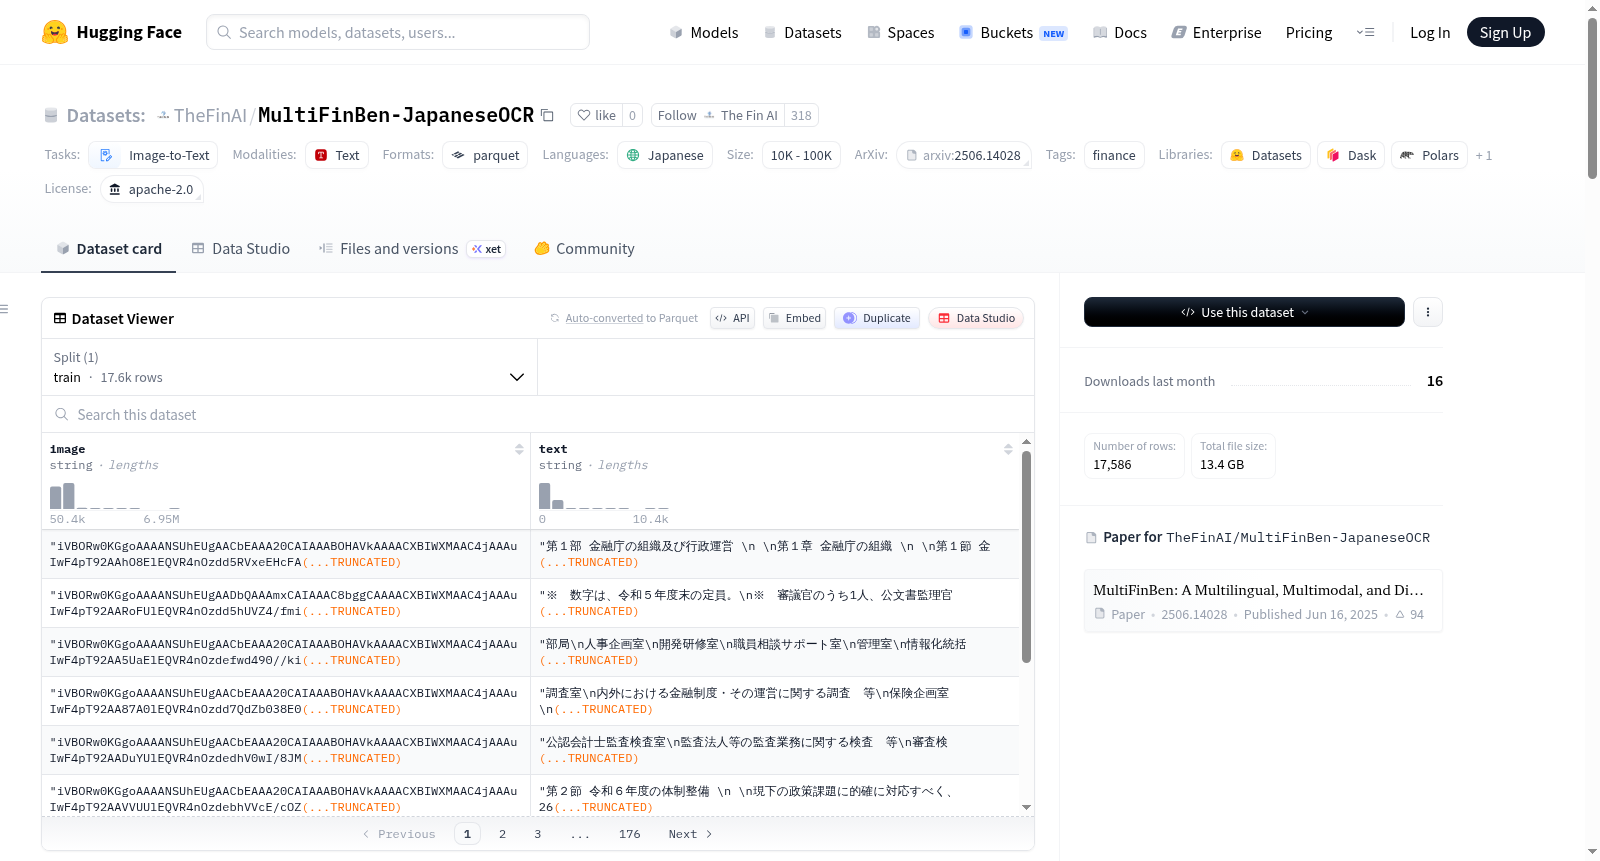
JapaneseOCR 数据集包含来自日本金融厅(FSA)白皮书的图像,用于评估大型语言模型在将非结构化文档(如PDF和图像)转换为机器可读格式方面的能力,特别是在金融领域。该数据集适用于图像到文本的任务,评估指标为ROUGE-1。数据集结构包括两个字段:image(Base64编码的PNG图像,代表PDF的一页)和text(从PDF文件中提取的文本)。数据集创建过程涉及收集、拆分和转换日本金融厅的公开监管文件,并通过Python OCR包fitz生成真实文本。数据集不包含个人身份信息(PII),仅限于日语监管数据。使用该数据集时需注意其可能存在的偏见和局限性,如数据来源仅限于证券市场监管文件,可能缺乏其他金融文档类型的多样性。数据集采用Apache License 2.0许可。
The JapaneseOCR dataset comprises images sourced from the white papers of Japan’s Financial Services Agency (FSA), and is designed to evaluate the capability of Large Language Models (LLMs) in converting unstructured documents such as PDFs and images into machine-readable formats, with a focus on the financial domain. This dataset is tailored for image-to-text tasks, using ROUGE-1 as the evaluation metric. The dataset structure includes two fields: `image` (Base64-encoded PNG images representing a single page of a PDF document) and `text` (text extracted from the corresponding PDF file). The dataset creation workflow involves collecting, splitting and converting publicly released regulatory documents from the Japanese FSA, and generating ground truth text via the Python OCR package fitz. The dataset contains no personally identifiable information (PII) and is restricted to Japanese regulatory data. When using this dataset, users should be mindful of its potential biases and limitations: for example, the data is only sourced from securities market regulatory documents, which may lack diversity across other types of financial documents. This dataset is licensed under the Apache License 2.0.
MultiFinBen-JapaneseOCR 数据集概述
数据集基本信息
- 数据集名称: JapaneseOCR (MultiFinBen-JapaneseOCR)
- 发布者: The FinAI Team
- 许可协议: Apache License 2.0
- 主要语言: 日语 (ja)
- 数据规模: 10K < n < 100K
- 任务类别: 图像到文本 (image-to-text)
- 领域标签: 金融 (finance)
数据集内容与结构
数据摘要
该数据集包含源自日本金融厅(FSA)白皮书的图像,用于基准测试和评估大型语言模型在将非结构化文档(如PDF和图像)转换为机器可读格式方面的能力,特别是在转换任务更为复杂且具有价值的金融领域。
数据实例与字段
数据集包含13,320个训练样本。每个实例包含2个字段:
- image: 监管文档的图像,每张图像代表PDF中的一页。数据类型为字符串,存储的是Base64编码的PNG图像。
- text: 从监管文档中提取的真实文本。
数据文件
- 训练集路径:
data/*.parquet - 下载大小: 11,661,151,472 字节
- 数据集大小: 11,860,671,915 字节
数据集创建
来源与构建
- 数据来源: 来自日本金融厅(FSA)公开的证券市场监管文档。官方网址为:https://www.fsa.go.jp/en/。
- 构建过程: 下载PDF文件,通过API分割为每页一个文件,并转换为图像。
- 标注过程: 真实文本的标注是使用Python OCR包
fitz(PyMuPDF) 完成的。数据集源于公开可用的监管文档,未涉及外部标注团队。
个人与敏感信息
该数据集不包含任何个人身份信息(PII),严格专注于日语监管数据,不存在个人或敏感信息。
使用考量
支持的任务与评估
- 主要任务: 图像到文本转换。
- 评估指标: ROUGE-1。
社会影响
该数据集使AI模型能够从日语的扫描金融文档中提取结构化信息,支持日语地区金融、监管和透明度倡议的下游应用。通过将页面级PDF图像与准确的真实文本对齐,支持开发跨不同格式和语言工作的更公平、更具包容性的模型。
已知局限性与偏差
- 来源偏差: 源数据仅限于证券市场的监管文档,可能未能充分代表其他金融文档类型(如税务记录、银行对账单或私营公司报告),可能限制模型的泛化能力。
- 标注限制: 真实文本是使用Python包fitz (PyMuPDF) 提取的,在复杂布局中可能引入不准确性,可能影响训练质量和评估可靠性。
- 多样性限制: 虽然数据集涵盖监管文档,但可能在布局风格上缺乏足够的多样性(例如,手写笔记、非标准财务表格、嵌入式图表),这可能限制模型对结构化程度较低或非常规金融文档的泛化能力。
附加信息
维护者
- Yueru He
- Ruoyu Xiang
- The FinAI Team
引用信息
如果使用此数据集,请引用: bibtex @misc{peng2025multifinbenmultilingualmultimodaldifficultyaware, title={MultiFinBen: A Multilingual, Multimodal, and Difficulty-Aware Benchmark for Financial LLM Evaluation}, author={Xueqing Peng and Lingfei Qian and Yan Wang and Ruoyu Xiang and Yueru He and Yang Ren and Mingyang Jiang and Jeff Zhao and Huan He and Yi Han and Yun Feng and Yuechen Jiang and Yupeng Cao and Haohang Li and Yangyang Yu and Xiaoyu Wang and Penglei Gao and Shengyuan Lin and Keyi Wang and Shanshan Yang and Yilun Zhao and Zhiwei Liu and Peng Lu and Jerry Huang and Suyuchen Wang and Triantafillos Papadopoulos and Polydoros Giannouris and Efstathia Soufleri and Nuo Chen and Guojun Xiong and Zhiyang Deng and Yijia Zhao and Mingquan Lin and Meikang Qiu and Kaleb E Smith and Arman Cohan and Xiao-Yang Liu and Jimin Huang and Alejandro Lopez-Lira and Xi Chen and Junichi Tsujii and Jian-Yun Nie and Sophia Ananiadou and Qianqian Xie}, year={2025}, eprint={2506.14028}, archivePrefix={arXiv}, primaryClass={cs.CL}, url={https://arxiv.org/abs/2506.14028}, }