OpenRubrics/RubricARROW-Judge-SFT
收藏资源简介:
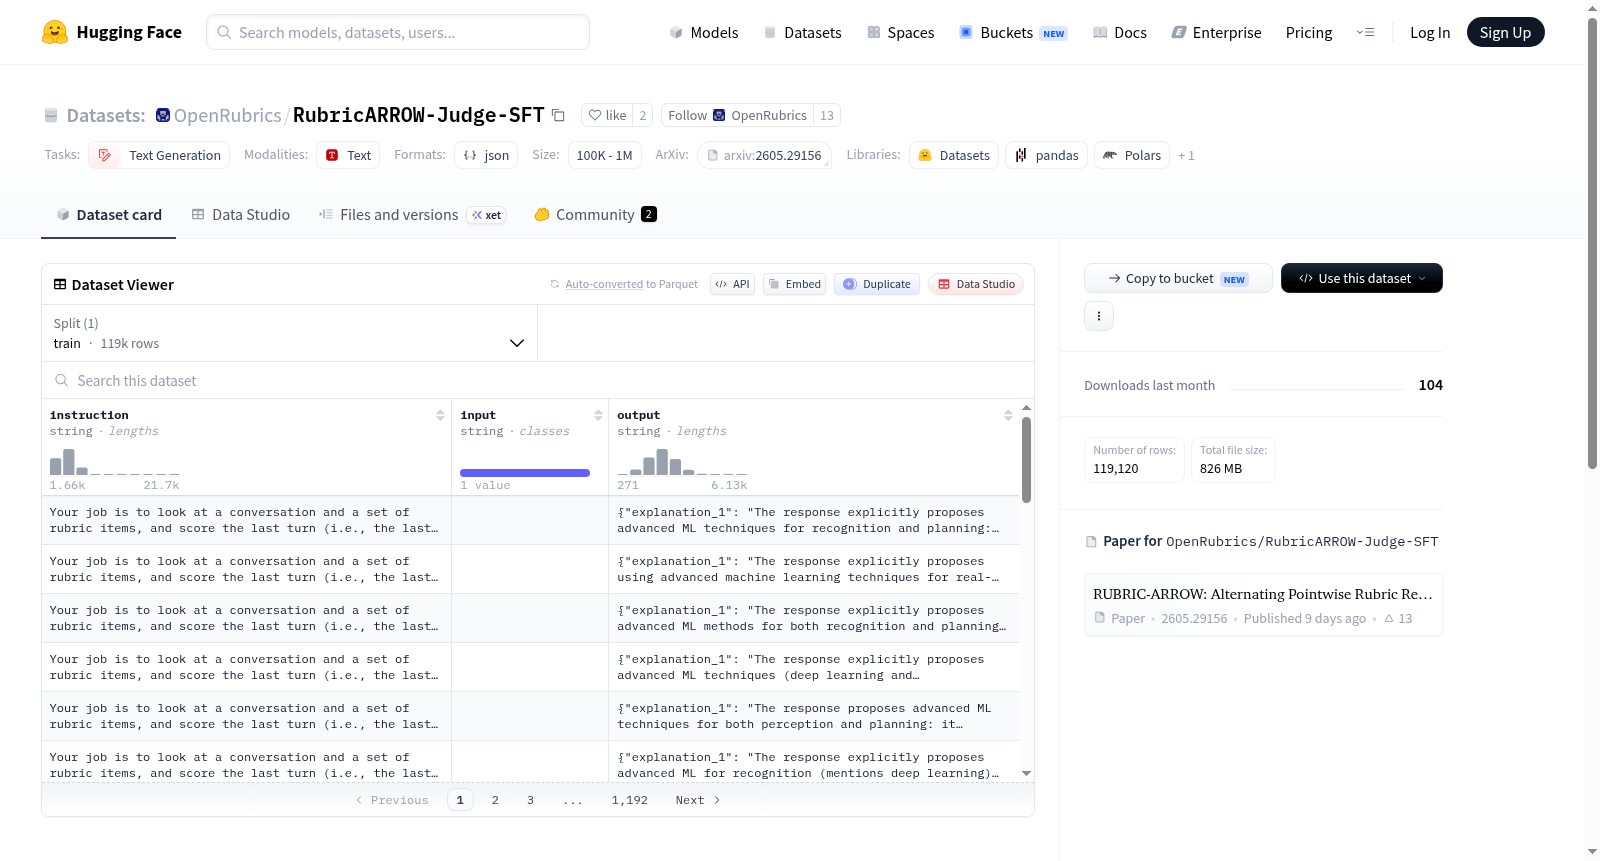
该数据集用于RUBRIC-ARROW SFT训练,具体为RubricARROW判断模型的监督微调(SFT)训练数据。数据以指令调优风格格式化,每个示例包含指令(instruction)、输入(input)和输出(output)字段,适用于文本生成任务。数据集基于论文《RUBRIC-ARROW: Alternating Pointwise Rubric Reward Modeling for LLM Post-training in Non-verifiable Domains》提出,旨在支持在不可验证领域的大语言模型后训练。
This dataset is intended for RUBRIC-ARROW SFT training, specifically serving as the supervised fine-tuning (SFT) data for the RubricARROW judgment model. The data is formatted in the instruction-tuning style, where each example includes three fields: instruction, input, and output, making it applicable to text generation tasks. This dataset is proposed based on the paper titled "RUBRIC-ARROW: Alternating Pointwise Rubric Reward Modeling for LLM Post-training in Non-verifiable Domains", and it aims to support post-training of large language models in non-verifiable domains.