
WatsonxQA (ProductDocs)
收藏资源简介:
该数据集由IBM Research收集,用于研究检索增强生成(RAG)超参数优化。这是一个基于企业产品文档的新开源数据集,包含从1144页HTML产品文档生成的5534个子文档。数据集包括75个问答对和金标准文档标签,其中25个由两位主题专家生成,其余的则是通过合成并经过两位作者的手动过滤和审查。这些数据集在许多方面都表现出多样性,它们代表不同的领域——研究论文、生物医学文档、维基百科页面和企业数据。它们在问题和答案长度上也有所不同;例如,MiniWiki的答案相对较短,而ClapNQ是专门为具有长答案而构建的。语料库的大小也各不相同,反映了在小型或大型文档集上的真实世界检索场景。每个基准数据集都被分为开发和测试集。为了使计算可行,大型基准数据集(BioASQ和ClapNQ)中的问题数量被限制为开发和测试分别为1000和150。
This dataset was collected by IBM Research for research on retrieval-augmented generation (RAG) hyperparameter optimization. It is a new open-source dataset based on enterprise product documentation, containing 5,534 sub-documents generated from 1,144 pages of HTML product documents. The dataset includes 75 question-answer pairs and gold-standard document labels, of which 25 were generated by two subject matter experts, while the remaining samples were synthesized and manually filtered and reviewed by two authors. The dataset exhibits diversity across multiple dimensions, covering various domains including research papers, biomedical documents, Wikipedia pages, and enterprise data. It also varies in the lengths of questions and answers; for example, MiniWiki features relatively short answers, while ClapNQ is specifically designed for long-form answers. The sizes of the corpora also differ, reflecting real-world retrieval scenarios across both small and large document collections. Each benchmark dataset is split into development and test sets. To ensure computational feasibility, the number of questions in the large benchmark datasets (BioASQ and ClapNQ) is limited to 1,000 for the development set and 150 for the test set, respectively.
watsonxDocsQA 数据集概述
基本信息
- 许可证: Apache-2.0
- 数据集地址: https://huggingface.co/datasets/ibm-research/watsonxDocsQA
数据集组成
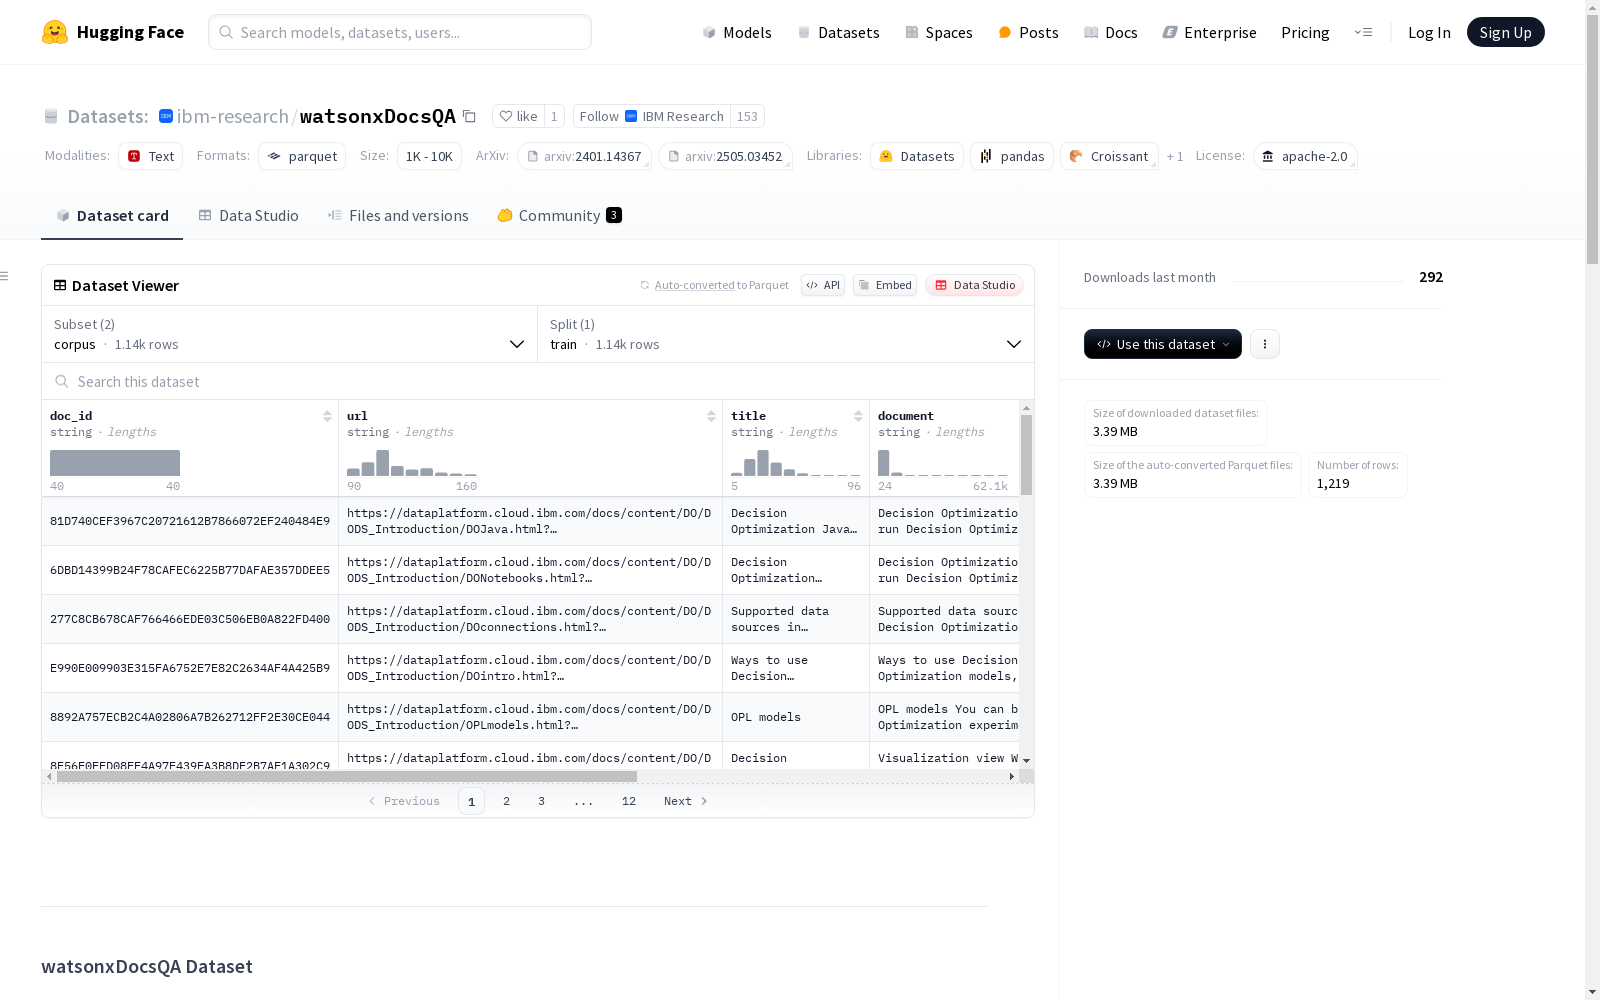
1. 语料库数据集 (corpus)
- 数据文件:
corpus/train-* - 特征:
doc_id: 文档唯一标识符url: 文档来源URLtitle: 文档标题document: 文档内容的文本表示md_document: 文档内容的Markdown表示
- 统计信息:
- 训练集大小: 10,625,185字节
- 训练集样本数: 1,144
- 下载大小: 3,327,056字节
- 数据集大小: 10,625,185字节
2. 问答数据集 (question_answers)
- 数据文件:
- 训练集:
question_answers/train-* - 测试集:
question_answers/test-*
- 训练集:
- 特征:
question_id: 问题唯一标识符question: 问题文本correct_answer: 正确答案correct_answer_document_ids: 正确答案文档ID列表ground_truths_contexts: 答案基于的上下文文本列表
- 统计信息:
- 训练集大小: 60,268字节,45个样本
- 测试集大小: 33,340字节,30个样本
- 下载大小: 58,074字节
- 数据集大小: 93,608字节
数据来源与构建方法
- 语料库来源: 企业产品文档(爬取自2024年3月的主页)
- 问答对构建:
- 25个问题: 由两位领域专家人工生成
- 50个问题: 使用
tiiuae/falcon-180b模型合成生成,并经过人工筛选和质量审查
引用信息
bibtex @misc{orbach2025analysishyperparameteroptimizationmethods, title={An Analysis of Hyper-Parameter Optimization Methods for Retrieval Augmented Generation}, author={Matan Orbach and Ohad Eytan and Benjamin Sznajder and Ariel Gera and Odellia Boni and Yoav Kantor and Gal Bloch and Omri Levy and Hadas Abraham and Nitzan Barzilay and Eyal Shnarch and Michael E. Factor and Shila Ofek-Koifman and Paula Ta-Shma and Assaf Toledo}, year={2025}, eprint={2505.03452}, archivePrefix={arXiv}, primaryClass={cs.CL}, url={https://arxiv.org/abs/2505.03452}, }
联系方式
- 邮箱: benjams@il.ibm.com
- 讨论区: 可在数据集仓库中提交pull request或发起讨论
- 1An Analysis of Hyper-Parameter Optimization Methods for Retrieval Augmented GenerationIBM Research · 2025年


