kwcluster-variables
收藏资源简介:
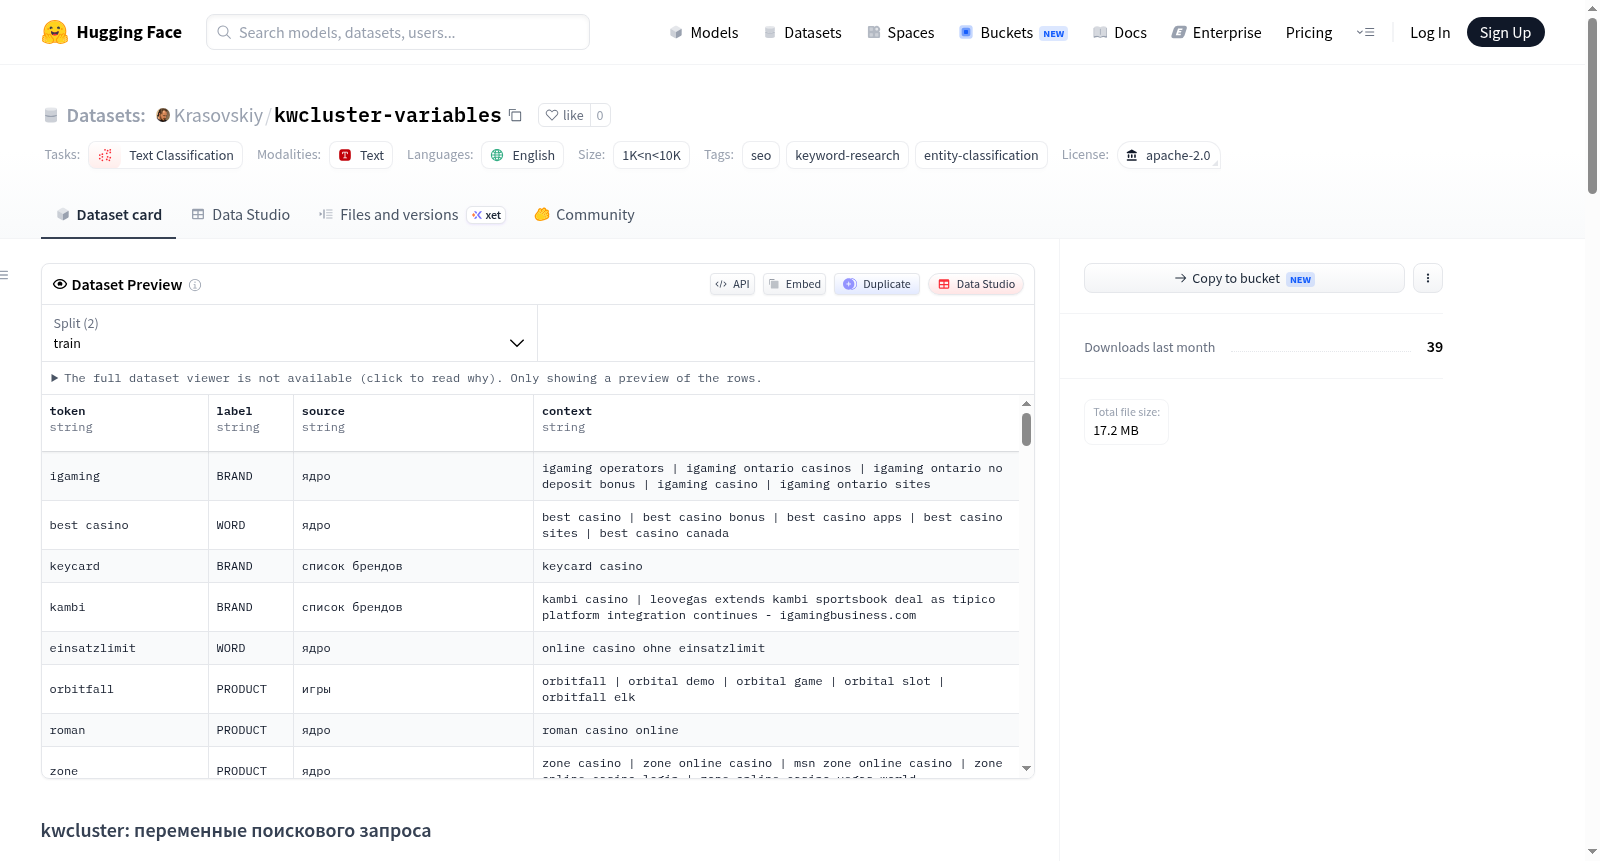
该数据集名为kwcluster,用于搜索查询中单词的角色分类。每个单词被标记为以下类别之一:公司名称、游戏、支付方式、区域、条件或普通词。标记回答的问题是:该单词是否应为网站上的独立页面设置。数据集主要用于语义聚类工具[kwcluster]和基于其训练的模型[Krasovskiy/kwcluster-variables-1.5b]。数据格式为JSON,包含token(单词)、label(标签)、source(来源,如手动标注、验证事实等)和context(上下文,最多五个相关查询,以竖线分隔)。上下文是必需的,因为单词在脱离查询时含义不明。数据集包含多个文件:train.jsonl(6811行,训练集)、test_frequent_words.jsonl(45行,高频词测试集)、test_rest.jsonl(1156行,其余测试集)、top300_hand_labeled.jsonl(300行,手动标注的高频词)、providers.txt(71个游戏工作室)、payment-methods.json(48种支付方式)、aglc-operators.json(53个阿尔伯塔监管机构运营商)。数据按单词划分,一个单词完整属于训练集或测试集。README强调了三项重要事项:1)训练样本的类别分布必须反映真实搜索查询分布,其中普通词约占82%,否则会导致模型误判;2)高频词(前300个)覆盖了80%的查询,其标注质量至关重要,因此手动标注了300个高频词并修正了118个错误;3)测试集上的指标不能反映真实行为,因为指标平等对待所有单词,而实际效果由少数高频词决定。标签来源包括手动标注(300个高频词,在真实查询上下文中标注)、已验证事实(如运营商网站地图中的游戏目录、许可证号、阿尔伯塔监管机构注册表、国家字典)以及一个语料库(1100万查询观察,86247个唯一查询,129个国家,半年数据)。数据集的局限性:支付方式和条件类别样本较少(55和38个),多语言(如德语、西班牙语)导致这些类别难以衡量,实际项目中支付方式通过参考表而非模型处理;仅覆盖赌场领域,主要为英语;除高频词外,标签并非人工确认,但字段source说明了来源。
The dataset is called kwcluster and is used for classifying the role of words in search queries. Each word is labeled with one of the following categories: company name, game, payment method, region, condition, or common word. The dataset answers the question: should the word be a separate page on the website? It is primarily used for the semantic clustering tool [kwcluster] and the model trained on it [Krasovskiy/kwcluster-variables-1.5b]. The data format is JSON, containing token (word), label (tag), source (origin, e.g., manual labeling, verified facts, etc.), and context (up to five related queries, separated by vertical bars). Context is required because words are ambiguous without queries. The dataset includes multiple files: train.jsonl (6811 rows, training set), test_frequent_words.jsonl (45 rows, high-frequency word test set), test_rest.jsonl (1156 rows, remaining test set), top300_hand_labeled.jsonl (300 rows, manually labeled high-frequency words), providers.txt (71 game studios), payment-methods.json (48 payment methods), aglc-operators.json (53 Alberta regulated operators). Data is split by word, with each word fully belonging to training or test set. The README emphasizes three important points: 1) The class distribution of training samples must reflect the real search query distribution, where common words account for about 82%, otherwise the model will misclassify; 2) High-frequency words (top 300) cover 80% of queries, so their labeling quality is crucial; thus 300 high-frequency words were manually labeled and 118 errors were corrected; 3) Metrics on the test set do not reflect real behavior because they treat all words equally, while actual performance is determined by a few high-frequency words. Label sources include manual labeling (300 high-frequency words, labeled in real query context), verified facts (e.g., game directories from operator site maps, license numbers, Alberta regulator registry, country dictionary), and a corpus (11 million query observations, 86,247 unique queries, 129 countries, half a year). Limitations: The payment method and condition categories have few samples (55 and 38), and multilingualism (e.g., German, Spanish) makes these categories difficult to measure; in practice, payment methods are handled via reference tables rather than the model; only covers the casino domain, mostly in English; except for high-frequency words, labels are not human-confirmed, but the source field indicates the origin.
数据集概述:kwcluster-variables
基本信息
- 许可证:Apache-2.0
- 语言:英语
- 任务类型:文本分类
- 标签:SEO、关键词研究、实体分类
- 数据规模:1K<n<10K 条样本
数据集内容
该数据集包含搜索查询中的词语及其角色分类,标签包括:公司名称、游戏、支付方式、地区、优惠条件或普通词汇。每条数据包含词语(token)、标签(label)、来源(source)及上下文(context),格式为 JSON。
| 文件 | 行数 | 说明 |
|---|---|---|
| train.jsonl | 6811 | 训练集 |
| test_frequent_words.jsonl | 45 | 高频词测试集 |
| test_rest.jsonl | 1156 | 其余测试集 |
| top300_hand_labeled.jsonl | 300 | 手工标注的高频词 |
| providers.txt | 71 | 工作室/开发商列表 |
| payment-methods.json | 48 | 支付方式列表 |
| aglc-operators.json | 53 | 阿尔伯塔监管机构运营商注册表 |
数据按词语划分,同一词语不会同时出现在训练集和测试集中。
标签来源
- 手工标注:高频词300个,根据真实查询上下文进行标注
- 可验证事实:来自网站地图中的游戏目录、许可证注册表、阿尔伯塔监管机构注册表、国家/地区参考
- 语料库:1100 万条搜索查询观测数据,86,247 条唯一查询,覆盖 129 个国家,跨度半年
重要注意事项
- 普通词汇在真实搜索查询中约占82%,数据集需反映这一分布
- 高频词对结果影响极大:前50个词涉及66%的关键词,前300个涉及80%
- 传统评估指标可能具有欺骗性,必须结合实际工具运行效果进行评估
数据集局限性
- 支付方式和优惠条件的样本较少(55和38条)
- 仅覆盖单一领域(赌场),主要使用英语
- 除高频词外,标签为推断而非人工确认,
source字段标明来源
附带资源
该仓库还包含完整的语义聚类工具,包括代码模块、参考表(监管机构、支付系统、国家、游戏类型等)、实验记录、分组基准数据集及正负样本对(16,219 和 36,090 对),并支持在 Colab 上运行。