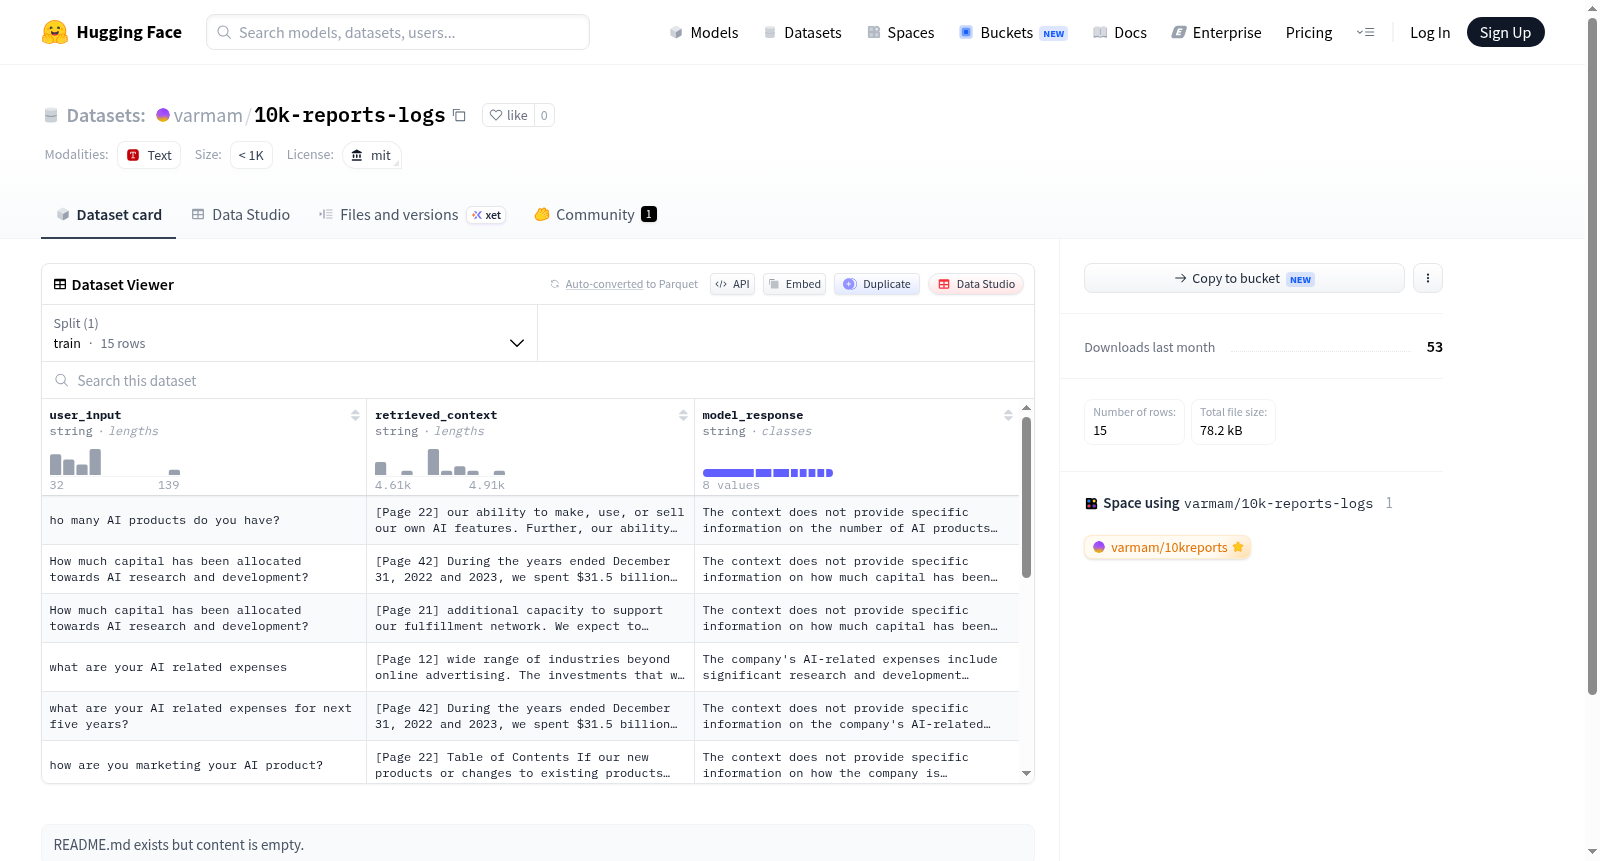
10k-reports-logs
收藏资源简介:
CINO-Small-v2是一个中文少数民族语言指令数据集,旨在支持多语言自然语言处理研究,特别是针对中国少数民族语言。该数据集包含约1.6万条指令数据,覆盖藏语、蒙古语、维吾尔语、彝语、壮语、布依语、朝鲜语、苗语和哈萨克语等9种少数民族语言。每条数据包含instruction(任务指令,如翻译以下句子)、input(任务输入文本,可能为空)、output(任务输出文本)和language(语言标签)四个字段。数据来源于人工翻译和构建,涵盖对话、文本分类、信息抽取、文本生成和代码生成等多种任务类型。适用于指令微调、多语言模型训练和语言资源评估等学术研究场景,但仅限于非商业用途,可能存在噪音或错误,且不保证准确性。
CINO-Small-v2 is a Chinese ethnic minority language instruction dataset developed to support multilingual natural language processing research, with a specific focus on Chinese ethnic minority languages. It contains approximately 16,000 instruction instances, covering nine ethnic minority languages including Tibetan, Mongolian, Uyghur, Yi, Zhuang, Buyei, Korean, Hmong, and Kazakh. Each instance includes four fields: instruction (task instruction, e.g., "Translate the following sentence"), input (task input text, which may be empty), output (task output text), and language (language tag). The dataset is manually translated and curated, covering diverse task types such as dialogue, text classification, information extraction, text generation, and code generation. It is applicable to academic research scenarios including instruction fine-tuning, multilingual model training, and language resource evaluation, and is for non-commercial use only. The dataset may contain noise or errors, and no warranty of accuracy is provided.
数据集名称:10k-reports-logs
数据集地址:https://huggingface.co/datasets/varmam/10k-reports-logs
许可证:MIT(麻省理工学院开源许可证)
数据集用途:该数据集包含10,000份报告日志,适用于自然语言处理、文本分析等相关研究和应用场景。
数据内容:具体包含报告日志文本数据,可用于训练语言模型、进行文本分类、信息提取等任务。