CSU-JPG/Textground4M
收藏资源简介:
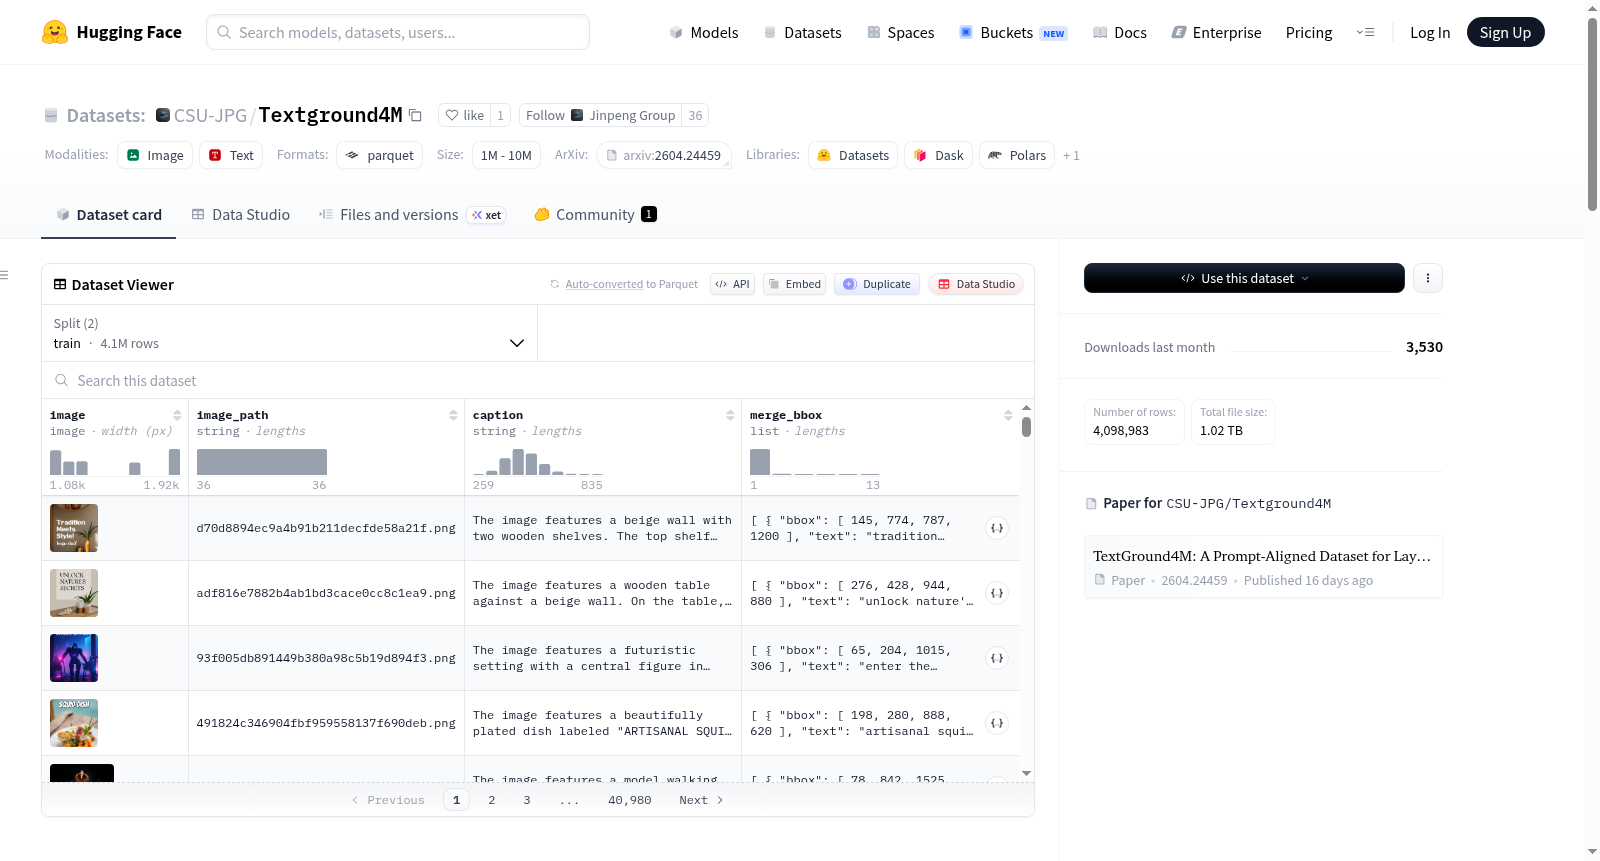
TextGround4M是一个大规模的数据集,专门用于文本到图像(T2I)生成中的提示对齐和布局感知的文本渲染。该数据集包含410万条提示-图像对,每条数据都标注有自然语言标题,其中所有渲染的文本跨度都被明确引用,并且有跨度的边界框链接到图像中的空间位置。这种细粒度的注释为T2I模型提供了布局感知和提示对齐的监督能力,这是之前的数据集如MARIO-10M和AnyWord-3M所不具备的。数据集分为训练集和测试集,训练集约有4.1M样本,测试集有1,000样本。数据字段包括图像、图像路径、标题和合并边界框等信息。
TextGround4M is a large-scale dataset dedicated to prompt alignment and layout-aware text rendering in text-to-image (T2I) generation. This dataset encompasses 4.1 million prompt-image pairs, with each sample annotated with natural language captions. All rendered text spans are explicitly referenced, and their respective bounding boxes are linked to their spatial positions within the corresponding image. Such fine-grained annotations offer layout-aware and prompt-aligned supervision for T2I models, a feature absent in prior datasets such as MARIO-10M and AnyWord-3M. The dataset is divided into training and test subsets: the training set contains approximately 4.1 million samples, while the test set includes 1,000 samples. The data fields include image, image path, caption, merged bounding boxes, and other relevant information.