rajatagarwal457/gdelt-forecast-binary
收藏资源简介:
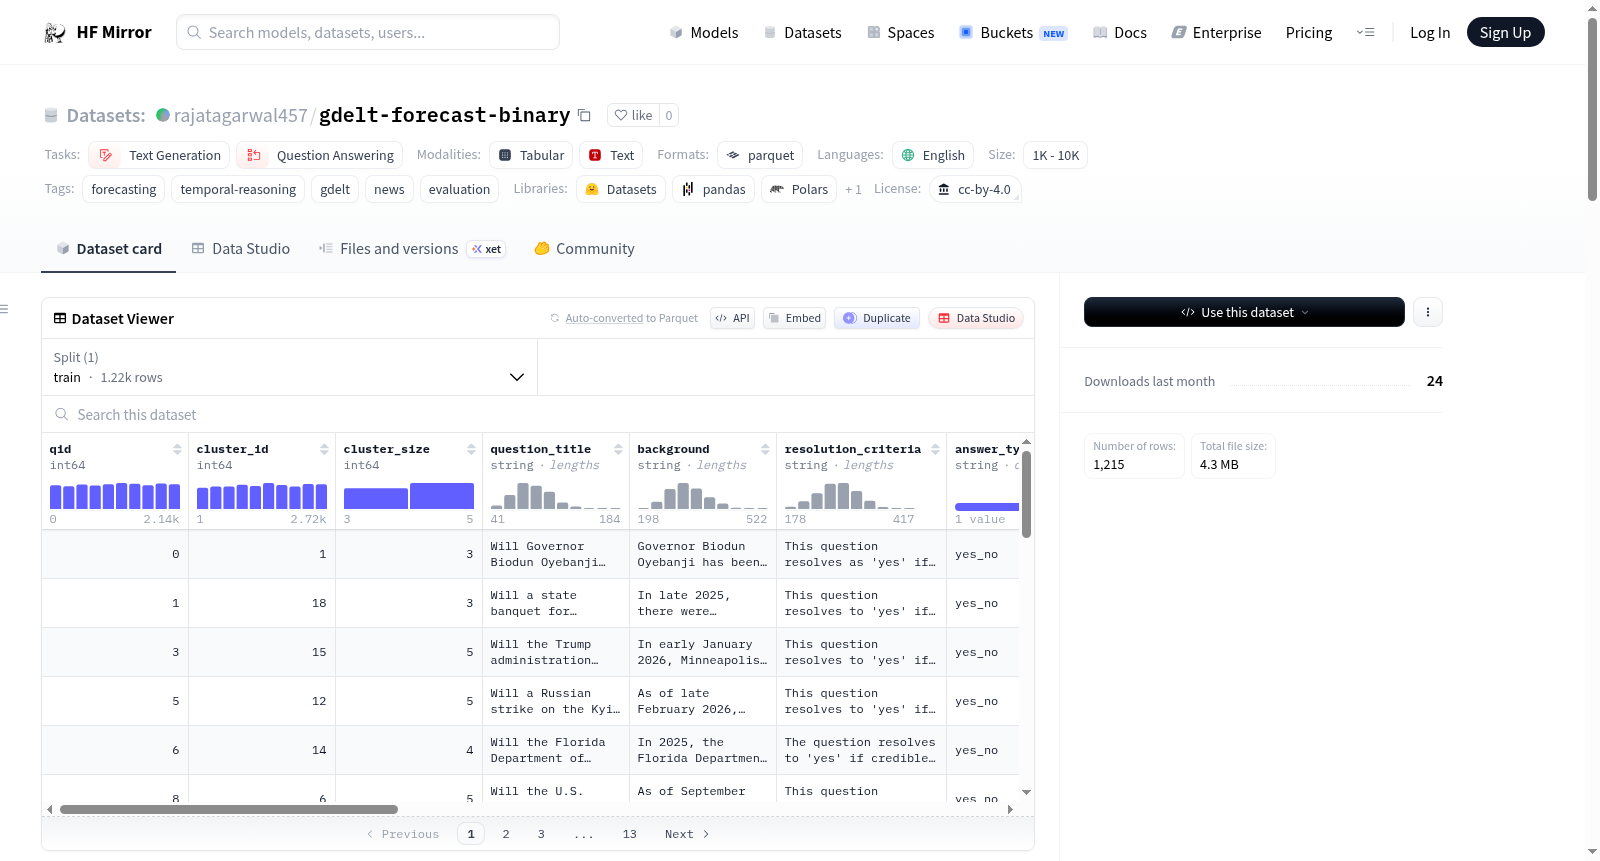
GDELT-Forecast Binary数据集包含1,215个二元(是/否)预测问题,这些问题是从GDELT 2.0语料库(2025年8月至2026年4月)中的新闻文章聚类生成的。每个问题都与原始种子事件文章、在问题创建日期之前检索到的前5篇证据文章以及已验证的答案配对。数据集旨在用于训练和评估基于大型语言模型(LLM)的预测模型,要求模型仅使用问题创建日期之前公开可用的新闻进行预测。数据集的构建过程包括五个阶段:政治/地缘政治过滤、事件聚类、问题生成、证据检索和聚合。数据集的模式(schema)详细列出了每个字段的类型和描述。此外,数据集还提供了统计信息、严格预测姿态的要求、已知限制和引用信息。
GDELT-Forecast Binary contains 1,215 yes/no forecasting questions generated from clusters of news articles in the GDELT 2.0 corpus (Aug 2025 – Apr 2026). Each question is paired with the original seed-event articles, top-5 retrieved evidence articles dated strictly before the question creation date, and a verified ground-truth answer. The dataset is intended for training and evaluating LLM-based forecasting models in a strict forecasting posture — the model sees only news that was publicly available before the questions creation date, then predicts the resolution. The dataset was built through a five-stage pipeline over the GDELT 2.0 corpus, including politics/geopolitics filtering, event clustering, question generation, evidence retrieval, and aggregation. The schema details each fields type and description. Additionally, the dataset provides statistics, strict forecasting posture requirements, known limitations, and citation information.