MoRoVoc
收藏资源简介:
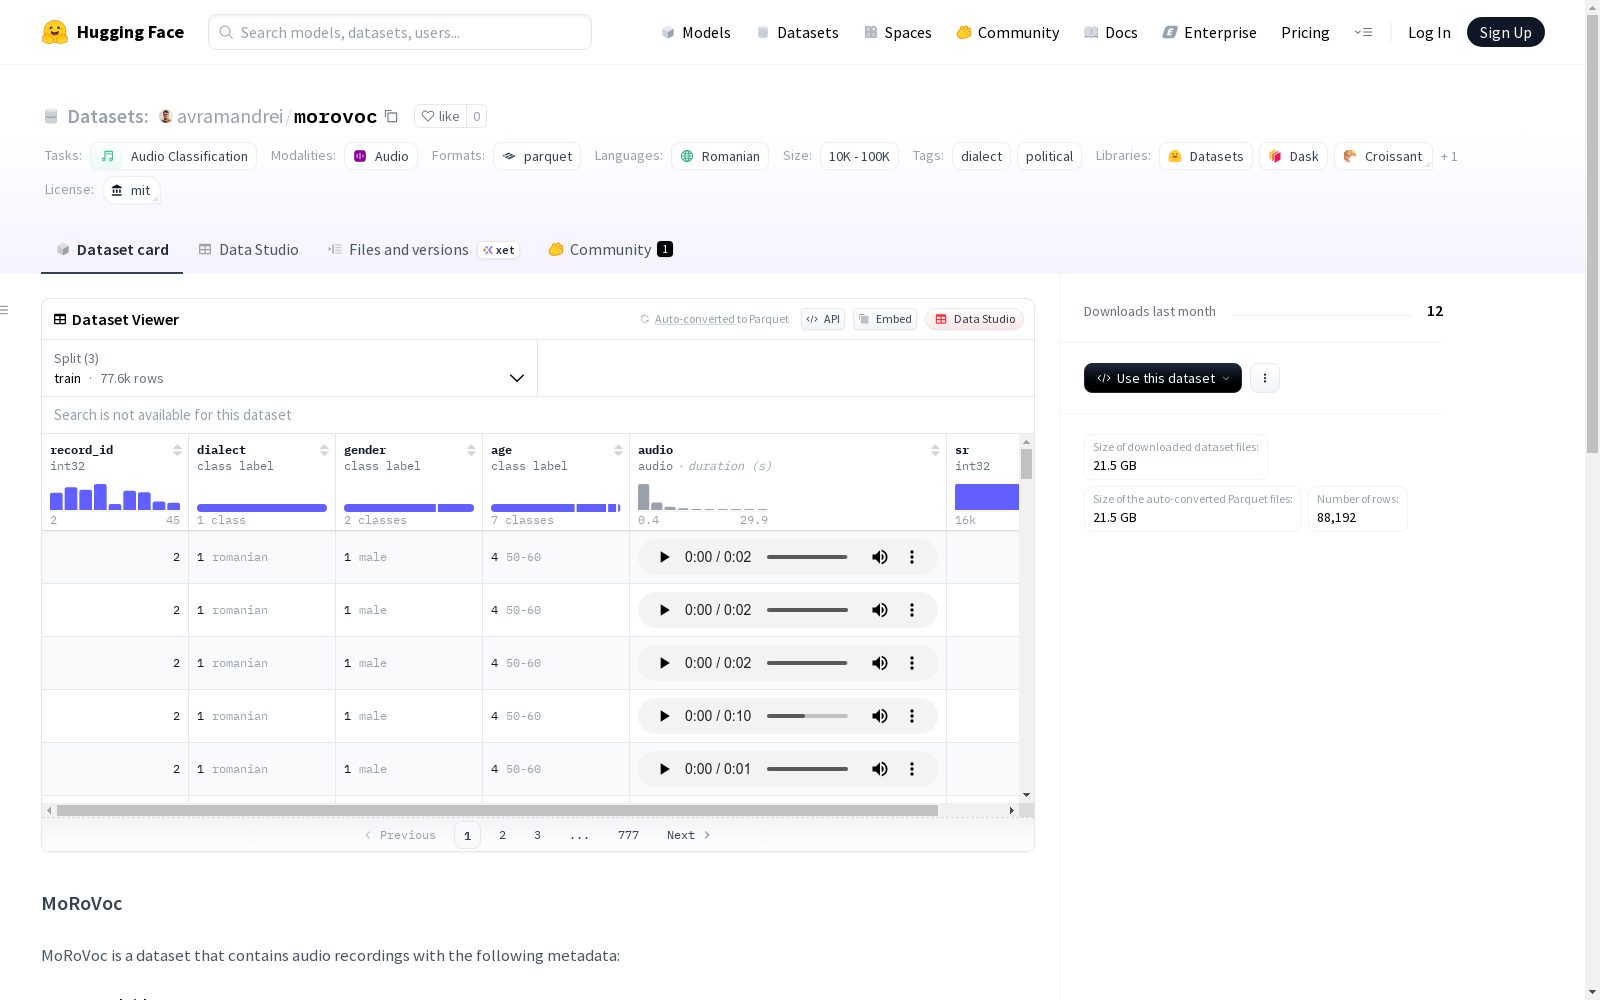
MoRoVoc是目前为止最大的用于分析罗马尼亚语地区变体的数据集,包含93+小时的音频和88,192个音频样本,罗马尼亚语和摩尔多瓦方言之间的样本数量平衡。该数据集包括全面的年龄和性别元数据,来源于高质量议会辩论。MoRoVoc数据集的创建是为了解决低资源语言在语音技术中的方言识别挑战。该数据集可用于公共研究,旨在通过引入多目标对抗训练框架来提高语音模型在方言识别、性别和年龄分类任务上的性能。
MoRoVoc is the largest dataset to date for analyzing Romanian regional varieties. It contains over 93 hours of audio and 88,192 audio samples, with a balanced number of samples between Romanian and Moldovan dialects. The dataset includes comprehensive age and gender metadata, and is sourced from high-quality parliamentary debates. MoRoVoc was created to address the dialect recognition challenge in speech technology for low-resource languages. It is available for public research, and aims to improve the performance of speech models on dialect recognition, gender and age classification tasks by introducing a multi-objective adversarial training framework.
MoRoVoc数据集概述
基本信息
- 许可证: MIT
- 语言: 罗马尼亚语 (ro)
- 任务类别: 音频分类
- 标签: 方言、政治
- 规模类别: 10K<n<100K
数据集结构
- 训练集: 77,638个样本
- 验证集: 5,348个样本
- 测试集: 5,348个样本
数据特征
- record_id: 每个记录的唯一标识符 (int32)
- dialect: 说话者的方言/语言变体
- 0: moldavian
- 1: romanian
- gender: 说话者的性别
- 0: female
- 1: male
- age: 说话者的年龄范围
- 0: 10-20
- 1: 20-30
- 2: 30-40
- 3: 40-50
- 4: 50-60
- 5: 50-70
- 6: 60-70
- 7: 70-80
- 8: 80-90
- audio: 音频文件 (WAV格式,采样率16,000Hz)
- sr: 音频采样率 (int32)
技术规格
- 下载大小: 21,519,950,558字节
- 数据集大小: 21,198,182,075.088字节
- 音频采样率: 16,000Hz
使用方式
python from datasets import load_dataset
dataset = load_dataset("avramandrei/morovoc")
访问数据分割
train_data = dataset[train] valid_data = dataset[validation] test_data = dataset[test]
访问样本
sample = train_data[0] audio_array = sample[audio][array] sampling_rate = sample[audio][sampling_rate]
引用信息
- 论文状态: 工作进展中
- 引用格式: Work in progress