recitation-sanskrit-01
收藏资源简介:
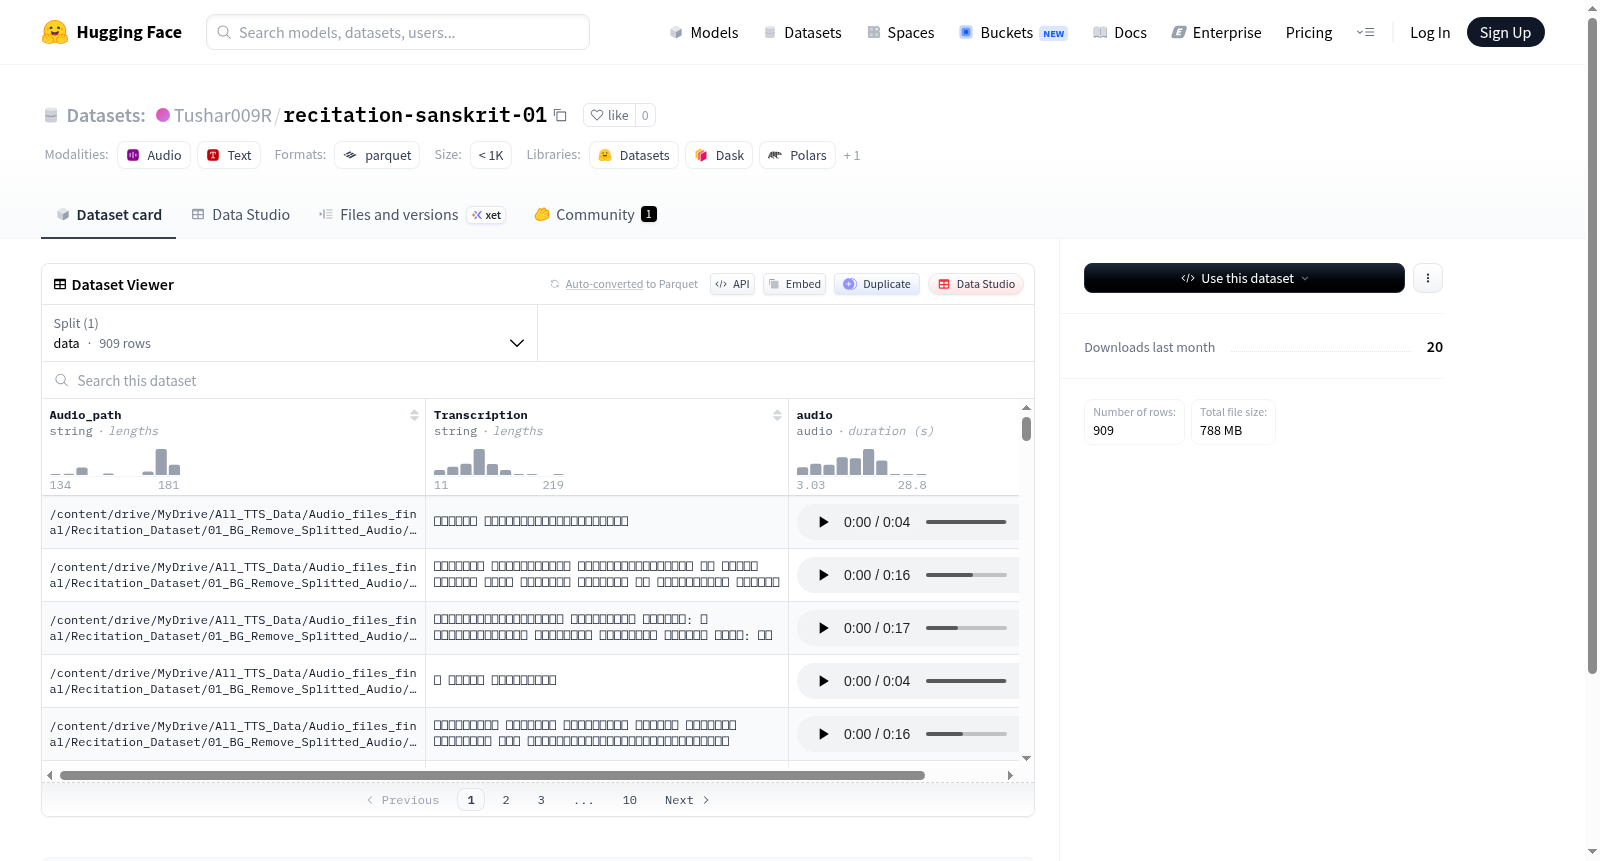
该数据集包含909个音频样本及相关文本转录,总大小约837MB。每个样本包含三个字段:1) Audio_path - 音频文件路径(字符串类型);2) Transcription - 对应的文本转录内容(字符串类型);3) audio - 原始音频数据(音频格式,未解码)。数据集采用单一分割(data),默认配置下数据文件路径为data/data-*。未提供关于数据来源、采集背景或具体应用场景的文本描述。
This dataset comprises 909 audio samples and their corresponding text transcriptions, with a total size of approximately 837 MB. Each sample contains three fields: 1) Audio_path: the path of the audio file (string type); 2) Transcription: the corresponding text transcription content (string type); 3) audio: the raw audio data in audio format, undecoded. The dataset uses a single split named data, and the default path for the data files is data/data-*. No textual descriptions regarding the data source, collection background, or specific application scenarios are provided.
根据您提供的数据集详情页面信息,以下是该数据集的概述:
数据集概述
基本信息
- 数据集名称:recitation-sanskrit-01
- 数据集地址:https://huggingface.co/datasets/Tushar009R/recitation-sanskrit-01
- 数据集大小:约837.9 MB(数据集总大小)
- 下载大小:约787.9 MB
数据特征
该数据集包含以下三个特征字段:
- Audio_path(字符串类型):音频文件路径。
- Transcription(字符串类型):音频对应的文本转录。
- audio(音频类型,未解码):音频数据,以原始格式存储,不进行解码处理。
数据集划分
- 数据集仅包含一个划分:data 划分。
- 示例数量:共909个样本。
- 数据文件路径:
data/data-*(通配符表示多个数据文件)。
配置信息
- 默认配置名称为:default,对应上述的 data 划分。