lower-bavarian-speech
收藏资源简介:
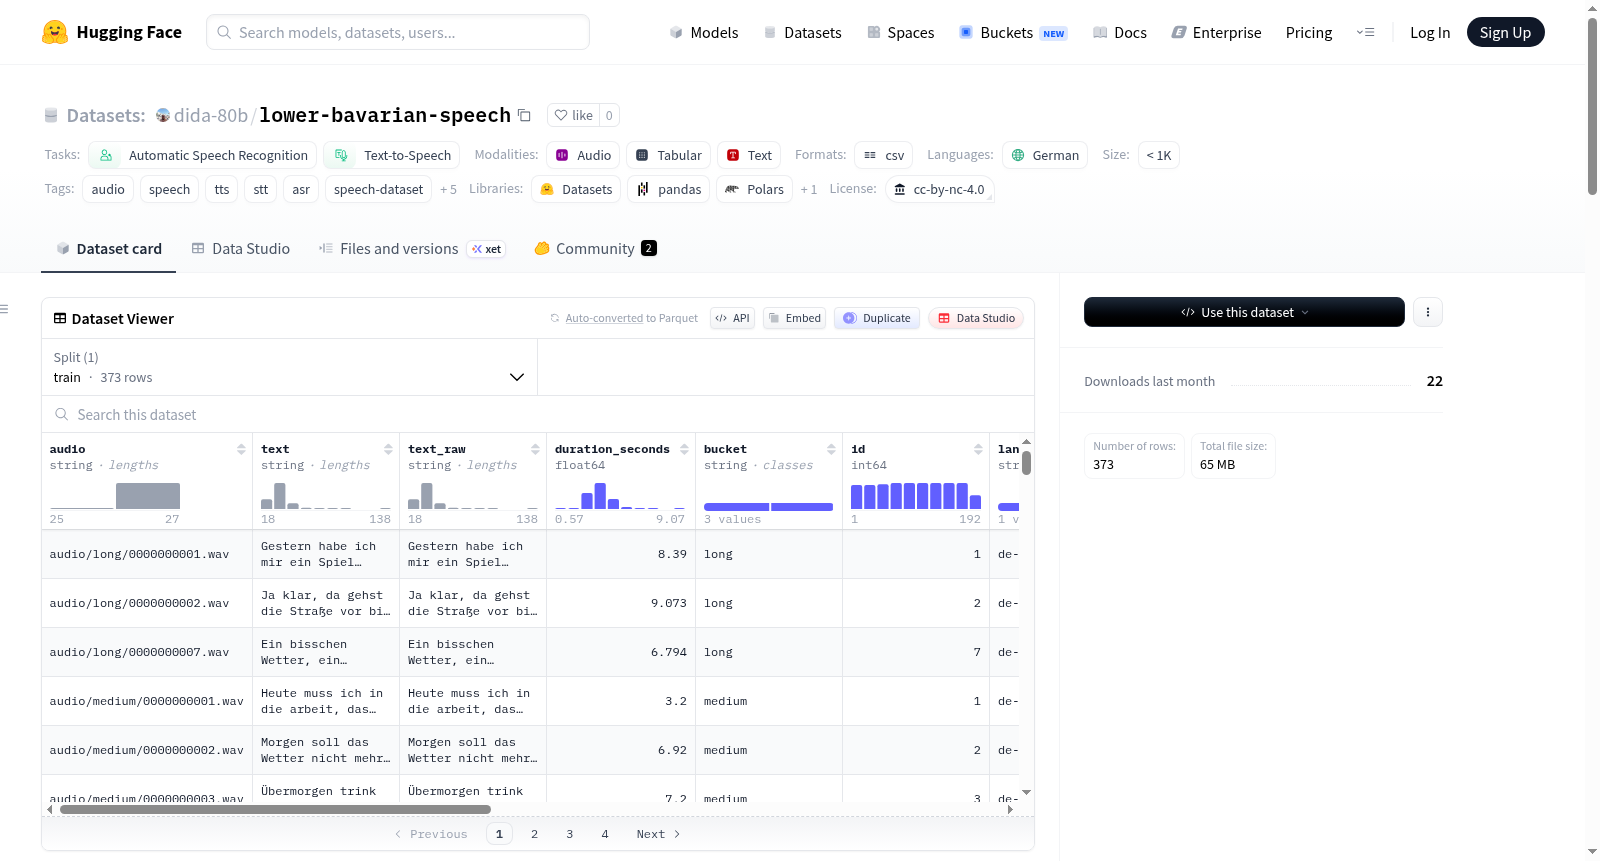
Lower Bavarian Speech(早期访问)是一个小型公开语音数据集,包含来自单一说话者的下巴伐利亚语(Niederbairisch)录音。数据集目前处于早期公开版本,包含292个经过审核的音频片段,总计约17.8分钟的语音内容。录音语言为德语(de-DE),方言标签为下巴伐利亚语(niederbairisch),录音质量标签为“clean”。数据集混合了较短和较长的自发口语句子,适用于自动语音识别(ASR)实验、方言适应、文本到语音(TTS)数据检查和原型设计,以及发音和转录分析。数据集的结构包括音频文件路径、转录文本、原始转录文本、音频时长、片段分类(short/medium/long)、原始ID、语言、方言、来源数据集名称、说话者配置标签、录音质量标签、情感标签、风格标签和TTS适用性标签。需要注意的是,数据集目前仅包含单一说话者,规模较小,尚未划分训练/开发/测试集,适合作为早期基础数据集使用。
Lower Bavarian Speech (Early Access) is a small open-access speech dataset containing recordings of Niederbairisch (Lower Bavarian dialect) from a single speaker. The dataset is currently in its early public release, containing 292 curated audio clips totaling approximately 17.8 minutes of speech content. The recording language is German (de-DE), with the dialect label designated as Niederbairisch, and the recording quality label marked as "clean". The dataset comprises a mix of short and long spontaneous spoken sentences, and is applicable to automatic speech recognition (ASR) experiments, dialect adaptation, text-to-speech (TTS) data inspection and prototyping, as well as phonetic and transcription analysis. The dataset structure includes fields such as audio file path, transcribed text, original transcribed text, audio duration, clip classification (short/medium/long), original ID, language, dialect, source dataset name, speaker configuration label, recording quality label, emotion label, style label, and TTS applicability label. It is worth noting that the dataset currently only includes a single speaker, has a small scale, and has not been divided into training, development, and test subsets, making it suitable as an early-stage foundational dataset.
Lower Bavarian Speech (Early Access) 数据集概述
数据集基本信息
- 名称: Lower Bavarian Speech (Early Access)
- 语言: 德语 (
de) - 方言: 下巴伐利亚语 (
Niederbairisch) - 许可协议: CC-BY-NC-4.0
- 规模类别: n<1K
- 任务类别: 自动语音识别、文本到语音
- 标签: 音频、语音、TTS、STT、ASR、语音数据集、巴伐利亚语、德语、方言、下巴伐利亚语、Niederbairisch
数据集状态与特点
- 状态: 早期访问版本,工作仍在进行中。
- 内容: 来自单一说话者的下巴伐利亚语录音。
- 适用性: 适用于小规模的自动语音识别和文本到语音实验。
- 结构: 为直接与 Hugging Face Datasets 库使用而构建,包含
audio/目录和metadata.csv文件。
数据内容详情
- 录音数量: 292 条已审核的音频片段。
- 总时长: 约 17.8 分钟语音。
- 语言代码:
de-DE - 方言标签:
niederbairisch - 说话者设置: 单一说话者。
- 录音质量标签:
clean - 内容类型: 混合了较短和较长的自发口语句子。
数据集用途
- 自动语音识别实验。
- 方言适应。
- 文本到语音数据检查和原型设计。
- 发音和转录分析。
数据列说明
audio: WAV 文件的相对路径。text: 经过空格标准化的转录文本。text_raw: 来自审核清单的原始转录文本。duration_seconds: 片段时长。bucket: 分类为short、medium或long。id: 导出数据集中的原始项目 ID。language:de-DEdialect:niederbairischbase_dataset: 源数据集名称。speaker_profile: 说话者设置标签。recording_quality: 来自审核清单的质量标签。emotion_label: 来自审核清单的情感标签。style_label: 来自审核清单的风格标签。tts_suitability: 来自审核清单的适用性标签。
注意事项
- 转录文本反映了审核过的口语内容,未标准化为正式的标准德语。
- 部分表达包含口语化措辞或自发的句子结构,这是预期且有意为之的。
- 后续修订可能会添加更多片段、清理元数据并改进卡片。
局限性
- 仅包含单一说话者。
- 规模仍然相对较小。
- 尚未划分训练/开发/测试集。
- 最好视为早期基础数据集,而非已完成的基准数据集。
示例音频
- 文本:
Die Berge sind von hier aus nicht weit weg.预览: https://huggingface.co/datasets/dida-80b/lower-bavarian-speech/resolve/main/audio/short/0000000008.wav - 文本:
Ich habe mich gestern gescheit verspätet.预览: https://huggingface.co/datasets/dida-80b/lower-bavarian-speech/resolve/main/audio/short/0000000024.wav - 文本:
Ja klar, da gehst die Straße vor bis zur Kreuzung, dann rechts entlang und dann kommt der Netto.预览: https://huggingface.co/datasets/dida-80b/lower-bavarian-speech/resolve/main/audio/long/0000000002.wav