gretel-financial-risk-analysis-v1
收藏资源简介:
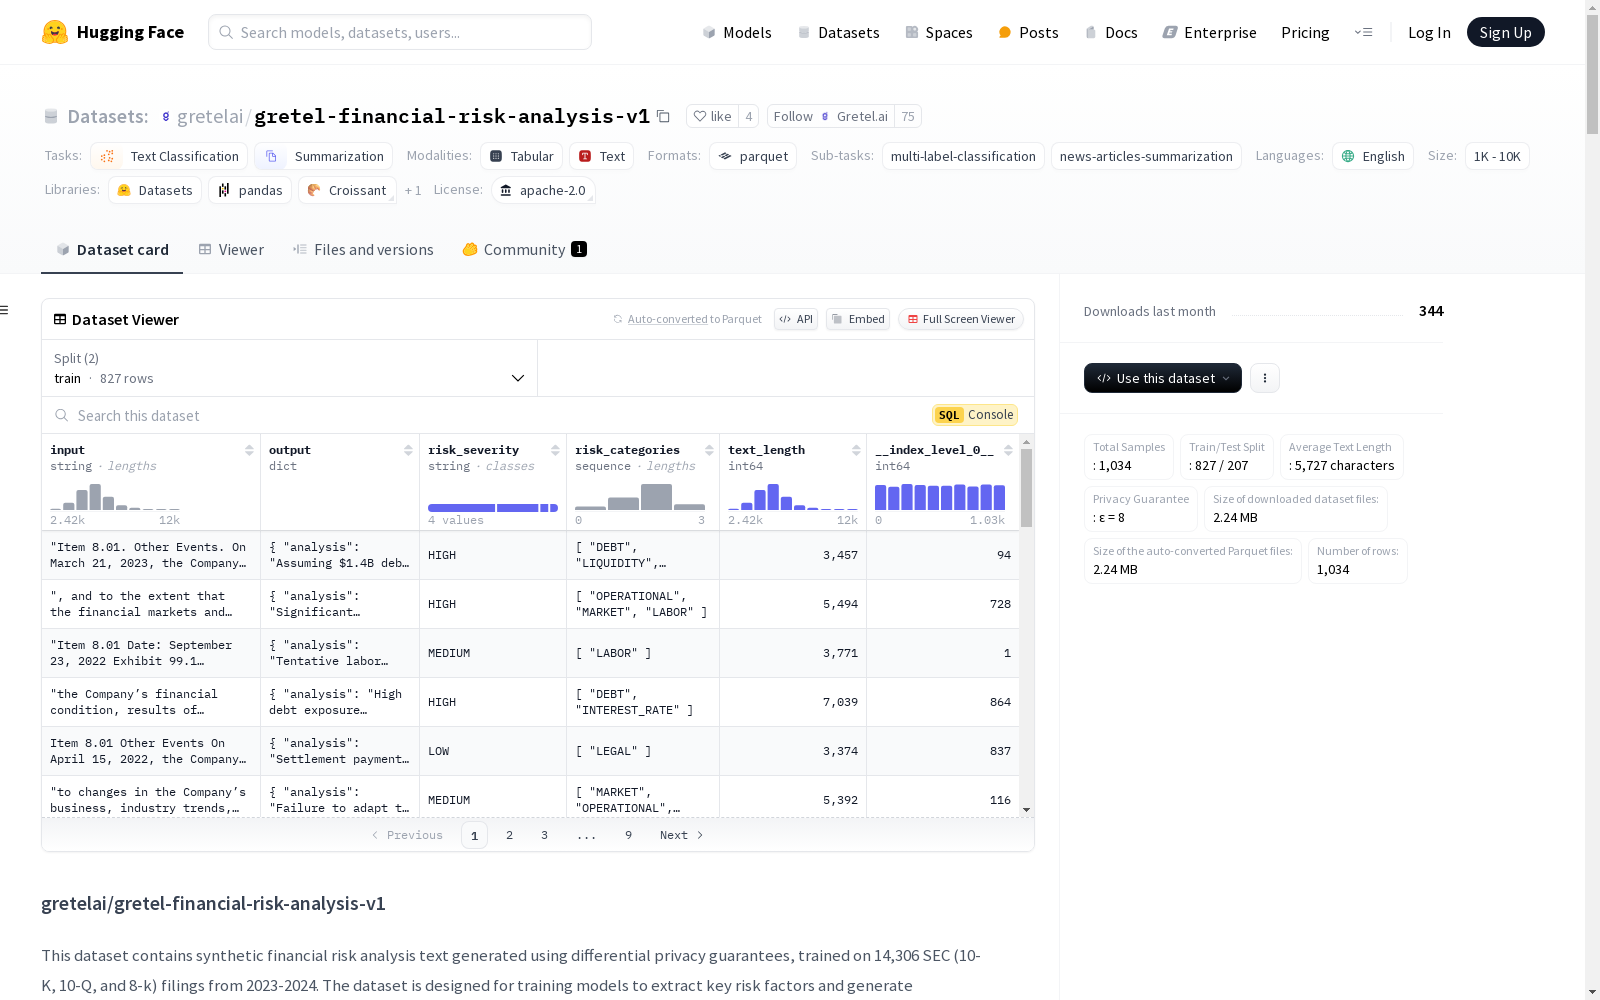
该数据集包含使用差分隐私保证生成的合成金融风险分析文本,训练数据来自2023-2024年的14,306份SEC(10-K、10-Q和8-K)文件。数据集旨在训练模型从金融文档中提取关键风险因素并生成结构化摘要,展示了利用差分隐私保护敏感信息的能力。数据集支持两个主要任务:特征提取(识别和分类文本中的金融风险)和文本摘要(生成结构化风险分析摘要)。模型输出包括风险严重性分类、风险类别识别和识别风险的结构化分析。数据集包含1,034个样本,训练/测试分割为827/207,平均文本长度为5,727个字符,隐私保证为ε = 8。
This dataset comprises synthetic financial risk analysis texts generated under differential privacy guarantees, with training data sourced from 14,306 SEC filings (10-K, 10-Q, and 8-K) spanning 2023 to 2024. It is designed to train models to extract critical risk factors from financial documents and generate structured summaries, demonstrating the capability of leveraging differential privacy to protect sensitive information. The dataset supports two core tasks: feature extraction (identifying and classifying financial risks within texts) and text summarization (generating structured risk analysis summaries). Model outputs include risk severity classification, risk category identification, and structured analysis of identified risks. The dataset contains 1,034 samples, with an 827/207 train/test split, an average text length of 5,727 characters, and a privacy guarantee of ε = 8.