orpo-text-pairs
收藏资源简介:
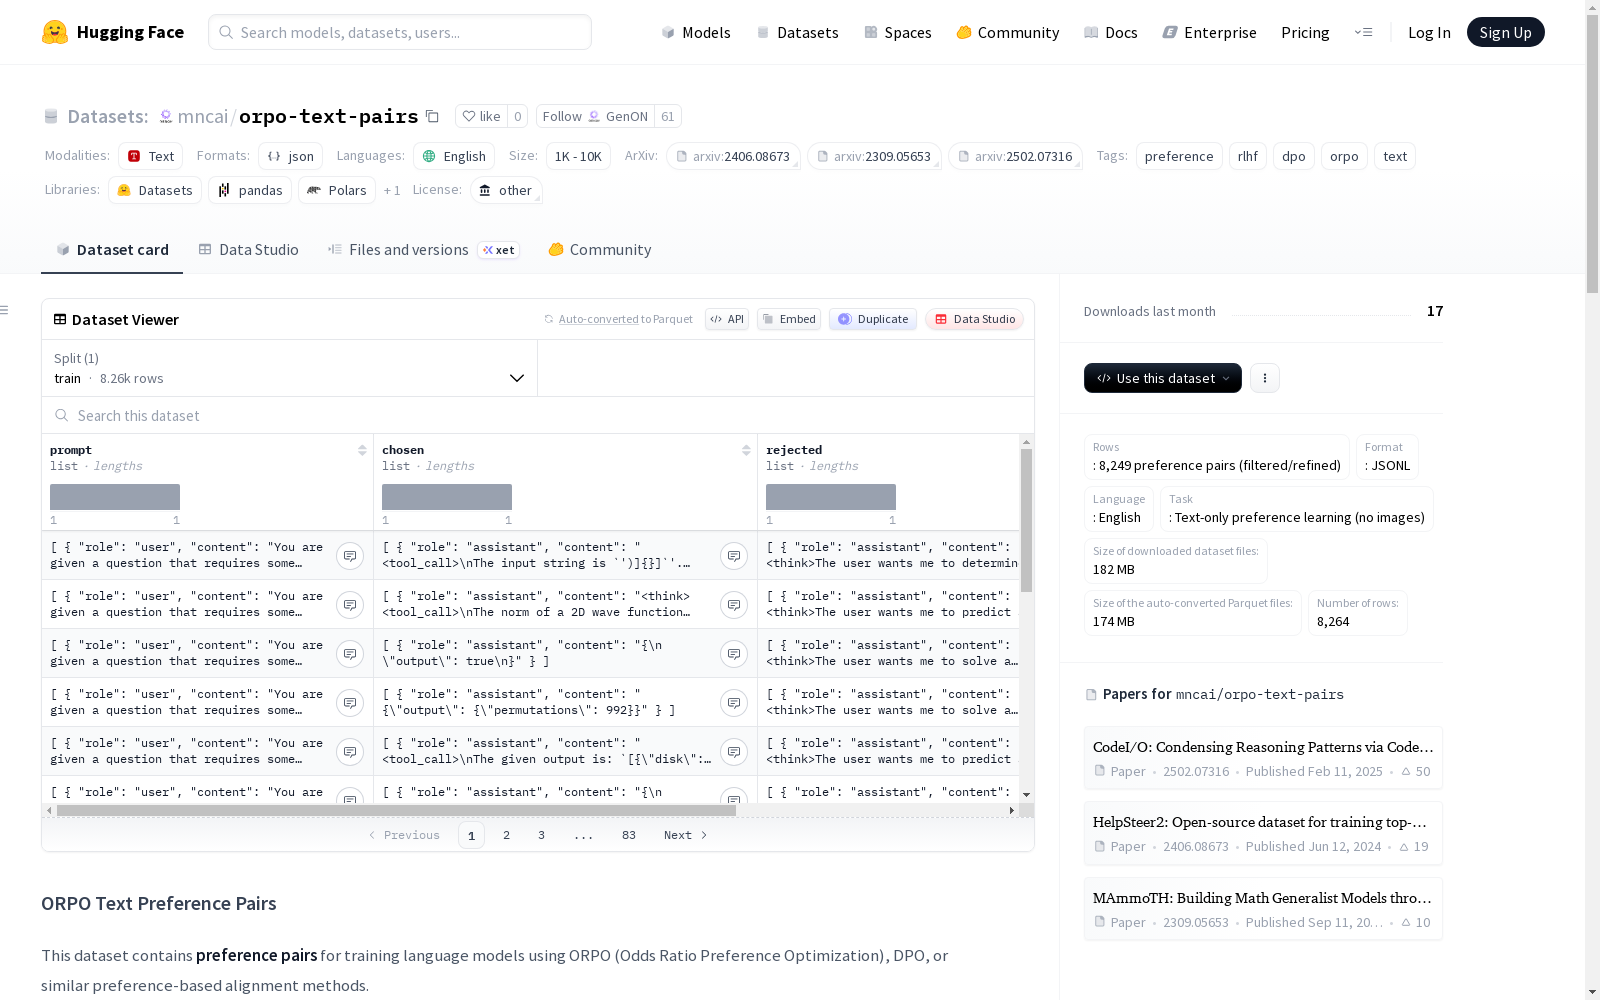
ORPO文本偏好对数据集包含8,249个经过筛选/精炼的偏好对,用于训练语言模型使用ORPO(Odds Ratio Preference Optimization)、DPO或类似的基于偏好的对齐方法。数据集采用JSONL格式,包含纯英文文本数据。每条记录包含以下字段:'prompt'(用户对话轮次)、'chosen'(优选响应)、'rejected'(非优选响应)和'meta'(元数据,包括来源数据集、使用的模型和评判信息)。元数据字段详细记录了来源数据集名称、原始行索引、生成响应的模型、评判决策以及样本是否适合训练。该数据集源自多个来源数据集,包括HelpSteer2、MathInstruct、CodeIO-PyEdu-Reasoning和MathV360K,继承了这些数据集的混合许可要求。使用本数据集时,需遵守各来源数据集的许可条款,并对部分来源数据集进行署名。
The ORPO Text Preference Pair Dataset contains 8,249 filtered and refined preference pairs, intended for training language models using ORPO (Odds Ratio Preference Optimization), DPO, or other similar preference-based alignment methods. This dataset is stored in JSONL format and consists exclusively of English text data. Each record includes the following fields: 'prompt' (user dialogue turn), 'chosen' (preferred response), 'rejected' (non-preferred response), and 'meta' (metadata including source datasets, the model used, and annotation information). The meta field comprehensively records the source dataset name, original row index, model that generated the responses, judgment decisions, and whether the sample is suitable for training. This dataset is derived from multiple source datasets including HelpSteer2, MathInstruct, CodeIO-PyEdu-Reasoning, and MathV360K, and inherits the mixed licensing requirements of these datasets. When using this dataset, users must comply with the licensing terms of each source dataset and provide attribution for some of the source datasets.