AraSeg-2026-Shared-Task-NP
收藏资源简介:
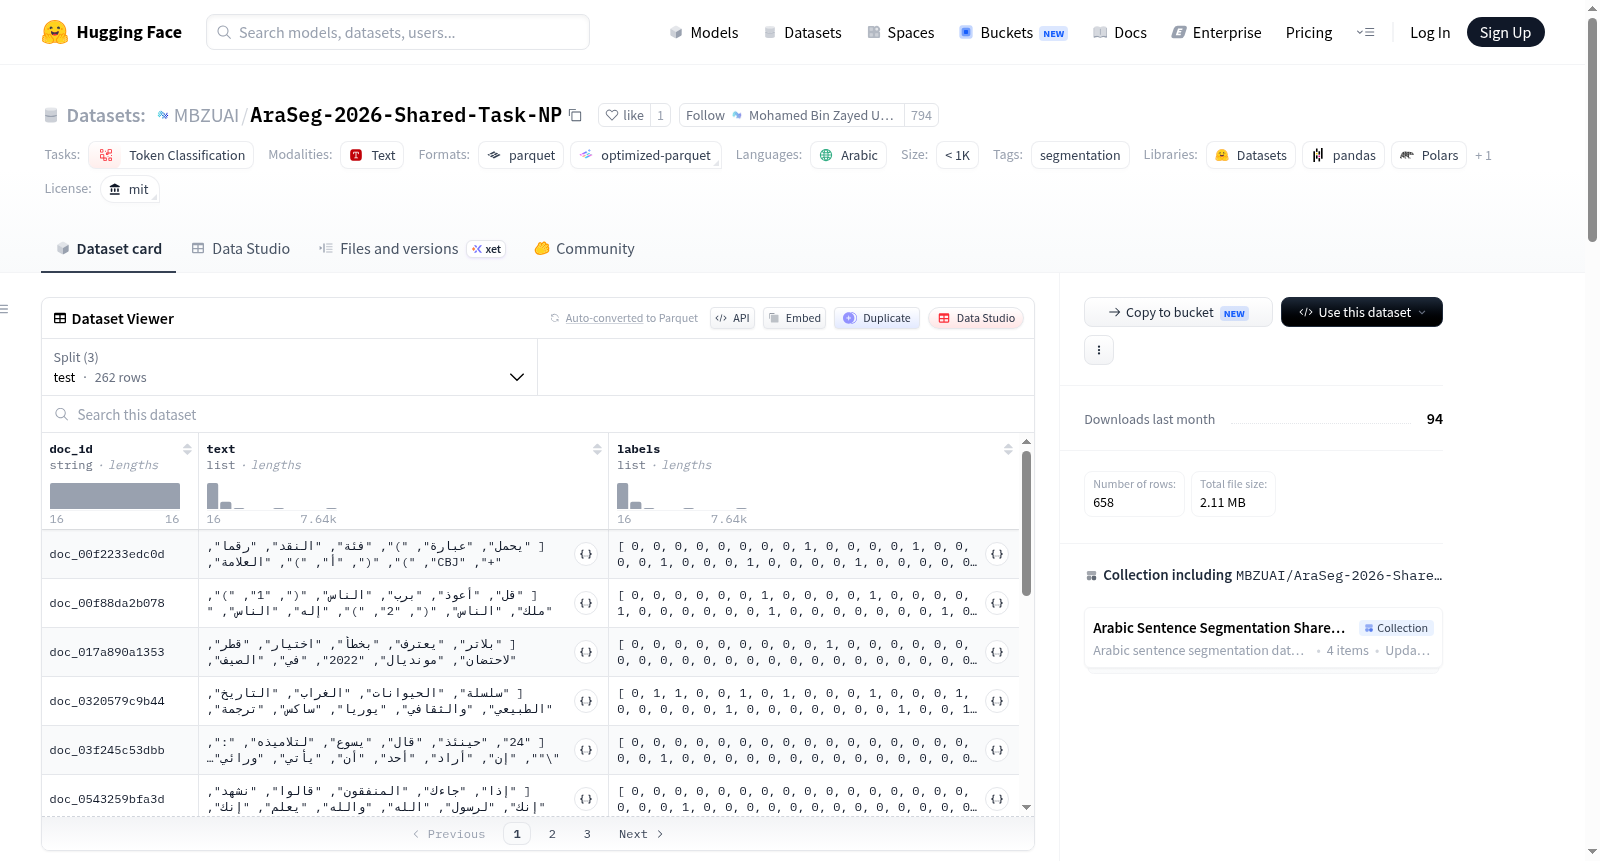
AraSeg是首个用于阿拉伯语句子分割的综合基准数据集,专注于现代标准阿拉伯语(MSA)在标点不一致、缺失或嘈杂环境下的句子分割研究。该数据集包含从多样来源和体裁收集的手动标注文档,支持跨不同写作风格和领域的鲁棒评估。数据集提供AraSeg-NP变体,其中移除了段落边界。在结构上,每个数据实例包括唯一文档标识符(doc_id)、以分词token列表形式表示的文本(text),以及token级句子边界标签(labels),其中标签1表示当前token后跟随句子边界,0表示无边界。数据集分为训练集(174个文档,含10,657个句子和124K词)、开发集(222个文档,含12,985个句子和159K词)和测试集(262个文档,含12,509个句子和154K词),总大小约8.6MB。任务定义为二元token分类,即给定token序列,预测每个token后是否有句子边界。评估采用边界级指标,包括精确率、召回率和F1值,在文档级别计算并跨语料库平均。
AraSeg is the first comprehensive benchmark dataset for Arabic sentence segmentation, focusing on sentence segmentation research of Modern Standard Arabic (MSA) in scenarios with inconsistent, missing or noisy punctuation. This dataset contains manually annotated documents collected from diverse sources and genres, enabling robust evaluation across different writing styles and domains. It provides the AraSeg-NP variant, where paragraph boundaries are removed. Structurally, each data instance includes a unique document identifier (doc_id), text represented as a tokenized list of tokens, and token-level sentence boundary labels, where label 1 indicates a sentence boundary follows the current token and label 0 indicates no boundary. The dataset is split into training set (174 documents, containing 10,657 sentences and 124K words), development set (222 documents, containing 12,985 sentences and 159K words) and test set (262 documents, containing 12,509 sentences and 154K words), with a total size of approximately 8.6 MB. The task is defined as binary token classification: given a token sequence, predict whether a sentence boundary exists after each token. Evaluation adopts boundary-level metrics including precision, recall and F1-score, which are calculated at the document level and averaged across the corpus.