s800-sapbert-selection
收藏资源简介:
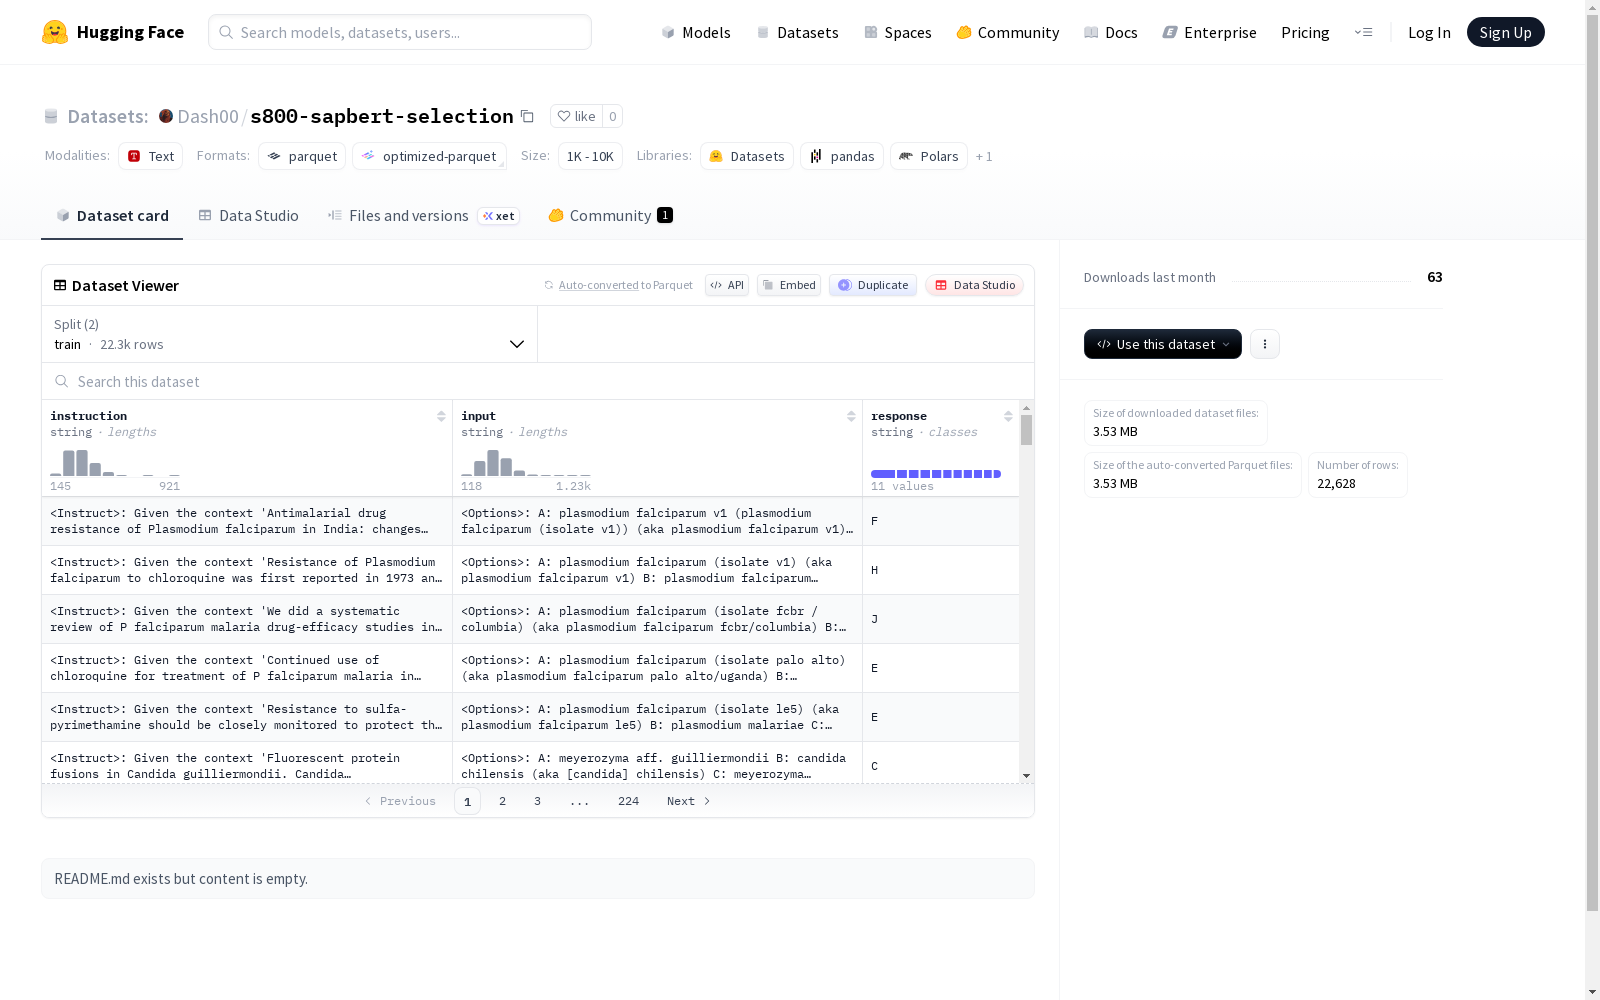
该数据集包含8379个训练样本和284个测试样本,总大小约6.68MB。每个样本由三个文本字段组成:instruction(指令)、input(输入)和response(响应)。数据集采用标准分割方式,包含训练集(train)和测试集(test)两部分,分别存储在data/train-*和data/test-*路径下。从字段命名推断,该数据集可能用于指令跟随或对话生成类任务,但具体应用场景需结合实际数据内容进一步确认。
This dataset comprises 8379 training samples and 284 test samples, with an overall size of approximately 6.68 MB. Each sample includes three text fields: "instruction", "input", and "response". The dataset adopts a standard train-test split, containing a training set (train) and a test set (test), which are respectively stored under the paths data/train-* and data/test-*. Based on the naming of these fields, this dataset may be intended for instruction following or dialogue generation tasks; however, its specific application scenarios need to be further confirmed by referring to the actual data content.