media-metadata-librivox-audiobooks
收藏资源简介:
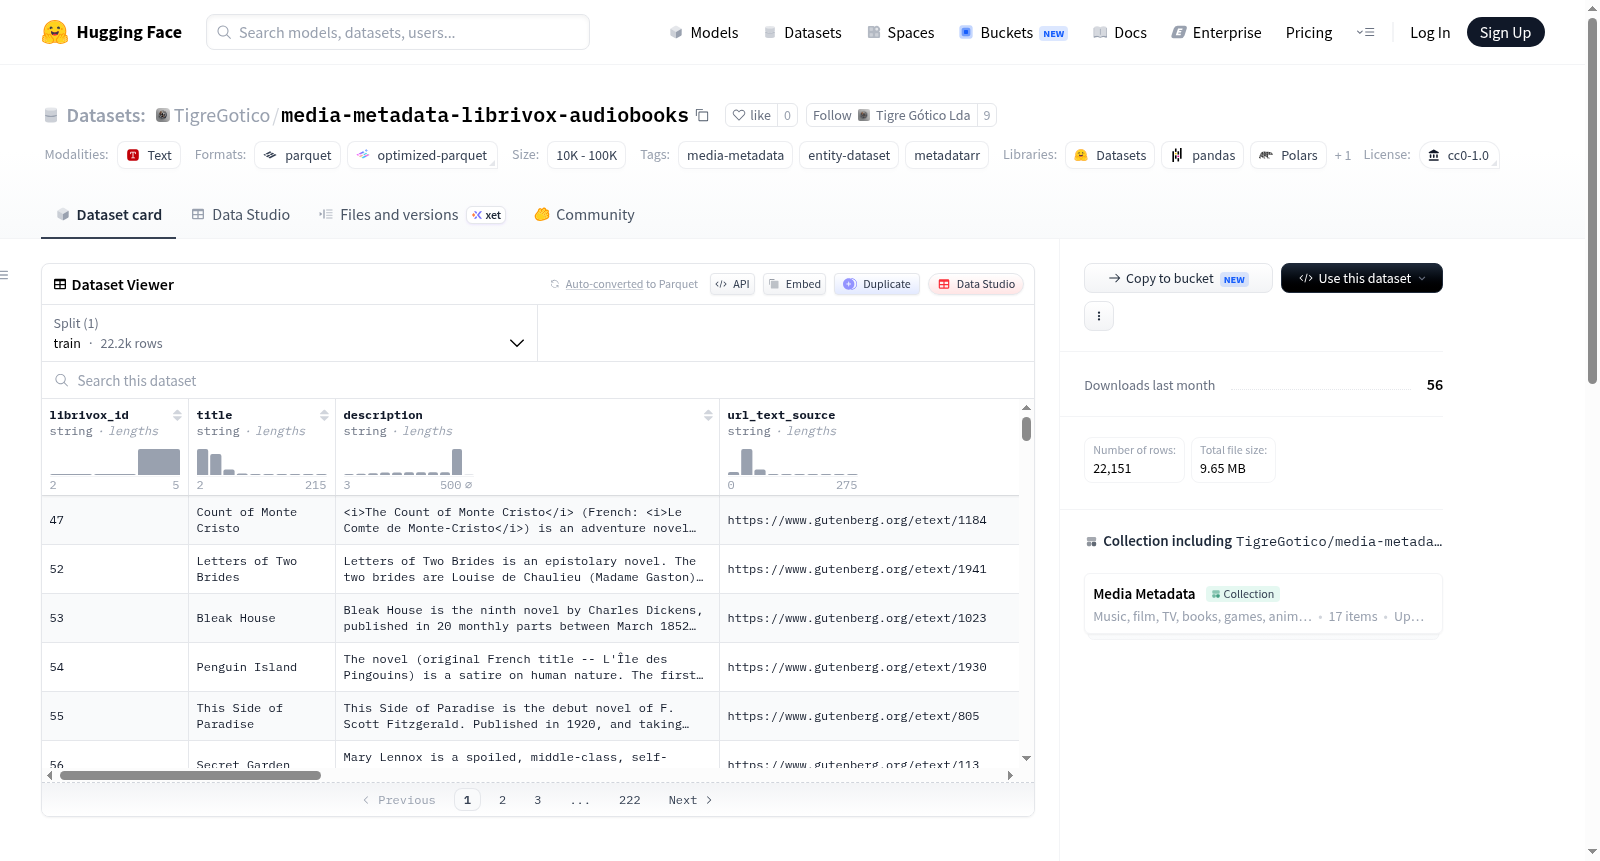
LibriVox Audiobooks数据集是一个包含22,000个有声读物录音元数据的集合,这些录音来自LibriVox平台——一个由志愿者录制、属于公共领域的项目,所有录音可自由下载和使用,无任何限制。该数据集在语音研究领域广泛应用,著名的LibriSpeech自动语音识别(ASR)基准测试即基于此。它提供完整的目录元数据,以结构化字段呈现,包括:LibriVox目录ID、书籍标题、源文本链接(通常指向古登堡计划)、录音语言、文本进入公共领域的年份、音频章节数量、项目类型(如独奏或协作)、录音的RSS订阅链接、完整ZIP文件的直接下载链接、作者列表(含名、姓、出生和逝世日期)以及朗读者列表(含名、姓和读者ID)。其中,朗读者字段特别适用于多朗读者协作项目,常用于说话人多样性研究。数据集适用于语音处理、有声读物分析、说话人识别和公共领域资源挖掘等任务。
The LibriVox Audiobooks Dataset is a collection of metadata for 22,000 audiobook recordings sourced from LibriVox, a public-domain project recorded by volunteers where all recordings are freely downloadable and usable without any restrictions. This dataset is widely applied in the field of speech research, and the renowned LibriSpeech automatic speech recognition (ASR) benchmark is based on it. It provides complete catalog metadata presented in structured fields, including: LibriVox catalog ID, book title, source text link (usually pointing to Project Gutenberg), recording language, year when the text entered the public domain, number of audio chapters, project type (e.g., solo or collaborative), RSS subscription link of the recording, direct download link of the full ZIP file, list of authors (including first name, last name, birth and death dates), and list of readers (including first name, last name and reader ID). The reader field is particularly suitable for multi-reader collaborative projects and is often used in speaker diversity research. The dataset is applicable to tasks such as speech processing, audiobook analysis, speaker recognition and public domain resource mining.