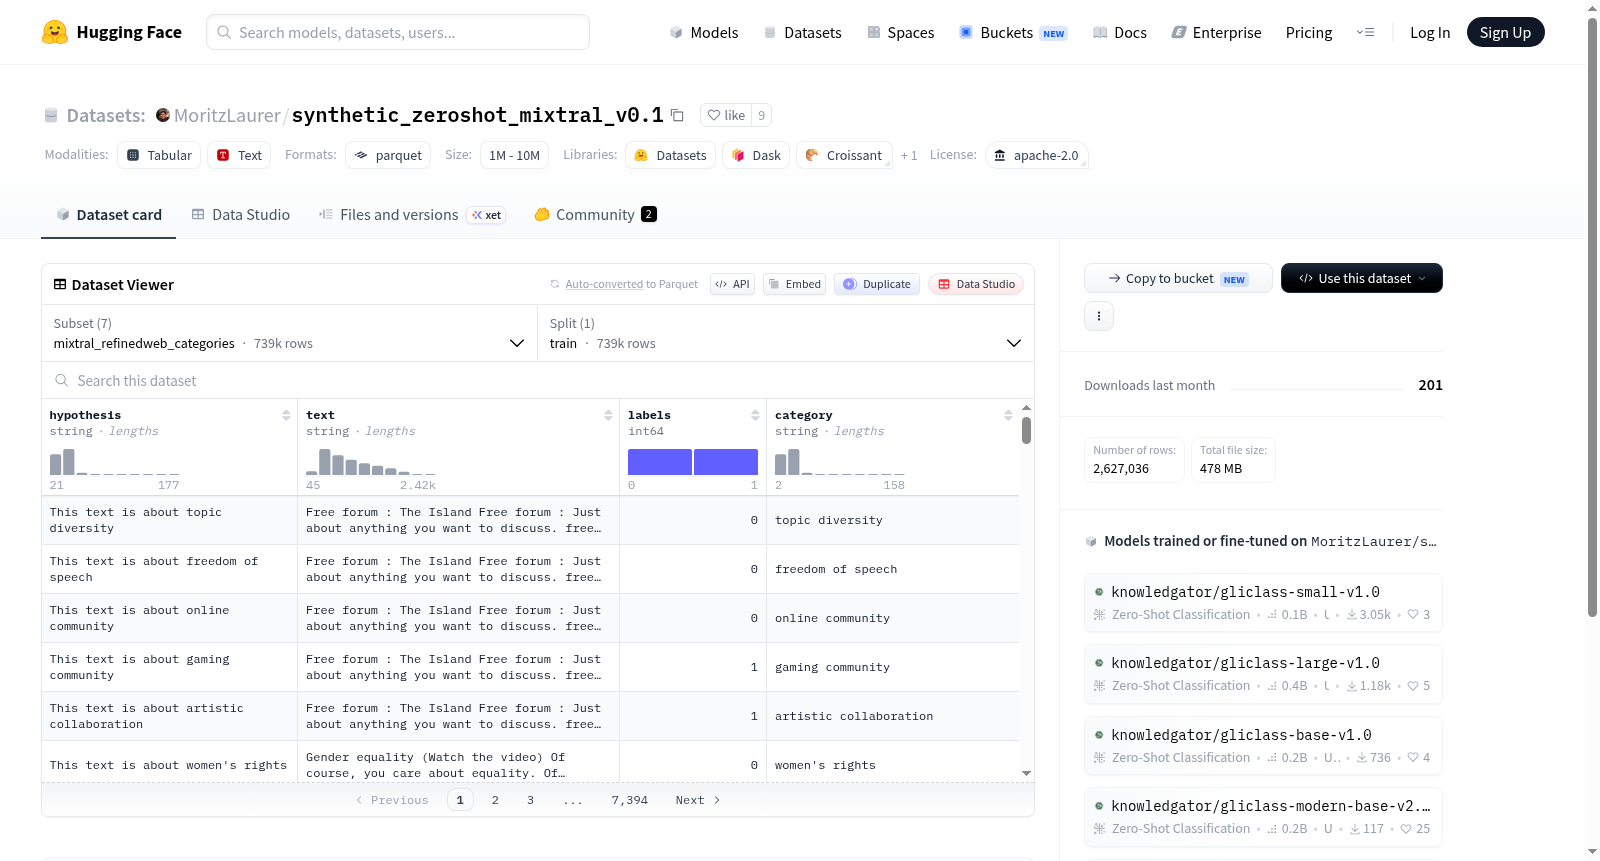
MoritzLaurer/synthetic_zeroshot_mixtral_v0.1
收藏资源简介:
--- license: apache-2.0 dataset_info: - config_name: mixtral_refinedweb_categories features: - name: hypothesis dtype: string - name: text dtype: string - name: labels dtype: int64 - name: category dtype: string splits: - name: train num_bytes: 679252117 num_examples: 739362 download_size: 93960048 dataset_size: 679252117 - config_name: mixtral_refinedweb_characteristics features: - name: hypothesis dtype: string - name: text dtype: string - name: labels dtype: int64 splits: - name: train num_bytes: 508301784 num_examples: 543242 download_size: 76811839 dataset_size: 508301784 - config_name: mixtral_refinedweb_nli features: - name: hypothesis dtype: string - name: text dtype: string - name: labels dtype: int64 - name: hypo_topic dtype: string - name: topic_id dtype: int64 - name: topic_prob dtype: float64 - name: __index_level_0__ dtype: int64 splits: - name: train num_bytes: 99039674 num_examples: 94428 download_size: 60993629 dataset_size: 99039674 - config_name: mixtral_written_texts_for_tasks features: - name: hypothesis dtype: string - name: text dtype: string - name: labels dtype: int64 - name: text_type dtype: string - name: text_style dtype: string - name: profession dtype: string - name: task_description dtype: string - name: task_hypotheses sequence: string splits: - name: train num_bytes: 117675112 num_examples: 105806 download_size: 17224265 dataset_size: 117675112 - config_name: mixtral_written_texts_for_tasks_v2 features: - name: hypothesis dtype: string - name: text dtype: string - name: labels dtype: int64 - name: text_type dtype: string - name: text_style dtype: string - name: profession dtype: string - name: task_description dtype: string - name: task_hypotheses sequence: string splits: - name: train num_bytes: 186470635 num_examples: 156096 download_size: 29446549 dataset_size: 186470635 - config_name: mixtral_written_texts_for_tasks_v3 features: - name: hypothesis dtype: string - name: text dtype: string - name: labels dtype: int64 - name: text_type dtype: string - name: text_style dtype: string - name: profession dtype: string - name: task_description dtype: string - name: task_hypotheses sequence: string - name: prompt_and_tasks_version dtype: string - name: prompt_formatted dtype: string splits: - name: train num_bytes: 1610534901 num_examples: 679516 download_size: 131534115 dataset_size: 1610534901 - config_name: mixtral_written_texts_for_tasks_v4 features: - name: hypothesis dtype: string - name: text dtype: string - name: labels dtype: int64 - name: text_type dtype: string - name: text_style dtype: string - name: profession dtype: string - name: task_description dtype: string - name: task_hypotheses sequence: string - name: prompt_and_tasks_version dtype: string - name: prompt_formatted dtype: string splits: - name: train num_bytes: 726038875 num_examples: 308586 download_size: 68208727 dataset_size: 726038875 configs: - config_name: mixtral_refinedweb_categories data_files: - split: train path: mixtral_refinedweb_categories/train-* - config_name: mixtral_refinedweb_characteristics data_files: - split: train path: mixtral_refinedweb_characteristics/train-* - config_name: mixtral_refinedweb_nli data_files: - split: train path: mixtral_refinedweb_nli/train-* - config_name: mixtral_written_texts_for_tasks data_files: - split: train path: mixtral_written_texts_for_tasks/train-* - config_name: mixtral_written_texts_for_tasks_v2 data_files: - split: train path: mixtral_written_texts_for_tasks_v2/train-* - config_name: mixtral_written_texts_for_tasks_v3 data_files: - split: train path: mixtral_written_texts_for_tasks_v3/train-* - config_name: mixtral_written_texts_for_tasks_v4 data_files: - split: train path: mixtral_written_texts_for_tasks_v4/train-* ---
The dataset includes multiple configurations, each with different features and data files. The main features include hypothesis, text, labels, etc. The dataset is divided into multiple versions, each with a training set (train), and provides data size and download size.
数据集概述
数据集配置
1. mixtral_refinedweb_categories
- 特征:
hypothesis: 字符串text: 字符串labels: 64位整数category: 字符串
- 分割:
train:- 字节数: 679252117
- 样本数: 739362
- 下载大小: 93960048
- 数据集大小: 679252117
2. mixtral_refinedweb_characteristics
- 特征:
hypothesis: 字符串text: 字符串labels: 64位整数
- 分割:
train:- 字节数: 508301784
- 样本数: 543242
- 下载大小: 76811839
- 数据集大小: 508301784
3. mixtral_refinedweb_nli
- 特征:
hypothesis: 字符串text: 字符串labels: 64位整数hypo_topic: 字符串topic_id: 64位整数topic_prob: 64位浮点数__index_level_0__: 64位整数
- 分割:
train:- 字节数: 99039674
- 样本数: 94428
- 下载大小: 60993629
- 数据集大小: 99039674
4. mixtral_written_texts_for_tasks
- 特征:
hypothesis: 字符串text: 字符串labels: 64位整数text_type: 字符串text_style: 字符串profession: 字符串task_description: 字符串task_hypotheses: 序列字符串
- 分割:
train:- 字节数: 117675112
- 样本数: 105806
- 下载大小: 17224265
- 数据集大小: 117675112
5. mixtral_written_texts_for_tasks_v2
- 特征:
hypothesis: 字符串text: 字符串labels: 64位整数text_type: 字符串text_style: 字符串profession: 字符串task_description: 字符串task_hypotheses: 序列字符串
- 分割:
train:- 字节数: 186470635
- 样本数: 156096
- 下载大小: 29446549
- 数据集大小: 186470635
6. mixtral_written_texts_for_tasks_v3
- 特征:
hypothesis: 字符串text: 字符串labels: 64位整数text_type: 字符串text_style: 字符串profession: 字符串task_description: 字符串task_hypotheses: 序列字符串prompt_and_tasks_version: 字符串prompt_formatted: 字符串
- 分割:
train:- 字节数: 1610534901
- 样本数: 679516
- 下载大小: 131534115
- 数据集大小: 1610534901
7. mixtral_written_texts_for_tasks_v4
- 特征:
hypothesis: 字符串text: 字符串labels: 64位整数text_type: 字符串text_style: 字符串profession: 字符串task_description: 字符串task_hypotheses: 序列字符串prompt_and_tasks_version: 字符串prompt_formatted: 字符串
- 分割:
train:- 字节数: 726038875
- 样本数: 308586
- 下载大小: 68208727
- 数据集大小: 726038875
数据文件路径
mixtral_refinedweb_categories:train:mixtral_refinedweb_categories/train-*
mixtral_refinedweb_characteristics:train:mixtral_refinedweb_characteristics/train-*
mixtral_refinedweb_nli:train:mixtral_refinedweb_nli/train-*
mixtral_written_texts_for_tasks:train:mixtral_written_texts_for_tasks/train-*
mixtral_written_texts_for_tasks_v2:train:mixtral_written_texts_for_tasks_v2/train-*
mixtral_written_texts_for_tasks_v3:train:mixtral_written_texts_for_tasks_v3/train-*
mixtral_written_texts_for_tasks_v4:train:mixtral_written_texts_for_tasks_v4/train-*