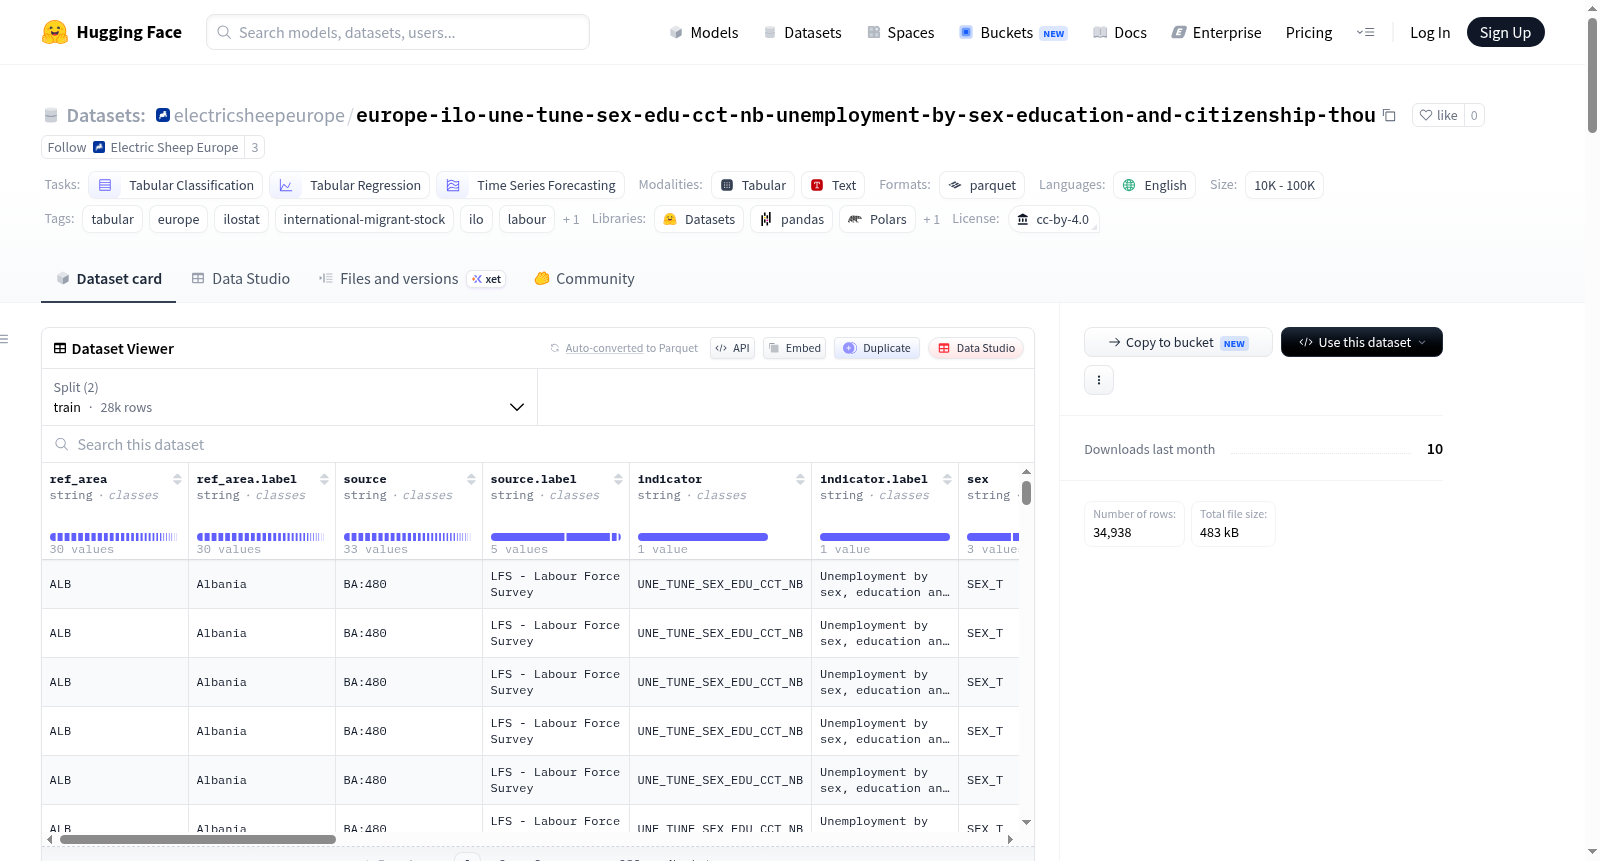
electricsheepeurope/europe-ilo-une-tune-sex-edu-cct-nb-unemployment-by-sex-education-and-citizenship-thou
收藏资源简介:
--- license: cc-by-4.0 language: - en task_categories: - tabular-classification - tabular-regression - time-series-forecasting multilinguality: monolingual size_categories: - 10K<n<100K tags: - tabular - europe - ilostat - international-migrant-stock - ilo - labour - employment pretty_name: "Unemployment by sex, education and citizenship (thousands) | Europe (ILOSTAT)" --- # Unemployment by sex, education and citizenship (thousands) | Europe (ILOSTAT) 🇪🇺 **34,938 observations** · **38 Europe countries** · **1991–2025** · *Repackaged by [Electric Sheep Europe](https://huggingface.co/electricsheepeurope)*      ## TL;DR This dataset contains **34,938 observations** of `International migrant stock` data across **38 Europe countries**, spanning **1991–2025**, covering **1 distinct indicators**. ## About the source **ILOSTAT** is the ILO's central statistics database, the leading global source for labour statistics. It compiles indicators across employment, unemployment, wages, working time, child labour, informal economy, social protection, occupational injuries, and SDG decent work targets — drawing on national labour force surveys, household income surveys, establishment surveys, and administrative records. Coverage spans 200+ economies, with the ILO's Department of Statistics responsible for harmonisation. - **Source:** [ILOSTAT](https://www.ilo.org/shinyapps/bulkexplorer/?id=UNE_TUNE_SEX_EDU_CCT_NB) - **Publisher:** International Labour Organization (ILO) - **License:** [cc-by-4.0](https://creativecommons.org/licenses/by/4.0/) - **Topic:** International migrant stock ## Methodology Data pulled directly from the ILOSTAT REST API at `https://rplumber.ilo.org/data/indicator?id=UNE_TUNE_SEX_EDU_CCT_NB` and filtered to Europe ISO3 country codes. ILOSTAT harmonises raw survey microdata using ICLS (International Conference of Labour Statisticians) definitions; sources are flagged in the `source.label` column for traceability. ## Geographic coverage 38 Europe countries · top rows shown below, sorted by row count: | Country | Rows | First year | Last year | |---------|-----:|-----------:|----------:| | `GRC` | 1,617 | 1992 | 2025 | | `SWE` | 1,509 | 1995 | 2024 | | `GBR` | 1,484 | 1995 | 2025 | | `NLD` | 1,450 | 1996 | 2024 | | `FRA` | 1,426 | 1995 | 2024 | | `CHE` | 1,418 | 1991 | 2025 | | `BEL` | 1,383 | 1995 | 2024 | | `ESP` | 1,328 | 1995 | 2025 | | `DEU` | 1,312 | 1995 | 2024 | | `NOR` | 1,260 | 1996 | 2024 | | `PRT` | 1,254 | 1995 | 2025 | | `IRL` | 1,241 | 1999 | 2024 | | `DNK` | 1,238 | 1995 | 2024 | | `AUT` | 1,139 | 1995 | 2025 | | `LUX` | 1,118 | 1995 | 2024 | | ... | _23 more countries_ | | | ## Indicators (sample) - `UNE_TUNE_SEX_EDU_CCT_NB` — Unemployment by sex, education and citizenship (thousands) ## Schema | Column | Type | Description | Example | |--------|------|-------------|---------| | `ref_area` | `string` | ISO 3166-1 alpha-3 country code | `ALB` | | `ref_area.label` | `string` | Country name in English | `Albania` | | `source` | `string` | ILOSTAT source code (e.g. labour force survey) | `BA:480` | | `source.label` | `string` | Source name in English | `LFS - Labour Force Survey` | | `indicator` | `string` | ILOSTAT indicator code | `UNE_TUNE_SEX_EDU_CCT_NB` | | `indicator.label` | `string` | Indicator name in English | `Unemployment by sex, education and ci…` | | `sex` | `string` | Disaggregation by sex (SEX_T = total, SEX_M = male, SEX_F = female) | `SEX_T` | | `sex.label` | `string` | — | `Total` | | `classif1` | `string` | First classification variable (age, education, status, etc.) | `EDU_AGGREGATE_TOTAL` | | `classif1.label` | `string` | — | `Education (Aggregate levels): Total` | | `classif2` | `string` | Second classification variable where applicable | `CCT_CIT_TOTAL` | | `classif2.label` | `string` | — | `Citizenship: Total` | | `time` | `int64` | Observation year | `2024` | | `obs_value` | `float64` | Observed indicator value (unit varies — see indicator definition) | `108.247` | | `obs_status` | `string` | Observation status flag (e.g. provisional, unreliable) | `U` | | `obs_status.label` | `string` | — | `Unreliable` | | `note_classif` | `string` | — | `C3:5578` | | `note_classif.label` | `string` | — | `Nonstandard education level: Includin…` | | `note_indicator` | `string` | — | `I11:264` | | `note_indicator.label` | `string` | — | `Break in series: Methodology revised` | | `note_source` | `string` | — | `R1:3513` | | `note_source.label` | `string` | — | `Repository: ILO-STATISTICS - Micro da…` | ## Disaggregation dimensions The following columns provide disaggregation dimensions: - **`sex`** (3 unique values): `SEX_T`, `SEX_M`, `SEX_F` ## Data quality & caveats - Data is annual frequency. Some indicators also publish monthly or quarterly series — those are not included here. - When an indicator has multiple sources for the same country×year, the ILO-selected 'best source' is used. - Disaggregation columns (`sex`, `classif1`, `classif2`) are non-null only when the indicator publishes that breakdown. ## Usage ```python from datasets import load_dataset ds = load_dataset("electricsheepeurope/europe-ilo-une-tune-sex-edu-cct-nb-unemployment-by-sex-education-and-citizenship-thou") df = ds["train"].to_pandas() print(df.head()) ``` ### Filter to one country ```python germany = df[df["ref_area"] == "DEU"] ``` ### Time-series for a single indicator ```python sample = (df[df["indicator"] == "UNE_TUNE_SEX_EDU_CCT_NB"] .sort_values("time")) sample.plot(x="time", y="obs_value", title="UNE_TUNE_SEX_EDU_CCT_NB") ``` ### Pivot to country × year matrix ```python matrix = (df[df["indicator"] == "UNE_TUNE_SEX_EDU_CCT_NB"] .pivot_table(index="time", columns="ref_area", values="obs_value")) print(matrix.tail()) ``` ## Citation ```bibtex @misc{europe_ilo_une_tune_sex_edu_cct_nb_unemployment_by_sex_education_and_citizenship_thou_2025, title = {Unemployment by sex, education and citizenship (thousands) | Europe (ILOSTAT)}, author = {International Labour Organization (ILO)}, year = {2025}, url = {https://www.ilo.org/shinyapps/bulkexplorer/?id=UNE_TUNE_SEX_EDU_CCT_NB}, publisher = {HuggingFace Datasets, repackaged by Electric Sheep Europe}, howpublished = {\url{https://huggingface.co/datasets/electricsheepeurope/europe-ilo-une-tune-sex-edu-cct-nb-unemployment-by-sex-education-and-citizenship-thou}} } ``` ## License Released under [cc-by-4.0](https://creativecommons.org/licenses/by/4.0/). Original data © International Labour Organization (ILO). When using this dataset, please cite both the original source above and the Electric Sheep Europe repackaging. ## About Electric Sheep Electric Sheep Europe is part of the Electric Sheep mission: a unified, ML-ready data layer for Europe on HuggingFace. We pull data from authoritative open sources, normalize the schemas, package as Parquet, and publish with consistent dataset cards so researchers and developers can use `load_dataset()` to start working in seconds. Browse the full collection: [huggingface.co/electricsheepeurope](https://huggingface.co/electricsheepeurope) --- _Provenance: ingested 2026-05-27 via the Electric Sheep pipeline. Source URL: https://www.ilo.org/shinyapps/bulkexplorer/?id=UNE_TUNE_SEX_EDU_CCT_NB_
许可证: cc-by-4.0 语言: - 英语 任务类别: - 表格分类 - 表格回归 - 时间序列预测 多语言属性: 单语言 数据规模: - 10000 < 样本数 < 100000 标签: - 表格数据 - 欧洲 - ILOSTAT - 国际移民存量 - 国际劳工组织(ILO) - 劳工 - 就业 展示名称: "分性别、受教育程度与公民身份的失业人数(千人)| 欧洲(ILOSTAT)" # 分性别、受教育程度与公民身份的失业人数(千人)| 欧洲(ILOSTAT) 🇪🇺 **34,938条观测** · **38个欧洲国家** · **1991–2025年** · *由[Electric Sheep Europe](https://huggingface.co/electricsheepeurope)重新整理*      ## 核心摘要 本数据集涵盖38个欧洲国家1991年至2025年的`国际移民存量`相关数据,共计**34,938条观测样本**,包含**1个独立指标**。 ## 数据源说明 **国际劳工组织统计数据库(ILOSTAT)** 是国际劳工组织(ILO)的核心统计数据库,为全球领先的劳工统计权威来源。其收录指标覆盖就业、失业、薪资、工作时长、童工、非正规经济、社会保障、职业伤害以及可持续发展目标体面工作目标等领域,数据来源于全国劳动力调查、家庭收入调查、机构调查与行政记录。该数据库覆盖全球200余个经济体,数据标准化整合工作由国际劳工组织统计司负责。 - **数据源地址:** [ILOSTAT](https://www.ilo.org/shinyapps/bulkexplorer/?id=UNE_TUNE_SEX_EDU_CCT_NB) - **发布方:** 国际劳工组织(ILO) - **许可证:** [cc-by-4.0](https://creativecommons.org/licenses/by/4.0/) - **数据主题:** 国际移民存量 ## 数据处理方法 数据直接从ILOSTAT的REST API接口`https://rplumber.ilo.org/data/indicator?id=UNE_TUNE_SEX_EDU_CCT_NB`拉取,并筛选出欧洲地区的ISO3国家代码数据集。ILOSTAT采用国际劳工统计学家会议(ICLS)的定义对原始调查微观数据进行标准化整合;数据源信息将在`source.label`列中标记,以确保数据可追溯。 ## 地理覆盖范围 38个欧洲国家 · 以下按数据行数排序展示部分国家的信息: | 国家代码 | 数据行数 | 起始年份 | 结束年份 | |---------|-----:|-----------:|----------:| | `GRC` | 1,617 | 1992 | 2025 | | `SWE` | 1,509 | 1995 | 2024 | | `GBR` | 1,484 | 1995 | 2025 | | `NLD` | 1,450 | 1996 | 2024 | | `FRA` | 1,426 | 1995 | 2024 | | `CHE` | 1,418 | 1991 | 2025 | | `BEL` | 1,383 | 1995 | 2024 | | `ESP` | 1,328 | 1995 | 2025 | | `DEU` | 1,312 | 1995 | 2024 | | `NOR` | 1,260 | 1996 | 2024 | | `PRT` | 1,254 | 1995 | 2025 | | `IRL` | 1,241 | 1999 | 2024 | | `DNK` | 1,238 | 1995 | 2024 | | `AUT` | 1,139 | 1995 | 2025 | | `LUX` | 1,118 | 1995 | 2024 | | ... | 其余23个国家 | | | ## 指标示例 - `UNE_TUNE_SEX_EDU_CCT_NB` — 分性别、受教育程度与公民身份的失业人数(千人) ## 数据结构 | 列名 | 数据类型 | 字段描述 | 示例值 | |--------|------|-------------|---------| | `ref_area` | `string` | ISO 3166-1 alpha-3 国家代码 | `ALB` | | `ref_area.label` | `string` | 英语国家名称 | `Albania` | | `source` | `string` | ILOSTAT 数据源代码(例如劳动力调查) | `BA:480` | | `source.label` | `string` | 英语数据源名称 | `LFS - 劳动力调查` | | `indicator` | `string` | ILOSTAT 指标代码 | `UNE_TUNE_SEX_EDU_CCT_NB` | | `indicator.label` | `string` | 英语指标名称 | `Unemployment by sex, education and ci…` | | `sex` | `string` | 性别细分维度(SEX_T = 总计,SEX_M = 男性,SEX_F = 女性) | `SEX_T` | | `sex.label` | `string` | — | `总计` | | `classif1` | `string` | 第一分类变量(年龄、教育程度、身份等) | `EDU_AGGREGATE_TOTAL` | | `classif1.label` | `string` | — | `教育程度(汇总级别):总计` | | `classif2` | `string` | 可选第二分类变量 | `CCT_CIT_TOTAL` | | `classif2.label` | `string` | — | `公民身份:总计` | | `time` | `int64` | 观测年份 | `2024` | | `obs_value` | `float64` | 观测指标值(单位详见指标定义) | `108.247` | | `obs_status` | `string` | 观测状态标记(例如临时、不可靠) | `U` | | `obs_status.label` | `string` | — | `不可靠` | | `note_classif` | `string` | — | `C3:5578` | | `note_classif.label` | `string` | — | `非标准教育水平:包含…` | | `note_indicator` | `string` | — | `I11:264` | | `note_indicator.label` | `string` | — | `序列中断:方法学修订` | | `note_source` | `string` | — | `R1:3513` | | `note_source.label` | `string` | — | `存储库:ILO统计司 - 微观数据…` | ## 数据细分维度 以下列提供数据的细分维度: - **`sex`**(共3个唯一值):`SEX_T`、`SEX_M`、`SEX_F` ## 数据质量与注意事项 - 数据为年度频率。部分指标同时发布月度或季度序列,本数据集未包含此类数据。 - 当同一国家×年份的同一指标存在多个数据源时,将采用国际劳工组织选定的“最优数据源”。 - 细分列(`sex`、`classif1`、`classif2`)仅在指标支持对应细分维度时才非空。 ## 使用示例 python from datasets import load_dataset ds = load_dataset("electricsheepeurope/europe-ilo-une-tune-sex-edu-cct-nb-unemployment-by-sex-education-and-citizenship-thou") df = ds["train"].to_pandas() print(df.head()) ### 筛选单个国家 python germany = df[df["ref_area"] == "DEU"] ### 单个指标的时间序列 python sample = (df[df["indicator"] == "UNE_TUNE_SEX_EDU_CCT_NB"] .sort_values("time")) sample.plot(x="time", y="obs_value", title="UNE_TUNE_SEX_EDU_CCT_NB") ### 转换为国家×年份矩阵 python matrix = (df[df["indicator"] == "UNE_TUNE_SEX_EDU_CCT_NB"] .pivot_table(index="time", columns="ref_area", values="obs_value")) print(matrix.tail()) ## 引用格式 bibtex @misc{europe_ilo_une_tune_sex_edu_cct_nb_unemployment_by_sex_education_and_citizenship_thou_2025, title = {分性别、受教育程度与公民身份的失业人数(千人)| 欧洲(ILOSTAT)}, author = {国际劳工组织(ILO)}, year = {2025}, url = {https://www.ilo.org/shinyapps/bulkexplorer/?id=UNE_TUNE_SEX_EDU_CCT_NB}, publisher = {HuggingFace Datasets,由Electric Sheep Europe重新整理发布}, howpublished = {url{https://huggingface.co/datasets/electricsheepeurope/europe-ilo-une-tune-sex-edu-cct-nb-unemployment-by-sex-education-and-citizenship-thou}} } ## 许可证 本数据集采用[CC BY 4.0](https://creativecommons.org/licenses/by/4.0/)许可发布。 原始数据 © 国际劳工组织(ILO)。使用本数据集时,请同时引用上述原始数据源与Electric Sheep Europe的重新整理版本。 ## 关于Electric Sheep Electric Sheep Europe是Electric Sheep项目的欧洲分支,旨在构建统一的、适用于机器学习的欧洲数据层,托管于HuggingFace平台。我们从权威开源数据源获取数据,对其schema进行标准化处理,打包为Parquet格式,并发布格式统一的数据集卡片,使研究人员与开发者可通过`load_dataset()`函数在数秒内启动工作。 浏览完整数据集集合:[huggingface.co/electricsheepeurope](https://huggingface.co/electricsheepeurope) _数据溯源:2026年5月27日通过Electric Sheep流水线摄取。源URL:https://www.ilo.org/shinyapps/bulkexplorer/?id=UNE_TUNE_SEX_EDU_CCT_NB_