
WeiChow/cc3m
收藏官方服务:
资源简介:
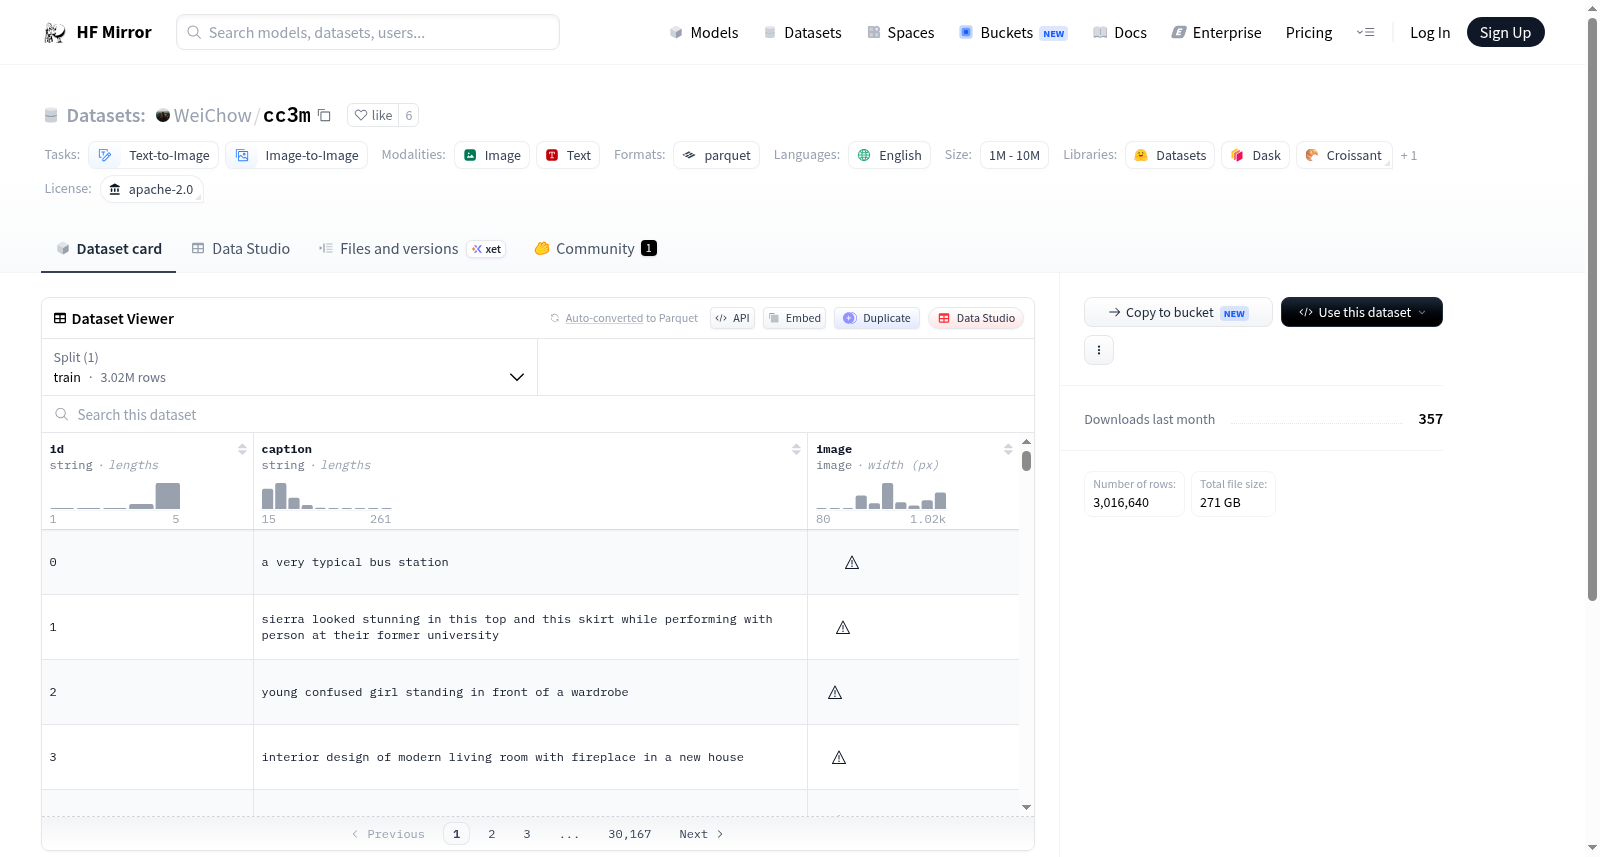
CC3M数据集是一个包含文本和图像的数据集,适用于文本到图像和图像到图像的任务。数据集包含了大约3016640个训练样本,每个样本包括一个唯一的id,一段文本描述(caption),以及与之对应的图像。图像如果大于1024x1024像素,会被缩放到1024x1024。数据集使用Apache-2.0许可。
CC3M dataset is a collection of text and images suitable for text-to-image and image-to-image tasks. It contains approximately 3,016,640 training samples, each with a unique id, a text description (caption), and the corresponding image. Images larger than 1024x1024 pixels are resized to 1024x1024. The dataset is licensed under Apache-2.0.
提供机构:
WeiChow搜集汇总
数据集介绍
背景与挑战
背景概述
该数据集是一个大规模多模态数据集,包含约300万条数据行,主要用于文本到图像和图像到图像任务。数据集由图像和对应的英语文本描述组成,图像经过预处理(如尺寸调整至不超过1024x1024像素),并以parquet格式存储。
以上内容由遇见数据集搜集并总结生成


