eval-whisper-tiny-multimed-hard-20260408-1930
收藏资源简介:
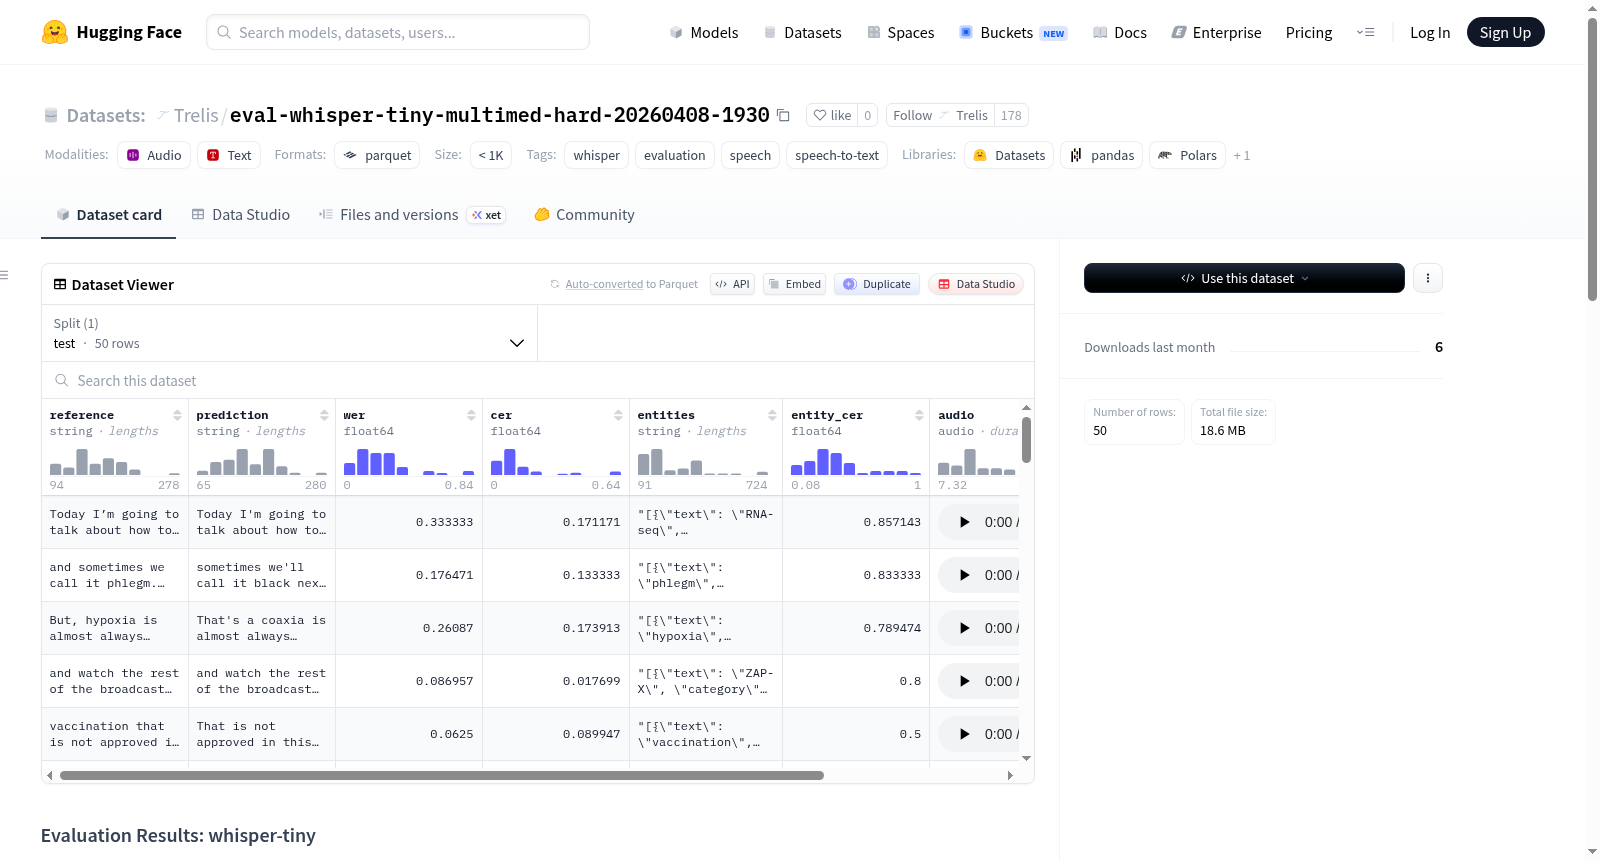
该数据集包含对 Whisper-tiny 模型在 Trelis/multimed-hard 数据集上的评估结果。数据集主要用于语音到文本模型的性能评估,重点关注转录准确性和实体识别。数据内容包括音频样本(如果源数据集提供)、参考转录文本、模型预测文本、词错误率(WER)、字符错误率(CER)、实体标注以及每个样本的实体字符错误率(Entity CER)。评估结果显示,整体字符错误率为14.36%,词错误率为23.56%,实体字符错误率为36.03%。不同类别的实体识别准确率有所差异,其中药物类别的识别准确率最高(CER为7.14%),而组织类别的识别准确率最低(CER为40.59%)。该数据集适用于语音识别模型的性能评估和比较研究。
This dataset contains the evaluation results of the Whisper-tiny model on the Trelis/multimed-hard dataset. It is primarily designed for performance evaluation of speech-to-text models, with a focus on transcription accuracy and entity recognition. The dataset includes audio samples (if provided by the original source dataset), reference transcriptions, model-predicted transcriptions, Word Error Rate (WER), Character Error Rate (CER), entity annotations, and Entity Character Error Rate (Entity CER) for each individual sample. The evaluation results indicate that the overall Character Error Rate is 14.36%, Word Error Rate is 23.56%, and Entity Character Error Rate is 36.03%. Recognition accuracy varies across different entity categories: the medication category achieves the highest recognition accuracy with a CER of 7.14%, while the organization category has the lowest recognition accuracy with a CER of 40.59%. This dataset is suitable for performance evaluation and comparative research of speech recognition models.