
Long Code Arena
收藏资源简介:
Long Code Arena是由捷德布莱恩斯研究和德尔福特理工大学联合开发的一套包含六个数据集的基准,旨在评估需要项目级上下文的代码处理模型。这些数据集涵盖了代码生成、修复、完成、摘要、处理差异等多个方面,数据来源于开放源代码的GitHub仓库,确保了数据的质量和多样性。创建过程中,数据经过严格的筛选和人工验证,以保证其准确性。该数据集主要应用于机器学习在软件工程领域的研究,特别是在需要长上下文处理的代码模型评估中,解决了现有基准在上下文长度和实际应用案例相似性方面的局限性。
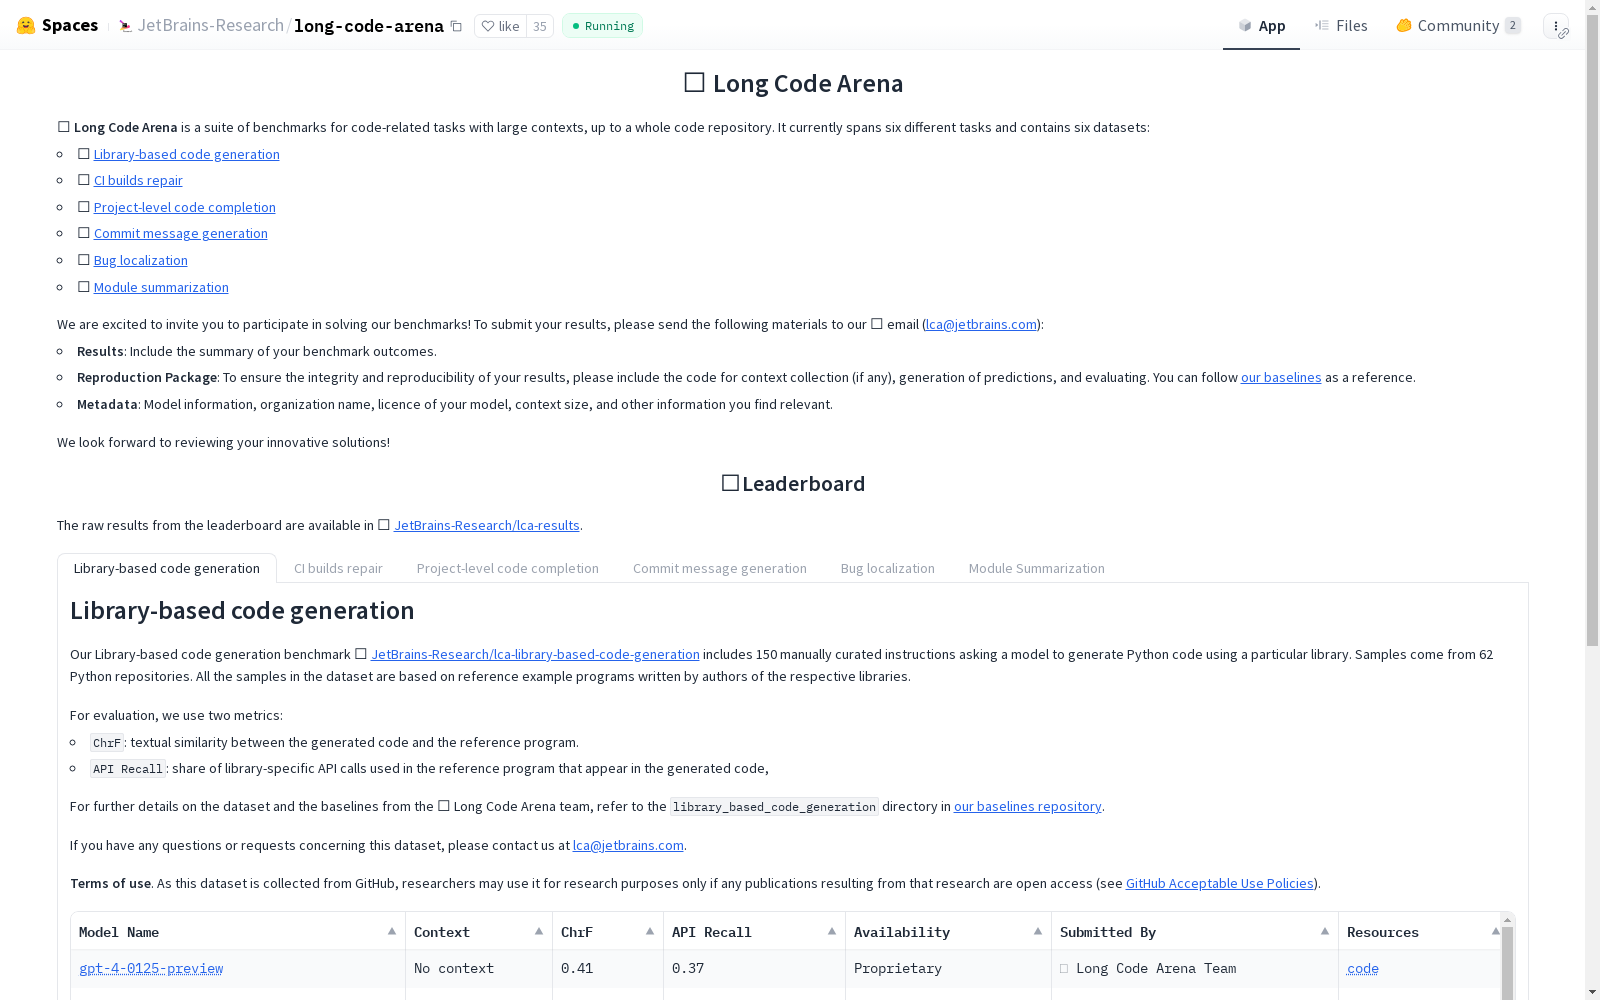
Long Code Arena is a benchmark suite composed of six datasets, co-developed by Jed Bryans Research and Delft University of Technology. It is designed to evaluate code processing models that necessitate project-level context. These datasets cover a wide range of tasks including code generation, code repair, code completion, code summarization, and diff processing. All data is sourced from open-source GitHub repositories, which guarantees both the quality and diversity of the benchmark. During its development, the data underwent rigorous screening and manual validation to ensure its accuracy. This benchmark is primarily used for machine learning research in the field of software engineering, especially for evaluating code models that require long-context processing, and it addresses the limitations of existing benchmarks regarding context length and similarity to real-world application scenarios.
- 1Long Code Arena: a Set of Benchmarks for Long-Context Code Models捷德布莱恩斯研究 · 2024年


