open-india-law
收藏资源简介:
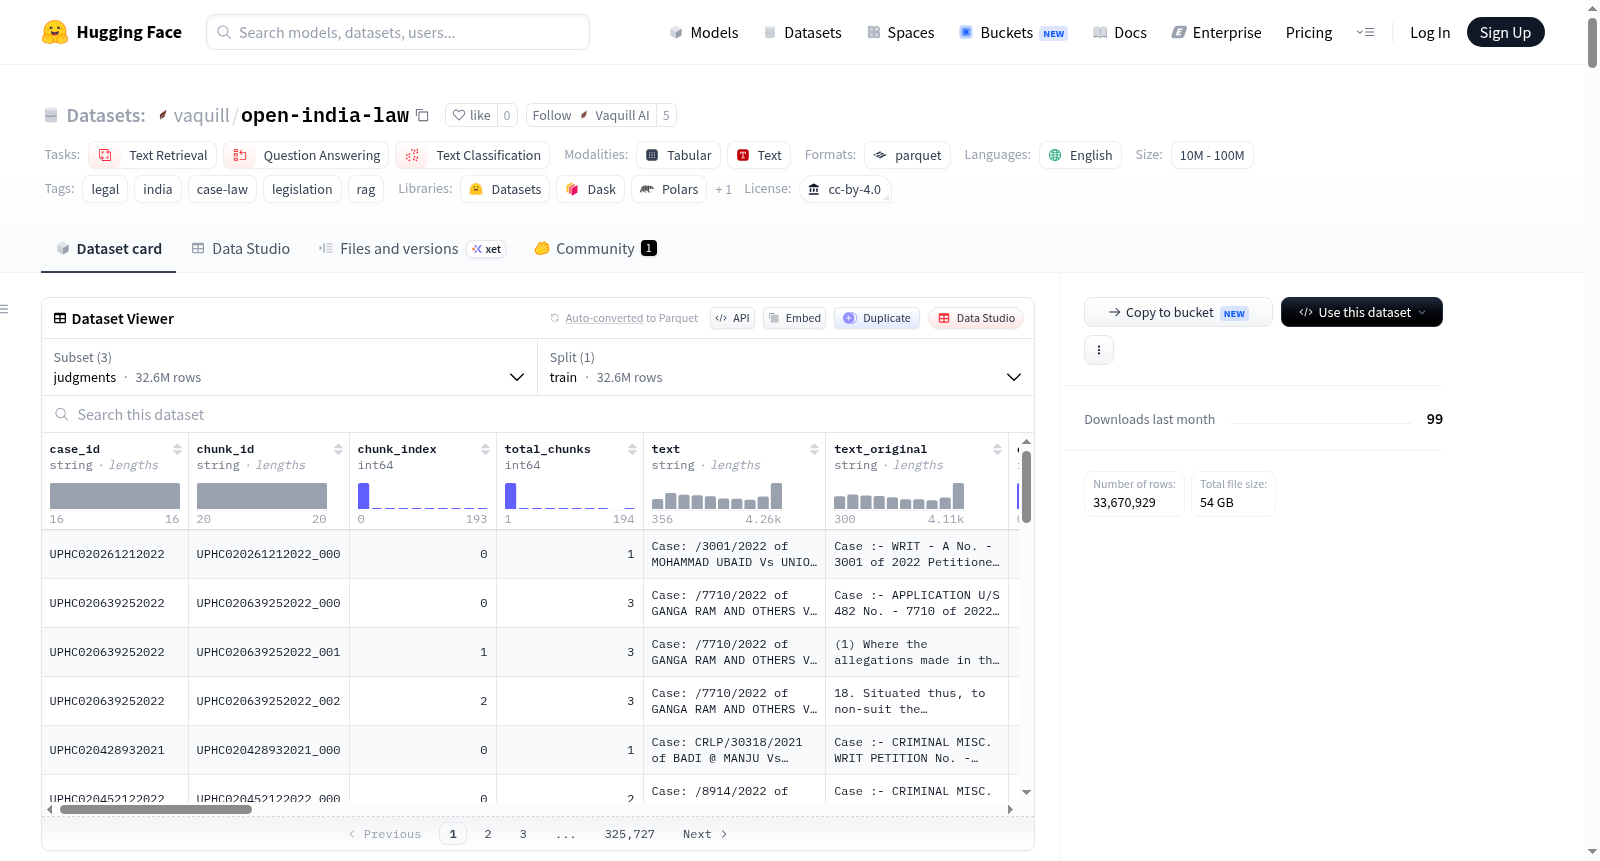
Open India Law 是一个开放、结构化的印度主要法律数据集。它涵盖了印度最高法院和全部25个高等法院的所有判决、15个法庭和监管机构的决定,以及中央、各邦和联邦属地的立法,细化到单独章节。数据全部来自官方政府来源,并统一为单一模式。数据集包含:法院判决12,848,644份(1950-2025年)、法庭和监管事项813,168份(1985-2026年)、法令22,265部(1806-2026年)、立法章节1,098,577条(可单独搜索)。不包括地区法院和初审法院判决。数据以Parquet格式存储,可通过HuggingFace Datasets库加载(支持judgments、legislation、regulations三个配置)。此外,还提供了基于Voyage AI voyage-4系列嵌入的Qdrant向量快照(共约3250万向量),支持混合搜索。数据集适用于文本检索、问答、文本分类等任务,特别适用于法律领域的RAG(检索增强生成)应用。语言为英语,许可证为CC-BY-4.0。
Open India Law is an open, structured dataset of Indian primary legal materials. It covers all judgments of the Supreme Court and all 25 High Courts, decisions of 15 tribunals and regulatory bodies, and legislation from the central government, states, and union territories, down to individual sections. All data is sourced from official government sources and unified into a single schema. The dataset includes: 12,848,644 court judgments (1950-2025), 813,168 tribunal and regulatory matters (1985-2026), 22,265 statutes (1806-2026), and 1,098,577 legislative sections (searchable individually). It does not include district court or trial court judgments. Data is stored in Parquet format and can be loaded via the HuggingFace Datasets library (with three configurations: judgments, legislation, regulations). Additionally, it provides Qdrant vector snapshots based on Voyage AI voyage-4 series embeddings (approximately 32.5 million vectors), supporting hybrid search. The dataset is suitable for tasks such as text retrieval, question answering, and text classification, especially for RAG (Retrieval-Augmented Generation) applications in the legal domain. Language: English. License: CC-BY-4.0.
Open India Law 数据集概述
基本信息
- 数据集名称: Open India Law
- 许可证: CC-BY-4.0
- 语言: 英语
- 数据规模: 10M < n < 100M
- 任务类型: 文本检索、问答、文本分类
- 标签: 法律、印度、判例法、立法、检索增强生成(RAG)
数据内容
数据集包含印度主要法律资料,涵盖以下三类内容:
| 数据类型 | 数量 | 时间跨度 |
|---|---|---|
| 法院判决 | 12,848,644 条 | 1950–2025 |
| 法庭及监管机构案件 | 813,168 条 | 1985–2026 |
| 立法法案 | 22,265 部 | 1806–2026 |
| 立法条款 | 1,098,577 条(可独立检索) | — |
说明: 不包含地区和初审法院的判决。
数据配置
数据集提供三个配置,分别对应不同的数据文件:
- judgments:
in_*_judgments.parquet - legislation:
in_*_legislation.parquet - regulations:
in_*_regulations.parquet
法院判决数据
覆盖印度最高法院和全部 25 个高等法院,主要法院包括:
| 法院 | 判决数量 | 时间跨度 |
|---|---|---|
| 最高法院 | 34,954 | 1950–2025 |
| 巴特那高等法院 | 1,615,041 | 1967–2025 |
| 孟买高等法院 | 1,595,948 | 1953–2025 |
| 阿拉哈巴德高等法院 | 1,498,250 | 1992–2025 |
| 马德拉斯高等法院 | 1,494,952 | 1997–2025 |
| 特伦甘纳高等法院 | 1,004,138 | 1963–2025 |
| 喀拉拉高等法院 | 916,190 | 1950–2024 |
| 卡纳塔克高等法院 | 581,276 | 1998–2025 |
其余高等法院判决数量从 453 条至 508,791 条不等。
法庭和监管机构数据
涵盖 15 个法庭和监管机构,包括:
- 中央行政法庭(CAT)
- 关税、消费税和服务税上诉法庭(CESTAT)
- 所得税上诉法庭(ITAT)
- 债务追收法庭(DRT)
- 国家公司法法庭(NCLT)
- 国家绿色法庭(NGT)
- 证券上诉法庭(SAT)
- 电力上诉法庭(APTEL)
- 房地产监管机构(RERA)
- 电信争议解决和上诉法庭(TDSAT)等
重要说明: 法庭材料按案件索引,未提供全文。约 210 万份 PDF 无文本层,其中约 348,516 份为实质性裁定,需要 OCR 和解析处理。
监管机构数据
包含 12 个监管机构发布的法规文件,主要机构包括:
| 机构 | 文件数 | 条款数 |
|---|---|---|
| 公司事务部(MCA) | 2,666 | 46,480 |
| 印度储备银行(RBI) | 2,640 | 104,143 |
| 环境、森林和气候变化部(MOEFCC) | 1,399 | 116,227 |
| 对外贸易总局(DGFT) | 1,233 | 4,252 |
| 印度证券交易委员会(SEBI) | 1,144 | 88,310 |
| 印度电信监管局(TRAI) | 834 | 22,720 |
立法数据
数据来源于 India Code,涵盖中央和各邦/地区的立法:
- 中央立法: 13,720 部法案,628,863 条条款(1834–2026)
- 邦级立法: 涵盖 37 个司法辖区,从阿萨姆邦(987 部)到拉克沙群岛(1 部)不等
- 每条立法条款可独立检索,附带
source_url指向官方 PDF
数据获取方式
python from datasets import load_dataset
judgments = load_dataset("vaquill/open-india-law", "judgments", split="train") acts = load_dataset("vaquill/open-india-law", "legislation", split="train") regs = load_dataset("vaquill/open-india-law", "regulations", split="train")
快照版本 v2026.08: 26 个判决文件(32,572,660 个文本块,53.6 GB)、37 个立法文件和 12 个监管文件(共 1,098,269 条条款)。
向量嵌入
数据集附带了预生成的向量嵌入可供使用:
| 集合 | 向量数 | 分片数 | 大小 |
|---|---|---|---|
legal_corpus_v1 |
19,595,718 | 4 | 272.8 GB |
legal_corpus_v2 |
11,823,753 | 4 | 179.6 GB |
acts_india |
1,098,577 | 2 | 11.2 GB |
总计 32,518,048 个向量,463.6 GB。嵌入使用 Voyage AI voyage-4 系列模型,1024 维,余弦距离,支持 BM25 混合检索。
数据来源与溯源
- 仅使用政府官方来源,不包含商业法律报告或第三方聚合数据
- 每条记录保留来源 URL,可追溯到法院、法庭或政府发布机构
- 数据构建过程全部开源,包含爬虫和解析脚本
数据格式
每条立法记录包含字段:act_id、title、chapter、section_number、section_title、text、act_status、section_status、state、year、amendment_count、source_url
每条法庭记录包含字段:case_id、case_number、title、bench、judges、decision_date、year、doc_type、is_judgment、source_pdf_url