EarthSpeciesProject/animalspeak-pseudovox
收藏资源简介:
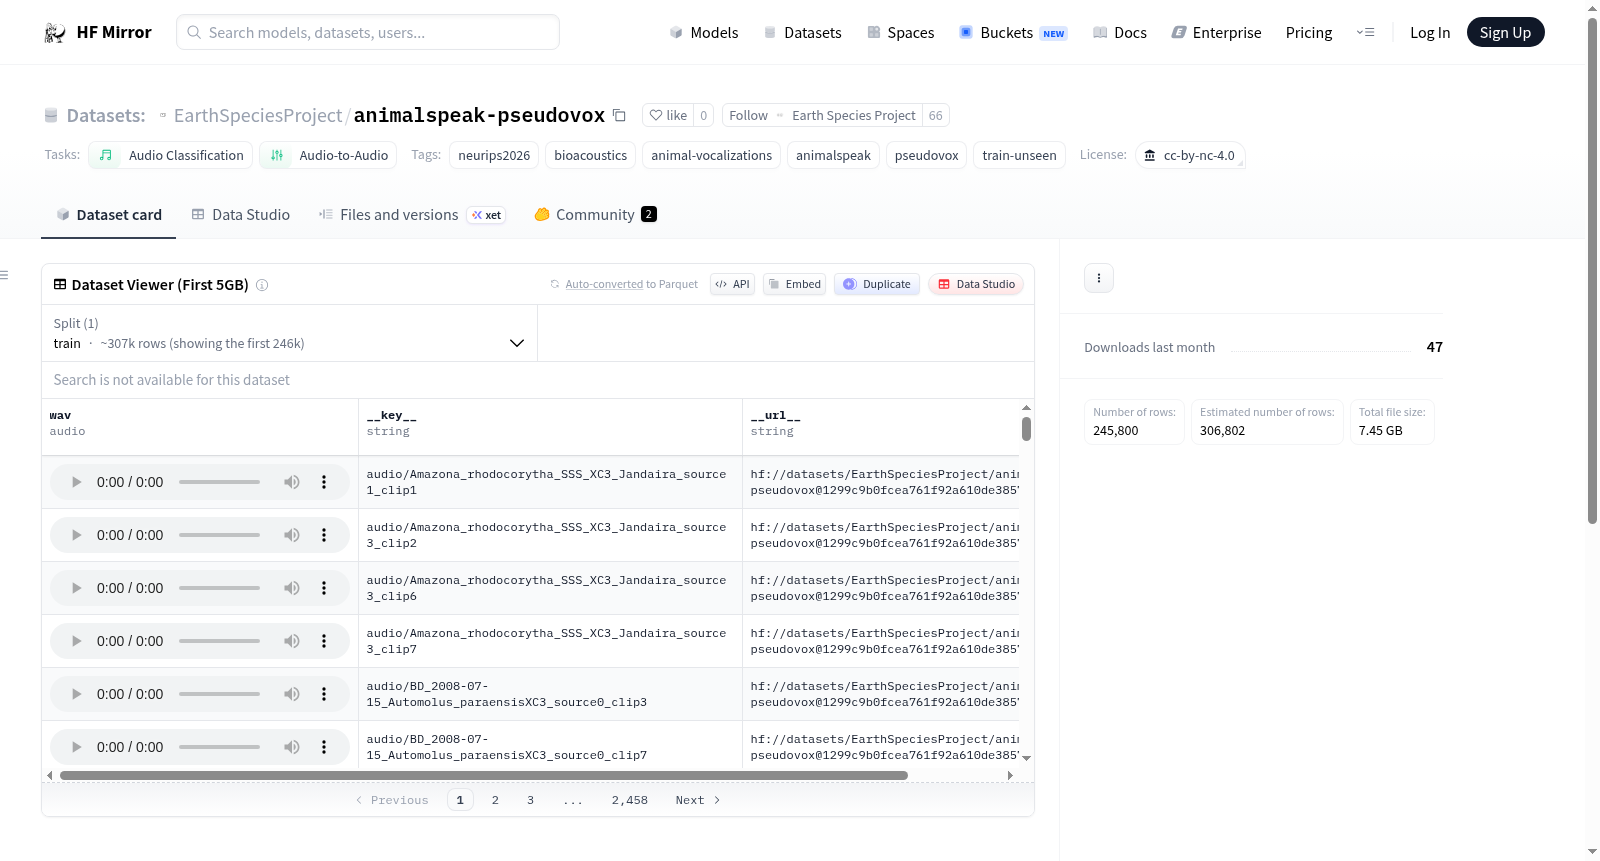
该数据集包含AnimalSpeak Pseudovox的train-unseen分割部分。每个示例都是一个经过静音修剪的短单发声WAV剪辑,附带紧凑的每剪辑元数据。数据集不包含生成的对话、字幕、问答对或多选题答案。数据集共有346,907行,分为18个分片,每个分片最多包含20,000行。文件包括WebDataset风格的分片(包含WAV音频条目)、每音频文件一行的元数据(包括ID、音频名称、持续时间、物种元数据和分类器置信度元数据)以及MLCommons Croissant元数据文件。
This dataset contains the train-unseen split of AnimalSpeak Pseudovox. Each example is a short, silence-trimmed single-vocalization WAV clip, accompanied by compact per-clip metadata. The dataset does not include generated dialogues, subtitles, question-answer pairs, or multiple-choice question answers. It has a total of 346,907 rows, divided into 18 shards, with each shard containing up to 20,000 rows. The included files are WebDataset-style shards (containing WAV audio entries), a metadata file with one row per audio file (including ID, audio name, duration, species metadata, and classifier confidence metadata), as well as an MLCommons Croissant metadata file.