laion/moss-character-voices-bestof64
收藏资源简介:
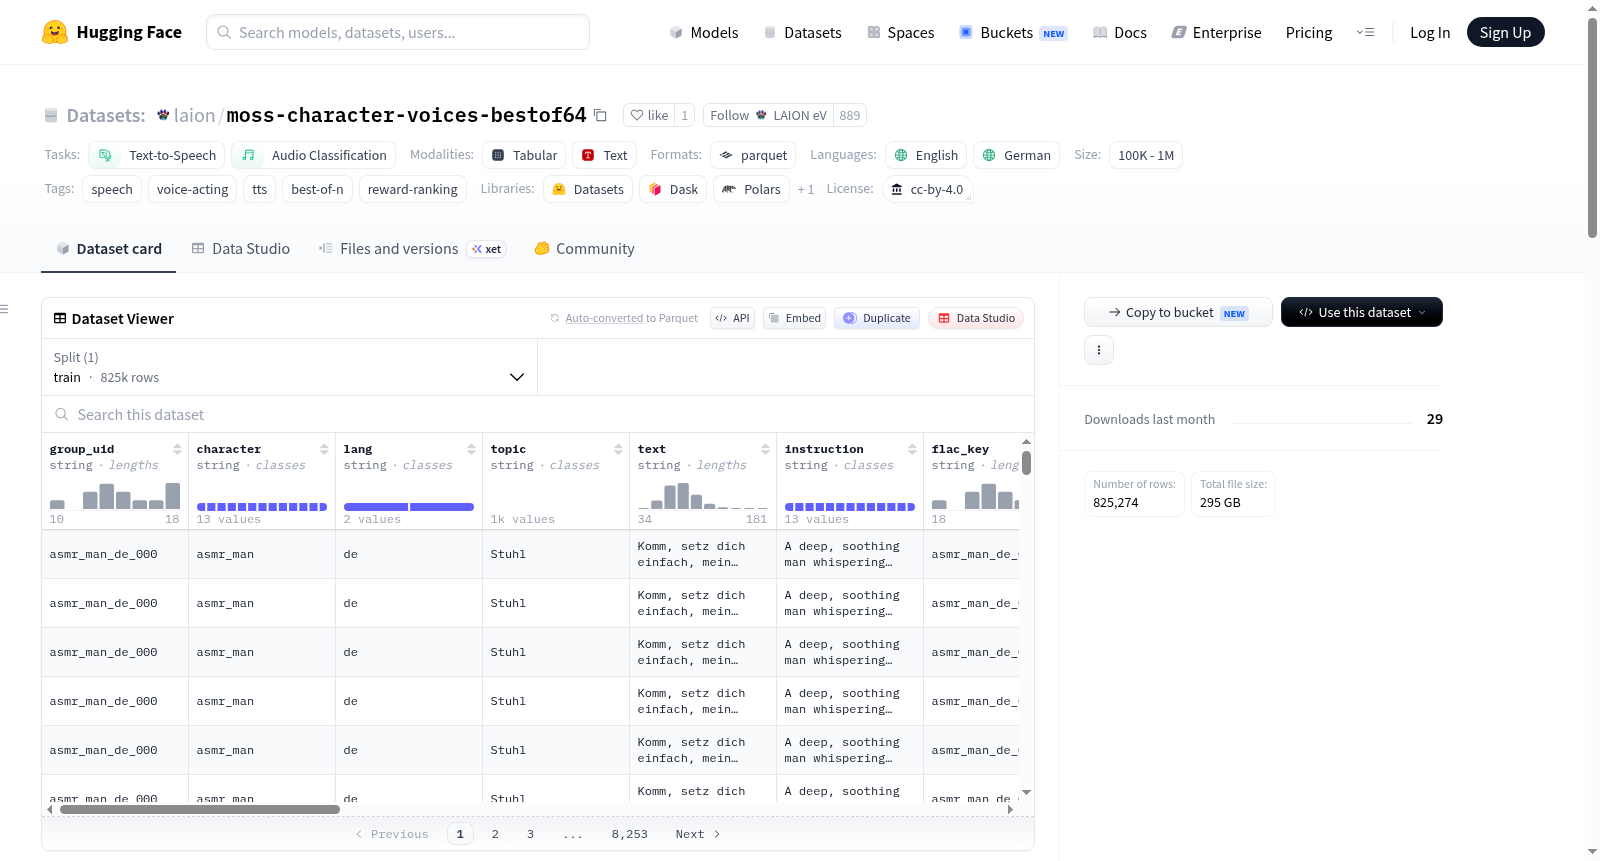
MOSS角色声音—最佳64(第二阶段)数据集是一个用于文本到语音(TTS)和音频分类任务的语音数据集,主要包含英语和德语内容。该数据集基于4.55B参数的MOSS-TTS-Local语音表演模型生成,涵盖了13个进化角色声音(如asmr_man、asmr_woman、dragon等)的语音样本。每个提示由一个固定的优化表演方向和Gemma生成的主题文本组成,每个提示采样64个不同的语音样本(使用不同种子生成,采样率为48 kHz)。每个样本通过多个评分模型(包括VoiceCLAP-commercial、57 VoiceNet、Per-character EmoNet和Parakeet-TDT ASR)进行评分,并根据每个角色的奖励值在组内排名(排名1为最佳)。数据以WebDataset格式组织,包括FLAC格式的音频文件和Parquet格式的元数据文件,其中元数据包含样本的详细信息如角色、语言、文本、排名、奖励值等。数据集规模目标为12,984组提示(约831,000个样本),占用约250-380 GB存储空间。许可证为CC-BY-4.0。
The MOSS Character Voice — Best 64 (Phase 2) Dataset is a speech dataset tailored for text-to-speech (TTS) and audio classification tasks, primarily consisting of English and German content. Generated based on the MOSS-TTS-Local speech performance model with 4.55 billion parameters, this dataset encompasses speech samples from 13 evolutionary character voices including asmr_man, asmr_woman, dragon, and others. Each prompt is composed of a fixed optimized performance direction and topic text generated by Gemma, with 64 distinct speech samples sampled per prompt (generated using different seeds, with a sampling rate of 48 kHz). Every sample is evaluated by multiple scoring models, namely VoiceCLAP-commercial, 57 VoiceNet, Per-character EmoNet, and Parakeet-TDT ASR, and ranked within its group based on the reward value of the corresponding character, where rank 1 denotes the highest quality. The dataset is structured in WebDataset format, comprising FLAC-encoded audio files and Parquet-format metadata files. The metadata includes detailed sample information such as character, language, source text, rank, reward value, and more. The target scale of the dataset is 12,984 prompt groups (approximately 831,000 total samples), occupying approximately 250–380 GB of storage space. The dataset is licensed under CC-BY-4.0.