PROCESSBENCH
收藏资源简介:
PROCESSBENCH是由阿里巴巴集团Qwen团队创建的一个用于评估数学推理过程中错误识别能力的数据集。该数据集包含3400个测试案例,主要涵盖竞赛和奥林匹克级别的数学问题。每个测试案例包含一个逐步解决方案,并由人类专家标注错误位置。数据集的创建过程包括从多个公开数据集中收集问题,使用多种开源语言模型生成解决方案,并通过专家注释确保数据质量。PROCESSBENCH旨在解决语言模型在复杂数学问题中自动识别错误步骤的需求,推动推理过程评估的研究。
PROCESSBENCH is a dataset developed by the Qwen Team of Alibaba Group for evaluating the capability of identifying errors in mathematical reasoning processes. It contains 3400 test cases, primarily covering competition-level and Olympiad-level mathematical problems. Each test case includes a step-by-step solution, with error positions annotated by human experts. The dataset creation workflow involves collecting problems from multiple public datasets, generating solutions using multiple open-source language models, and ensuring data quality via expert annotations. PROCESSBENCH aims to address the demand for automatically detecting erroneous steps in complex mathematical problems by language models, and to advance research on reasoning process evaluation.
ProcessBench 数据集概述
数据集简介
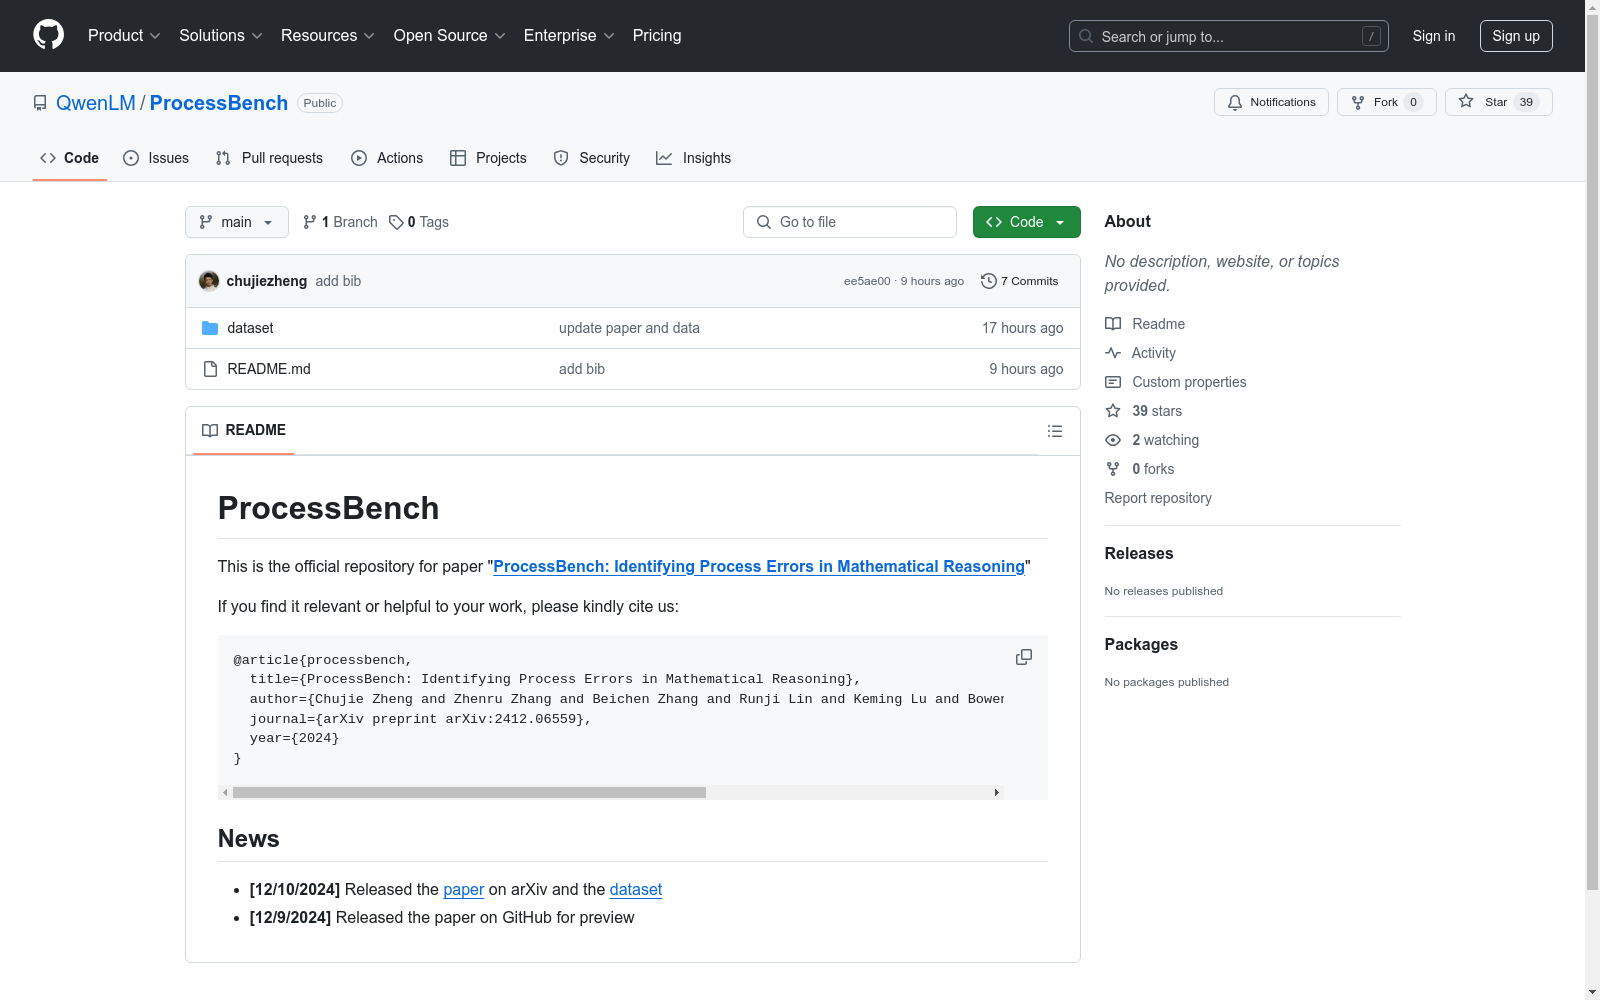
ProcessBench 是一个用于识别数学推理过程中错误的基准数据集。该数据集与论文 "ProcessBench: Identifying Process Errors in Mathematical Reasoning" 相关联。
数据集发布
- [12/10/2024] 数据集在 arXiv 上发布,并可在 dataset 目录中获取。
引用信息
如果该数据集对您的工作有帮助,请引用以下信息:
@article{processbench, title={ProcessBench: Identifying Process Errors in Mathematical Reasoning}, author={Chujie Zheng and Zhenru Zhang and Beichen Zhang and Runji Lin and Keming Lu and Bowen Yu and Dayiheng Liu and Jingren Zhou and Junyang Lin}, journal={arXiv preprint arXiv:2412.06559}, year={2024} }