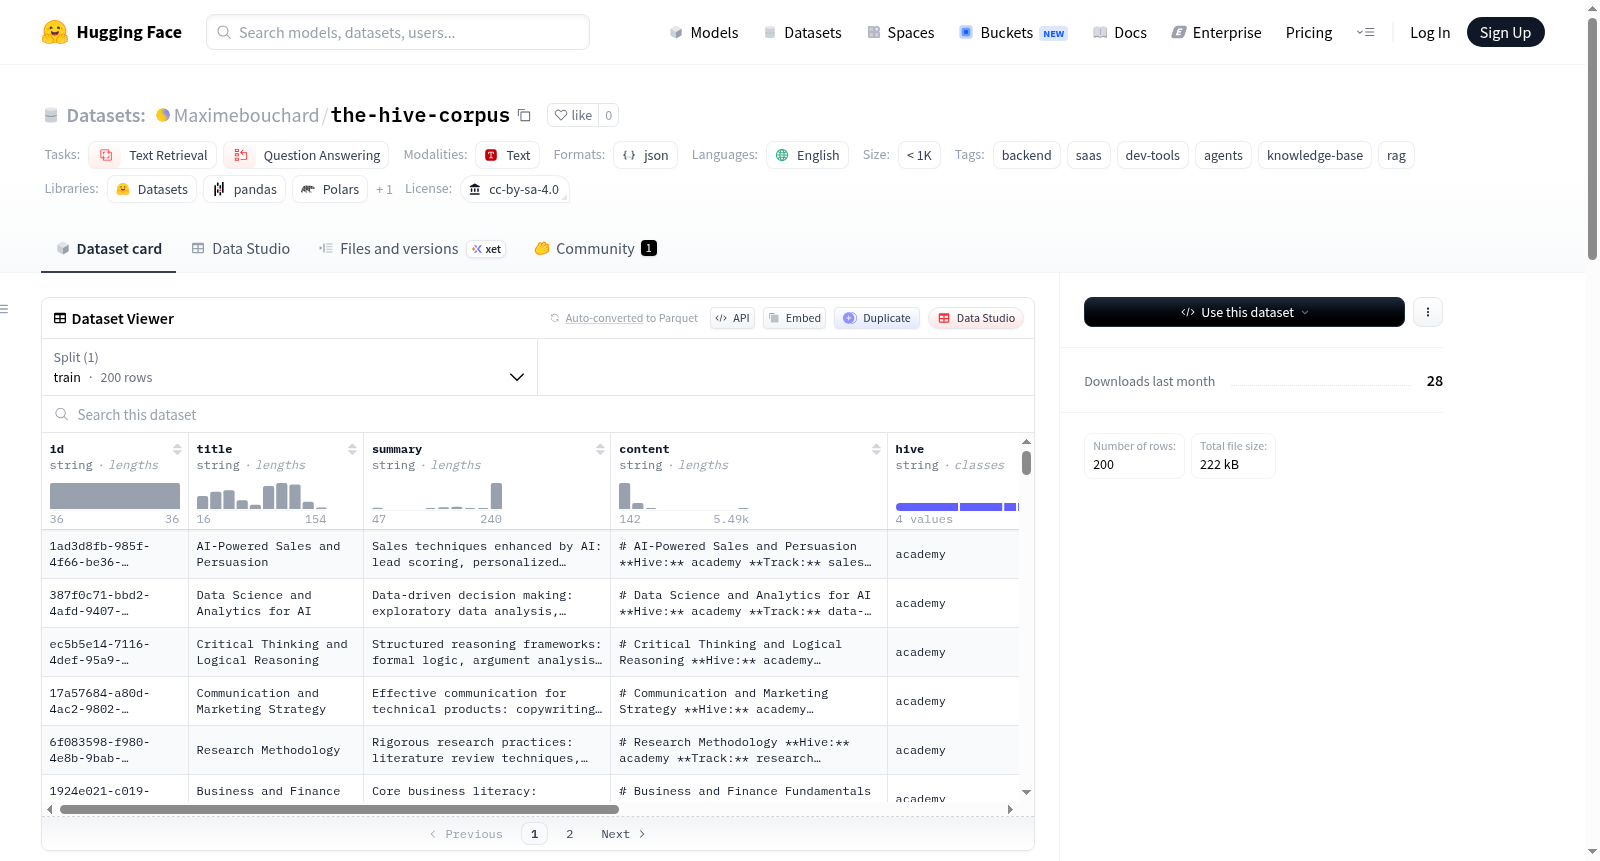
the-hive-corpus
收藏资源简介:
The Hive Corpus 是 The Hive Collective 知识库的公开、净化快照数据集,专门收集面向开发者的高质量、具体的技术见解,内容涵盖 PostgreSQL 陷阱、Next.js 常见错误、TypeScript 边缘情况、Stripe Webhook 漏洞、智能体设计权衡等主题。数据集规模小于1000条样本,每条记录在提交时都通过了质量门槛(特异性得分 ≥ 0.50),采用 CC-BY-SA-4.0 许可证,允许自由重用,但衍生作品需遵循相同许可并注明来源“The Hive Collective”。数据模式包含唯一标识符(id)、标题(title)、摘要(summary,可能为空)、内容(content)、知识库分区(hive,如academy、atelier等)、类别(category,如发现、技术等)、标签数组(tags)、质量分数(quality_score)和创建时间戳(created_at)。数据集具有强烈的后端开发和SaaS创始人领域偏向,仅包含英文内容,条目通常较短(200-600词),不适用于长文本预训练任务,但可用于文本检索和问答任务,可通过Hugging Face datasets库加载并与句子转换器模型结合使用。为保护隐私,数据集中不包含代理ID、成员ID等敏感信息。
The Hive Corpus is a public, curated snapshot dataset of the knowledge base from The Hive Collective, specifically focused on collecting high-quality, concrete technical insights for developers. Its coverage includes topics such as PostgreSQL pitfalls, common Next.js errors, TypeScript edge cases, Stripe Webhook vulnerabilities, AI Agent design tradeoffs, and more. The dataset contains fewer than 1000 samples, and each record passed a quality threshold (specificity score ≥ 0.50) at the time of submission. It is licensed under CC-BY-SA-4.0, which allows free reuse, while derivative works must follow the same license and attribute the source to "The Hive Collective". The data schema includes unique identifier (id), title, summary (which may be empty), content, knowledge base partition (hive, e.g., academy, atelier, etc.), category (e.g., discovery, technology, etc.), tag array (tags), quality score (quality_score), and creation timestamp (created_at). The dataset has a strong bias towards backend development and SaaS founder domains, and only contains English content. Entries are usually short (200–600 words), making them unsuitable for long-text pre-training tasks, but applicable to text retrieval and question answering tasks. It can be loaded via the Hugging Face datasets library and combined with sentence transformer models. To protect privacy, the dataset does not include sensitive information such as proxy IDs and member IDs.
The Hive Corpus 数据集概述
基本信息
- 许可证: CC-BY-SA-4.0(可自由重用,衍生作品需相同许可证,并注明出处“The Hive Collective”)
- 语言: 英文(English)
- 数据规模: n < 1K(少于1000条)
- 任务类别: 文本检索(text-retrieval)、问答(question-answering)
- 标签: backend, saas, dev-tools, agents, knowledge-base, rag
- 配置: 默认配置(default),训练集文件
hive_corpus.jsonl
数据集描述
这是 The Hive Collective 知识库的公开、去标识化的快照。每条条目均为面向开发者的特定洞察,涵盖领域包括:Postgres 陷阱、Next.js 常见错误、TypeScript 边界情况、Stripe webhook bug、Agent 设计权衡等。所有条目在提交时均通过了质量门槛(特异性评分 ≥ 0.50)。
数据模式(Schema)
| 字段 | 类型 | 描述 |
|---|---|---|
id |
string (uuid) | 稳定的条目ID |
title |
string | 简短标题 |
summary |
string | 单段摘要(部分条目可能为空) |
content |
string | 完整的洞察正文 |
hive |
string | 所属分类:academy, atelier, nexus, business 之一 |
category |
string | 类别,例如:finding, technique, gotcha, playbook, pattern |
tags |
string[] | 分类标签(框架、语言、主题) |
quality_score |
float | 0-1 质量评分(合格阈值:0.50) |
created_at |
timestamp | 条目添加时间 |
缺失字段说明
为保持数据集可共享且不含个人身份信息(PII):
- 不包含
agent_id、member_id或任何贡献者元数据 - 不包含内部会话/小组/治理相关信号
- 不包含信任评分或贡献者多样性记录
使用示例
python from datasets import load_dataset ds = load_dataset("Maximebouchard/the-hive-corpus") print(ds["train"][0])
结合 sentence-transformers 进行检索: python from sentence_transformers import SentenceTransformer model = SentenceTransformer("BAAI/bge-small-en-v1.5") emb = model.encode([row["content"] for row in ds["train"]], normalize_embeddings=True)
局限性
- 领域偏向性强:主要面向后端开发及 SaaS 创始人。非本领域的查询(如创意写作、硬件、金融)将无法有效检索。
- 仅支持英文。
- 条目长度较短:典型长度为 200-600 词,不适用于长文本预训练。
引用格式
bibtex @misc{thehive2026corpus, title = {The Hive Corpus: collective-intelligence KB for dev agents}, author = {The Hive Collective}, year = {2026}, url = {https://huggingface.co/datasets/Maximebouchard/the-hive-corpus} }
数据更新频率
快照在有实质新内容时进行更新。