cogitoergosumma-corpus
收藏资源简介:
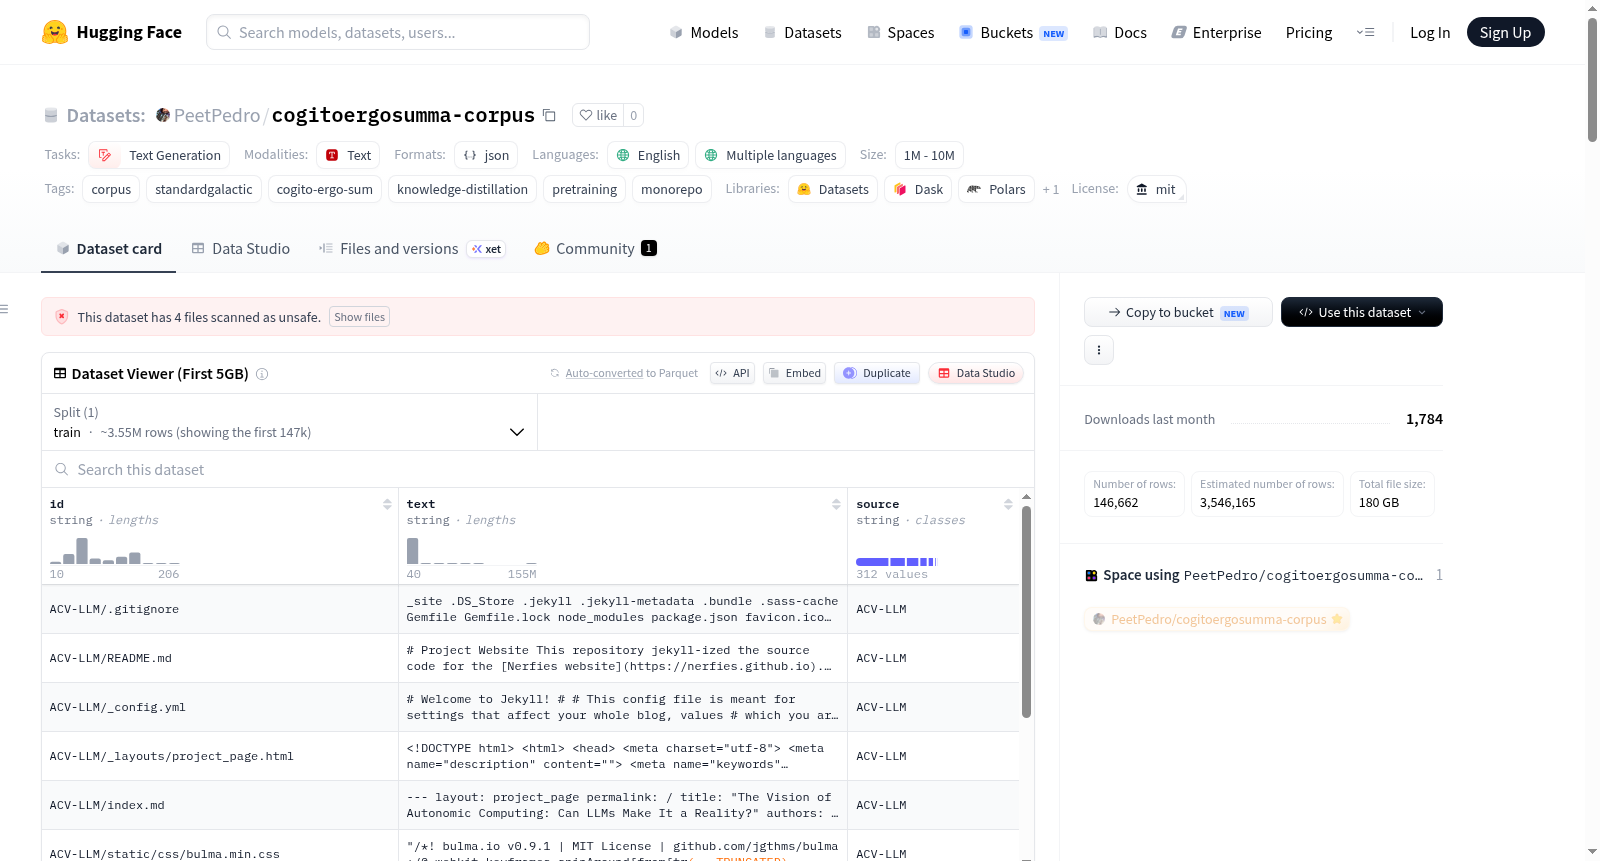
该数据集名为“Cogito Ergo Sum 全集合”(The Corpus of Cogito ergo SUMMA summarum),由用户 standardgalactic(Cogito Ergo Sum)的全部公开文本仓库汇集而成,是一个大型文本语料库。数据集包含 1,367 个仓库,约 78.3 GB 纯文本,以 JSONL 格式存储。每条记录由三个字段构成:id(仓库及文件路径)、text(文件完整内容)、source(来源仓库名称)。数据仅收录文本文件(如 Markdown、TeX、Python、JSON 等),排除了二进制文件、PDF、媒体文件、归档文件以及超过 300 MB 的大型 fork 仓库。构建过程中采用浅克隆、路径去重、可恢复构建策略。数据集可通过 Hugging Face Datasets 库直接加载,或通过 HF Bucket 流式访问,无需任何认证。其内容覆盖 quadrivium、library、alphabet、calculus、cosmology、language-evolution 等多个领域,旨在将分散在数千个仓库中的知识整合为一个可供搜索和学习的大型语料库,尤其适合用于文本生成、预训练、知识蒸馏等任务,或作为研究性学习资源。
This dataset is named The Corpus of Cogito ergo SUMMA summarum, compiled from all public text repositories of user standardgalactic (Cogito Ergo Sum), forming a large text corpus. It contains 1,367 repositories, approximately 78.3 GB of plain text, stored in JSONL format. Each record consists of three fields: id (repository and file path), text (full file content), and source (source repository name). The data only includes text files (such as Markdown, TeX, Python, JSON, etc.), excluding binary files, PDFs, media files, archive files, and large fork repositories exceeding 300 MB. The construction process uses shallow cloning, path deduplication, and resumable building strategies. The dataset can be directly loaded via the Hugging Face Datasets library or streamed through HF Bucket without authentication. Its content covers multiple domains such as quadrivium, library, alphabet, calculus, cosmology, and language-evolution, aiming to integrate knowledge scattered across thousands of repositories into a large-scale corpus for search and learning, particularly suitable for text generation, pre-training, knowledge distillation, and as a research and learning resource.
数据集概述:The Corpus of Cogito Ergo Sum Summarum
数据集简介
该数据集汇集了 Standard Galactic 用户所有公开的文本型代码仓库内容,包含 1,367 个仓库、约 78.3 GB 的文本数据,并持续增长中。数据集将分散在数万个未索引仓库中的知识整合为统一语料库。
数据规模
- 仓库数量:1,367 个
- 数据大小:约 78.3 GB 纯文本
- 构建状态:持续进行中,小型分叉仓库的尾部数据正在不断纳入
数据格式
数据集采用 JSONL 格式,每个文件对应一个源仓库(data/<repo>.jsonl),每条记录包含三个字段:
id:格式为<repo>/<path>,标识文件来源text:文件完整文本内容source:来源仓库名称
支持的文件类型:md、txt、tex、org、rst、srt、vtt、tsv、json、py、sh、c、cpp、rs、go、java、js、ts、html、yaml、toml、csv
排除内容:二进制文件、PDF、mhtml、媒体文件、压缩包,以及超过 300 MB 的大型分叉仓库(如 chromium、Linux 内核、游戏引擎等重复代码库)。
数据来源
主要来源仓库包括:quadrivium、library、research-projects、alphabet、calculus、abraxas、antivenom、spherepop、memnet、cosmology、language-evolution、cliodynamics、physiome、bootcamp、cognition-research、bash-lab、kitbash、cosmic-cults、guardrails、llvm-archive、art_of_tts、neovim、phabricator 等,覆盖认知科学、语言演化、宇宙学、计算、编程等多个领域。
访问方式
- Hugging Face 数据集:可通过
load_dataset("PeetPedro/cogitoergosumma-corpus", data_files="data/*.jsonl", split="train")加载 - HF Bucket 完整存档:可通过
hf://buckets/PeetPedro/cogitoergosumma-corpus/data/流式访问或同步下载
许可证
采用 MIT 许可证,但数据内容遵循各源仓库自身的许可证条款。
构建方法
- 使用浅克隆(
--depth 1)获取仓库 - 按路径去重
- 支持断点续传构建
- 数据经过清理,排除二进制内容