nlg-abstractive_summarization
收藏资源简介:
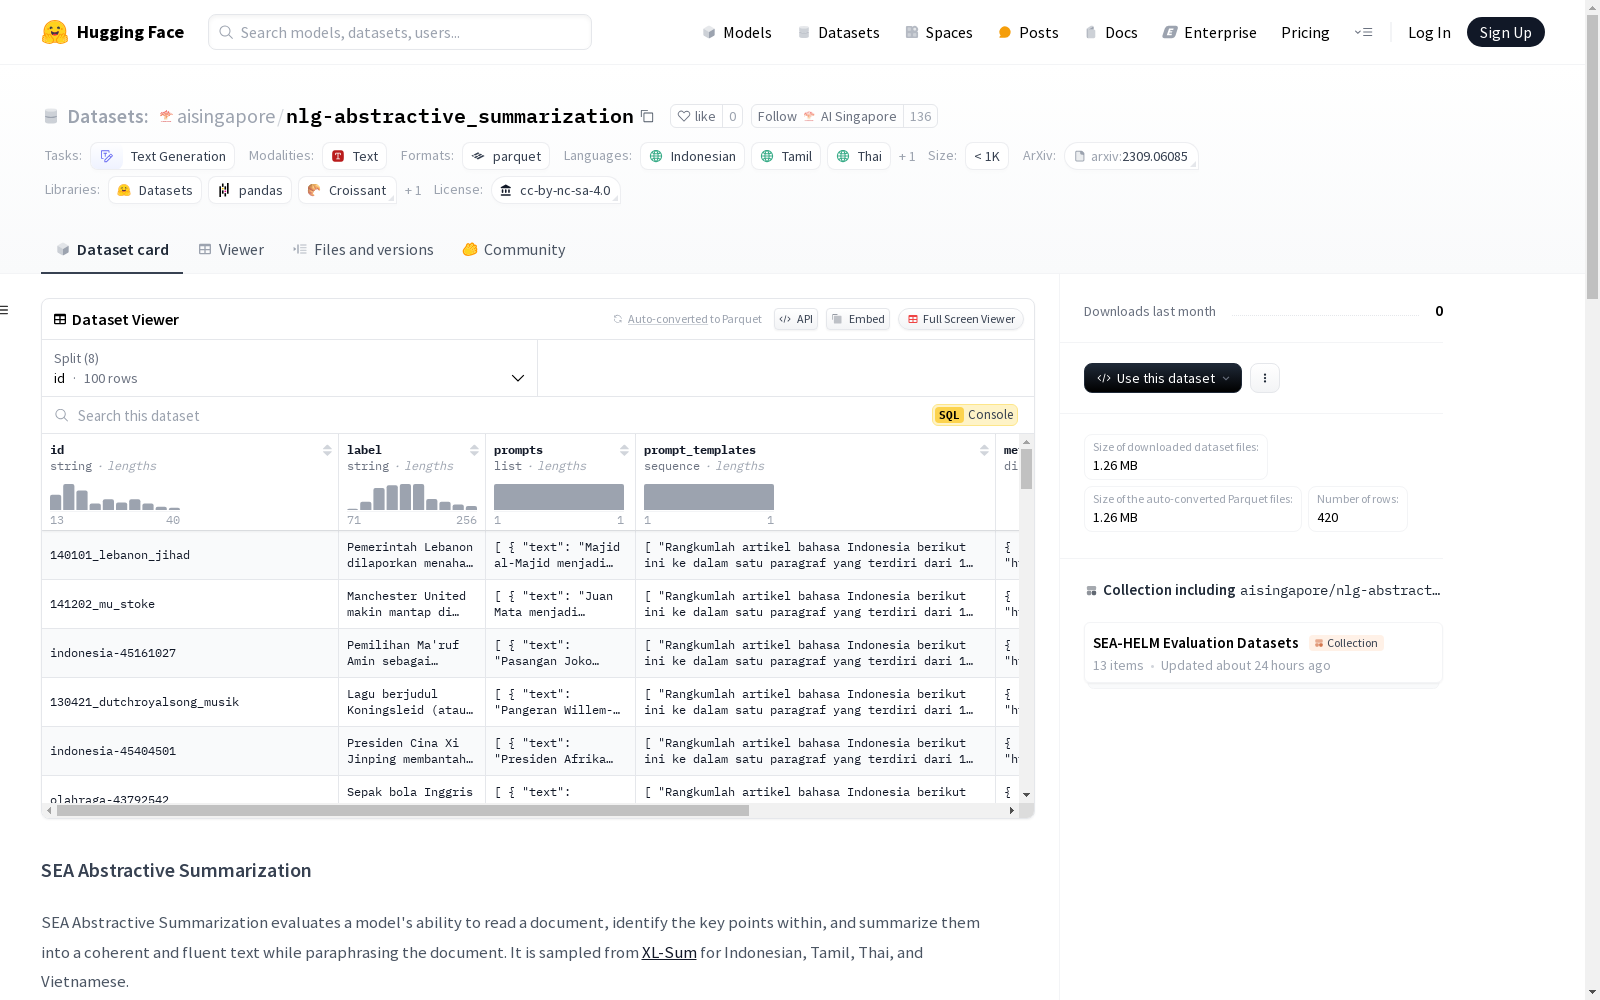
SEA Abstractive Summarization数据集用于评估模型阅读文档、识别关键点并将其总结为连贯流畅文本的能力,同时对文档进行释义。该数据集从XL-Sum中采样,涵盖印度尼西亚语、泰米尔语、泰语和越南语。数据集按语言划分,并包含少量示例的额外划分。每个划分包含不同数量的示例和不同模型的标记数。数据集用于评估聊天或指令调优的大型语言模型(LLMs),并作为AI Singapore的SEA-HELM排行榜的一部分。
SEA Abstractive Summarization Dataset is designed to evaluate a model's ability to read documents, identify key points, and summarize them into coherent, fluent texts while paraphrasing the original content. This dataset is sampled from XL-Sum, covering four languages: Indonesian, Tamil, Thai, and Vietnamese. It is partitioned by language, with an additional partition containing a small number of examples. Each partition includes a varying number of examples and a corresponding count of tokens from different models. This dataset is used to evaluate chat- and instruction-tuned large language models (LLMs), and serves as part of the SEA-HELM leaderboard developed by AI Singapore.