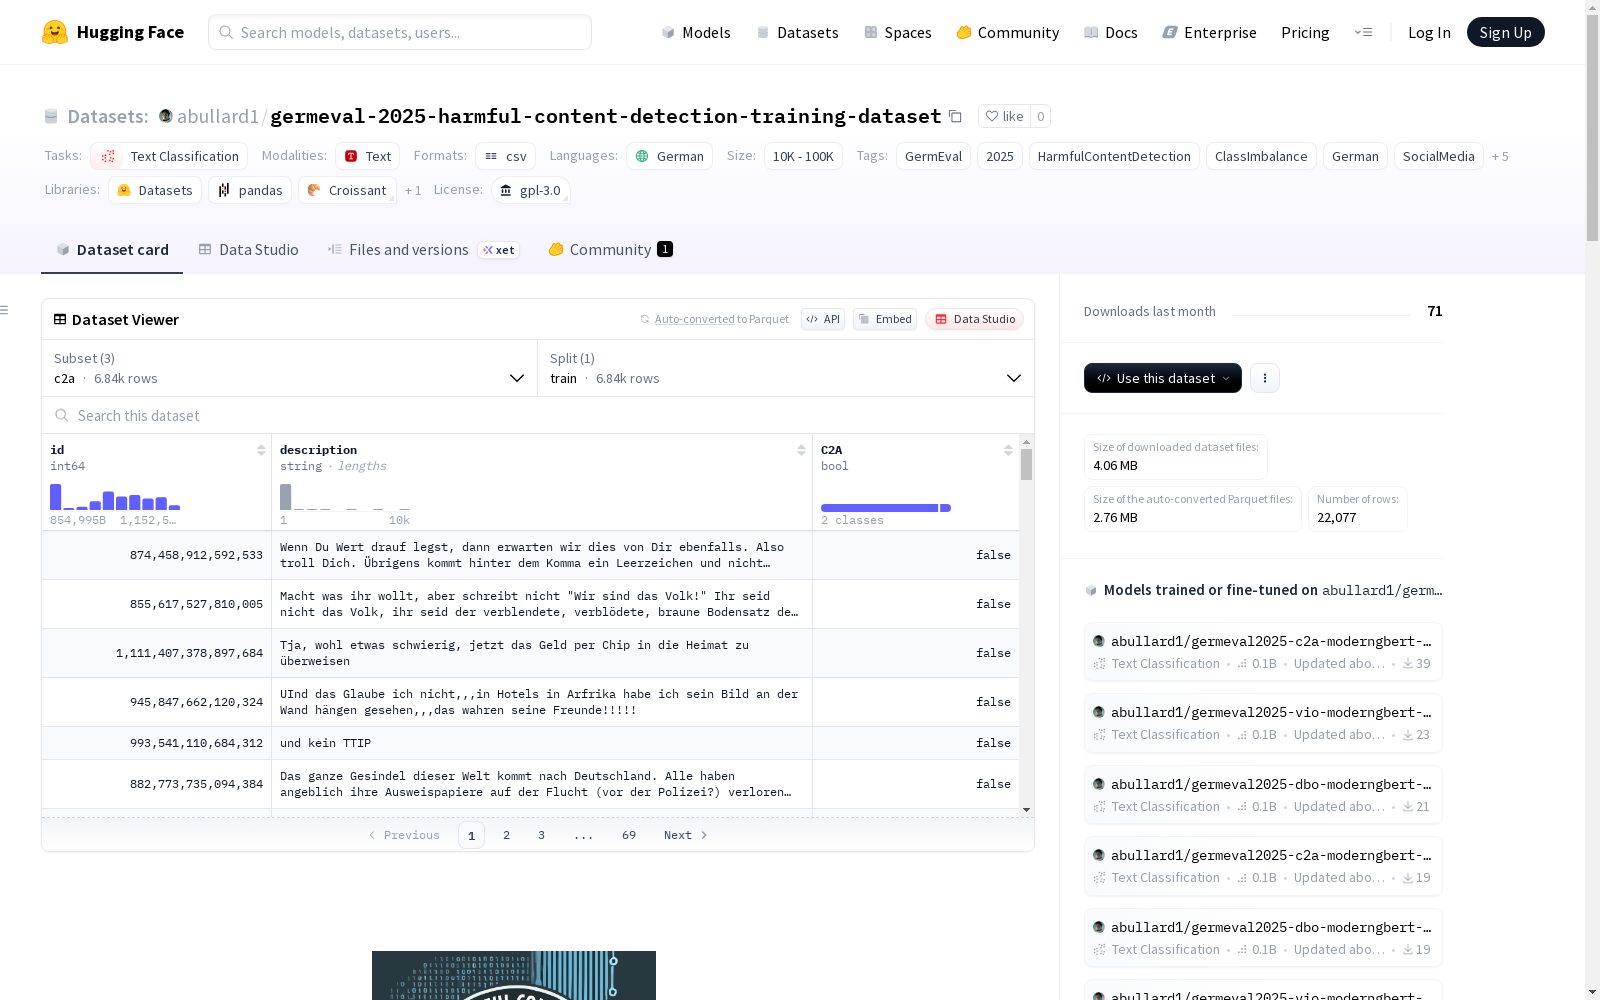
germeval-2025-harmful-content-detection-training-dataset
收藏资源简介:
GermEval 2025有害内容检测数据集(训练集)是针对德语社交媒体(Twitter)的,包含三个子任务:呼吁行动检测、对民主基本秩序的攻击分类、暴力内容检测。数据集由2014-2016年期间右翼极端主义网络中的德语推文组成,并由领域专家进行注释。数据集旨在研究有害内容检测,特别强调处理类别不平衡和短小、嘈杂的推文。
The GermEval 2025 Harmful Content Detection Dataset (Training Set) is targeted at German social media (Twitter) and covers three subtasks: call-to-action detection, classification of attacks on fundamental democratic order, and violent content detection. The dataset consists of German tweets from right-wing extremist networks between 2014 and 2016, and was annotated by domain experts. It is designed for research on harmful content detection, with a particular emphasis on addressing class imbalance and the challenges posed by short, noisy tweets.
GermEval 2025有害内容检测训练数据集概述
数据集基本信息
- 数据集名称:GermEval 2025 Harmful Content Detection (Training Splits)
- 许可证:GPL-3.0
- 创建者:Samuel Ruairí Bullard - University of Regensburg
- 语言:德语
- 语言多样性:单语
- 标注创建方式:专家生成
- 来源:原始数据集
- 模态:文本
- 数据规模:10K-100K样本
任务与类别
- 任务类别:文本分类
- 子任务配置:
- Call to Action (C2A):二元分类(TRUE/FALSE)
- Attacks on Democratic Basic Order (DBO):四分类(nothing/criticism/agitation/subversive)
- Violence (VIO):二元分类(TRUE/FALSE)
数据内容
- 数据来源:德国右翼极端主义网络的推特数据(2014-2016年)
- 数据特征:主要包含简短、嘈杂的推文
- 数据特点:存在严重的类别不平衡问题
文件结构
- c2a_train.csv:约9,084行
- dbo_train.csv:约9,617行
- vio_train.csv:约10,230行
数据格式
所有CSV文件均为逗号分隔,包含以下字段:
id:推文标识符(字符串)description:推文文本(字符串)- 任务特定标签字段(C2A/DBO/VIO)
使用说明
警告:该数据集包含有害、极端主义、暴力和攻击性语言,仅用于有害内容检测研究,在用户界面中显示示例时需谨慎
许可与引用要求
使用时需同时注明GermEval 2025组织者(斯图加特大学、曼海姆大学)和数据收集者(米特韦达应用科学大学)的贡献
相关资源
- 竞赛页面:https://www.codabench.org/competitions/4963/
- 模型库:https://huggingface.co/spaces/abullard1/abullardUR_GermEval2025_Submission_ModelZoo
- 基础模型:https://huggingface.co/LSX-UniWue/ModernGBERT_134M
- GitHub仓库:https://github.com/abullard1/abullardUR-GermEval-Shared-Task-2025