swegym_qwen80b_1500i
收藏资源简介:
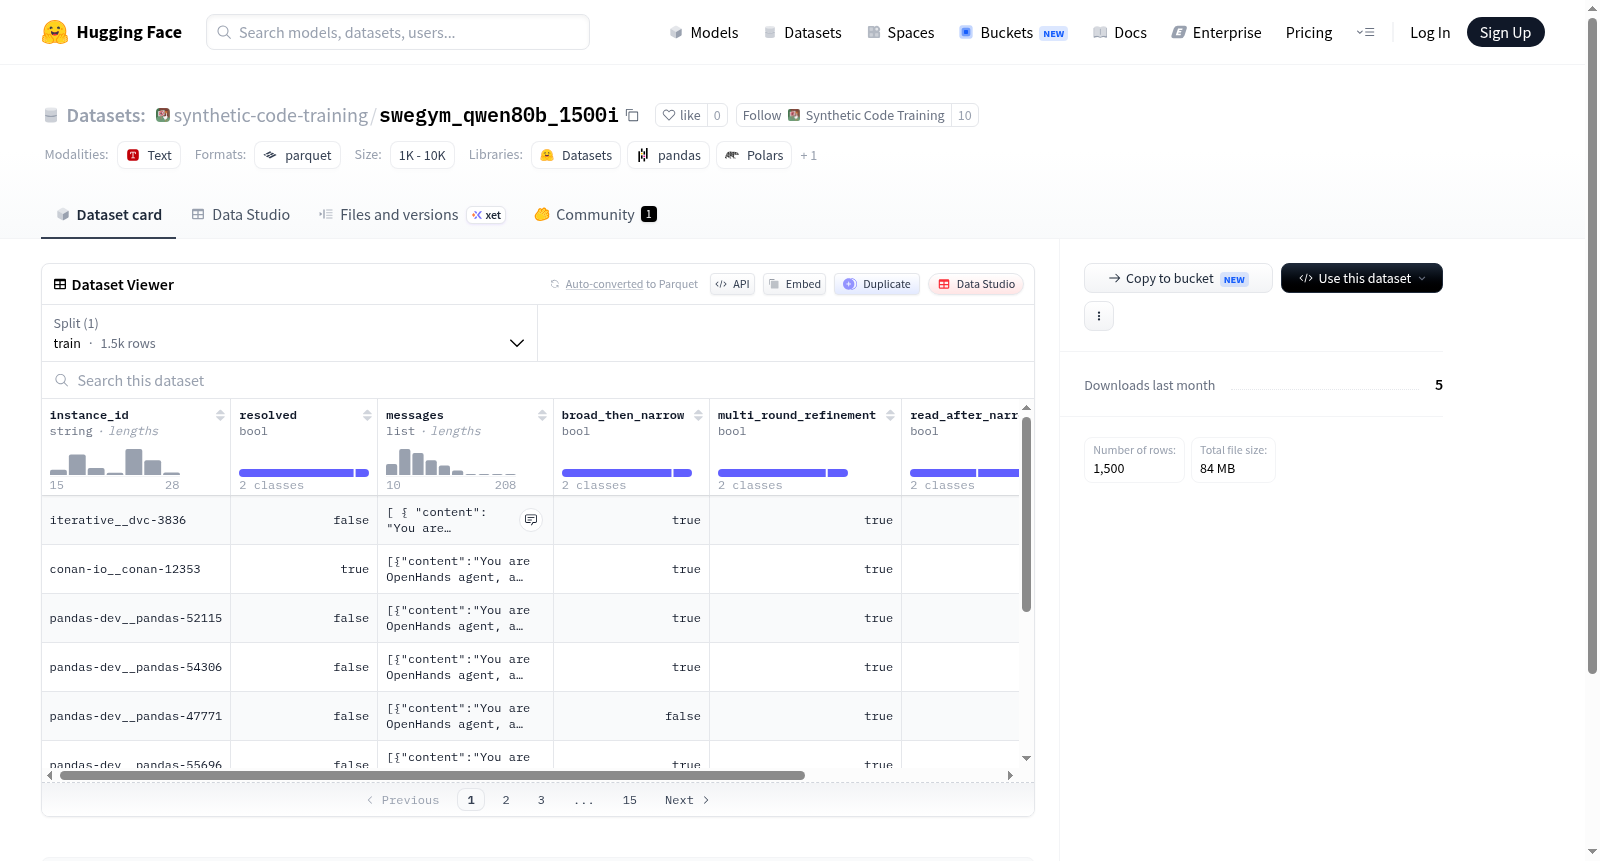
该数据集包含1500个训练样本,每个样本由以下字段组成:instance_id(字符串,实例唯一标识)、resolved(布尔值,表示是否已解决)、messages(列表,包含对话消息,每个消息有content(字符串,内容)和role(字符串,角色,如用户或助手))、broad_then_narrow(布尔值,表示是否先宽泛后精确)、multi_round_refinement(布尔值,表示是否进行多轮细化)、read_after_narrowing(布尔值,表示是否在细化后阅读)、judge_notes(字符串,法官备注)。数据集大小约为231MB,仅提供训练集。字段命名暗示该数据集可能用于多轮对话、信息检索或逐步精化任务,但具体用途需参考原始任务说明。
The dataset contains 1500 training samples, each consisting of the following fields: instance_id (string, unique instance identifier), resolved (boolean, indicating whether resolved), messages (list, containing dialogue messages, each message has content (string) and role (string, e.g., user or assistant)), broad_then_narrow (boolean, indicating whether broad then narrow), multi_round_refinement (boolean, indicating whether multi-round refinement), read_after_narrowing (boolean, indicating whether read after narrowing), judge_notes (string, judge notes). The dataset size is about 231MB, with only the training set provided. The field names suggest the dataset may be used for multi-turn dialogue, information retrieval, or stepwise refinement tasks, but the specific use case needs to refer to the original task description.
数据集概述
该数据集名为 synthetic-code-training/swegym_qwen80b_1500i,托管于 Hugging Face 平台。它是一个用于代码合成训练的数据集,包含 1500 个训练样本,总大小约为 232 MB(下载大小约为 84 MB)。
数据特征
数据集中每个样本包含以下字段:
- instance_id(字符串):实例的唯一标识符。
- resolved(布尔值):指示该实例是否已解决。
- messages(列表):由多个消息组成,每个消息包含:
- content(字符串):消息内容。
- role(字符串):消息角色(如 system、user、assistant)。
- broad_then_narrow(布尔值):是否采用“先宽后窄”的策略。
- multi_round_refinement(布尔值):是否进行了多轮细化。
- read_after_narrowing(布尔值):是否在细化后进行了阅读。
- judge_notes(字符串):评估者的备注或说明。
数据划分
- train 分割:包含全部 1500 个样本,字节数为 231,869,924。
数据文件
- 默认配置
default下的训练数据文件位于data/train-*,即数据以多个分片文件形式存储。
用途
该数据集主要用于代码合成模型的训练,可能涉及代码生成、问题解决等任务,并强调多轮迭代和策略性细化过程。特征中的布尔字段和评估备注为训练过程提供了额外的监督信号。