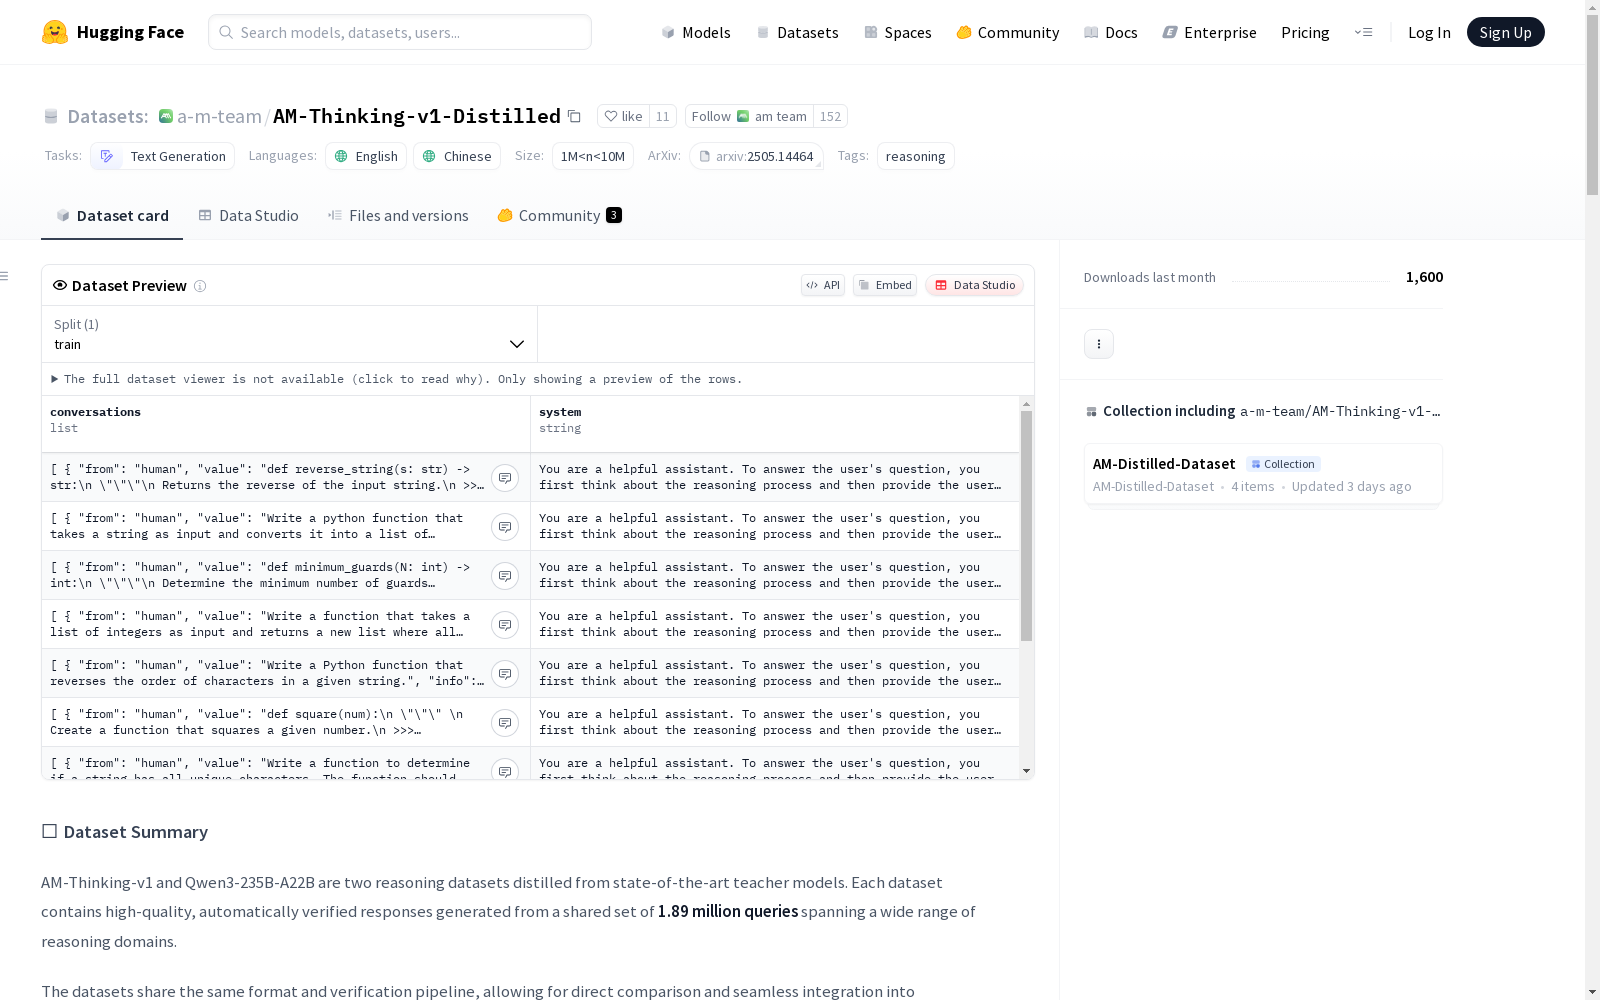
AM-Thinking-v1-Distilled, AM-Qwen3-Distilled
收藏资源简介:
该数据集由贝壳(Ke.com)的a-m-team团队创建,旨在通过蒸馏数据来提升开源语言模型的推理能力。数据集由三个最先进的教师模型(AM-Thinking-v1、Qwen3-235B-A22B和DeepSeek-R1)在189万个共享查询上收集的验证输出构建而成。经过严格的数据清洗和过滤,该数据集提供了高质、经过验证的推理数据,可用于训练在数学、编码和科学推理等任务上表现出色的模型。数据集已在Hugging Face上公开发布,支持未来对开源和高性能推理导向语言模型的研究。
This dataset was created by the a-m-team from Ke.com, with the aim of enhancing the reasoning capabilities of open-source language models via distilled data. It is constructed from verified outputs collected by three state-of-the-art teacher models, namely AM-Thinking-v1, Qwen3-235B-A22B, and DeepSeek-R1, across 1.89 million shared queries. Through rigorous data cleaning and filtering, this dataset provides high-quality, verified reasoning data that can be used to train models that excel at tasks such as mathematics, coding, and scientific reasoning. The dataset has been publicly released on Hugging Face to support future research on open-source, high-performance reasoning-oriented language models.
数据集概述:AM-Thinking-v1-Distilled
📘 数据集摘要
- 来源:从先进教师模型蒸馏得到的推理数据集
- 查询量:共享189万条独特提示
- 语言:英文(en)、中文(zh)
- 任务类型:文本生成(text-generation)
- 标签:推理(reasoning)
- 规模:1M<n<10M
- 关联数据集:AM-Qwen3-Distilled
📊 基准性能
| 基准测试 | AM-Thinking-v1 Distilled | Qwen3-235B-A22B Distilled | DeepSeek-R1 Distilled | Qwen3-32B | AM-Thinking-v1 | Qwen3-235B-A22B | DeepSeek-R1 |
|---|---|---|---|---|---|---|---|
| AIME2024 | 84.3 | 79.4 | 70.9 | 81.4 | 85.3 | 85.7 | 79.8 |
| AIME2025 | 72.2 | 62.2 | 52.8 | 72.9 | 74.4 | 81.5 | 70.0 |
| MATH500 | 98.4 | 93.9 | 95.8 | - | - | - | - |
| LiveCodeBench | 65.9 | 59.6 | 57.0 | 65.7 | 70.3 | 70.7 | 64.3 |
📂 数据结构
数据字段
system:蒸馏过程中使用的系统提示conversations:对话轮次列表,包含:from:human或assistantvalue:完整消息内容info:元数据字典,包含:source:数据集来源category:任务领域ground_truth:真实参考test_case:关联测试用例IDinstruction_constrain:指令约束元数据think_content:助理解释轨迹answer_content:最终答案段verify_score:验证置信度分数model_name:教师模型名称ppl:输出的困惑度
📈 数据集统计
- 任务类别分布:
- 通用聊天:41.8%
- 数学推理:29.5%
- 代码生成:17.1%
- 其他:11.6%
✅ 验证与质量控制
- 验证方法:
- 数学:Math-Verify
- 代码:沙盒环境测试用例验证
- 科学:LLM评分答案相似性
- 指令遵循:IFEval验证器
- 通用聊天:奖励模型评估
- 过滤措施:
- 困惑度过滤
- N-gram重复过滤
- 结构格式检查
⚠️ 限制
- 用途限制:仅限研究目的
- 免责声明:内容不代表任何个人或机构的观点
📜 引用
bibtex @misc{tian2025correctanswersequaldistillation, title={Not All Correct Answers Are Equal: Why Your Distillation Source Matters}, author={Xiaoyu Tian and Yunjie Ji and Haotian Wang and Shuaiting Chen and Sitong Zhao and Yiping Peng and Han Zhao and Xiangang Li}, year={2025}, eprint={2505.14464}, archivePrefix={arXiv}, primaryClass={cs.CL}, url={https://arxiv.org/abs/2505.14464}, }