source-based-instructions
收藏资源简介:
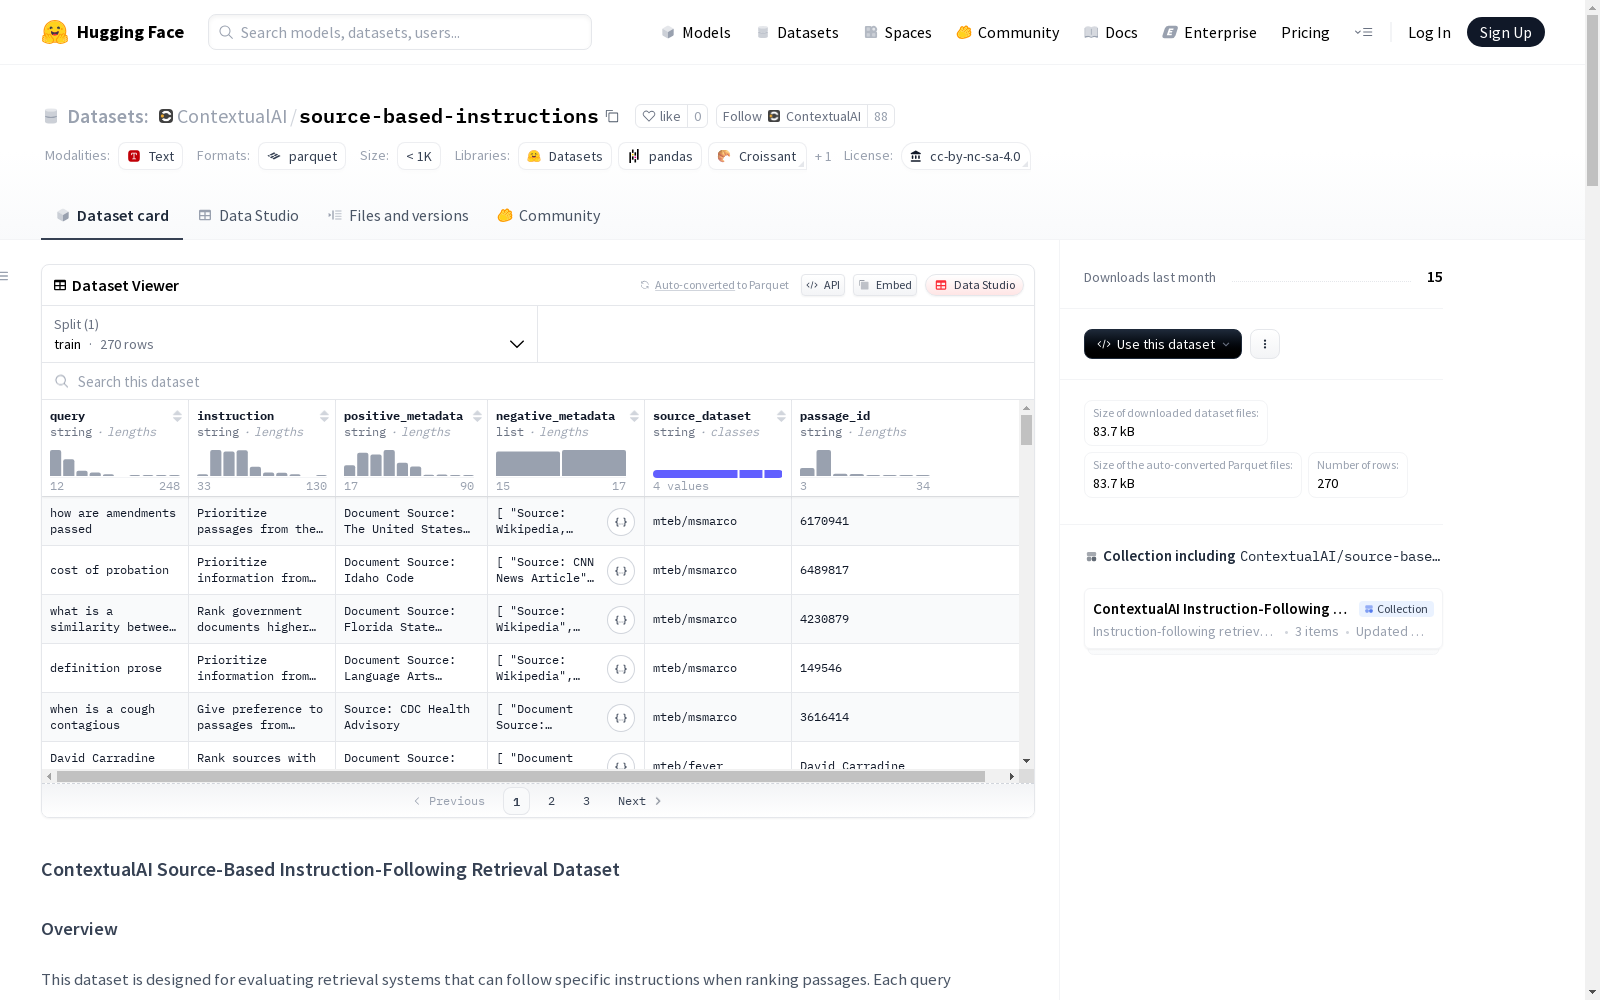
这是一个用于评估检索系统能否在排名段落时遵循特定指令的数据集。每个查询都附带一个指令,指定在检索过程中应优先考虑的信息方面或类型。数据集包含查询、指令、正样本元数据、负样本元数据、源数据集名称和段落ID等特征。由于法律原因,原始段落无法重新托管,因此提供了一个数据处理脚本来下载和合并这些段落。
This is a dataset designed to evaluate whether retrieval systems can follow specific instructions when ranking paragraphs. Each query is accompanied by an instruction that specifies the information aspects or types that should be prioritized during the retrieval process. The dataset includes features such as queries, instructions, positive sample metadata, negative sample metadata, source dataset names, and passage IDs. Due to legal restrictions, the original paragraphs cannot be reposted, so a data processing script is provided to download and merge these paragraphs.
ContextualAI Source-Based Instruction-Following Retrieval Dataset 概述
数据集基本信息
- 许可证: Creative Commons Attribution Non Commercial Share Alike 4.0
- 下载大小: 83,709 字节
- 数据集大小: 204,398 字节
- 训练集样本数: 270 个
数据集结构
特征
query: 搜索查询instruction: 检索时应优先考虑的信息方面的具体指令positive_metadata: 相关段落的元数据/上下文negative_metadata: 非相关段落的元数据/上下文列表source_dataset: 包含完整段落的源数据集名称passage_id: 从源数据集中检索完整段落的唯一标识符
数据处理
- 注意事项: 由于法律原因,无法重新托管原始段落,需通过提供的脚本下载并合并。
- 处理脚本: 使用Python脚本从源数据集下载原始段落并与元数据合并。
评估
- 评估指标: 平均倒数排名 (MRR)
- 评估过程:
- 对每个查询-指令对,检索/排名所有段落(1个正面 + N个负面)
- 找到正面段落的排名
- 计算倒数排名 (1/rank)
- 对所有查询取平均值
引用
bibtex @dataset{ContextualAI-source-based-instructions, title={Contextual Source-Based Instruction-Following Retrieval Dataset}, author={George Halal, Sheshansh Agrawal}, year={2025}, publisher={HuggingFace} }
联系方式
- 如有问题或疑问,请在数据集存储库中提交问题或联系 george@contextual.ai。