sectorial-llm-collection
收藏资源简介:
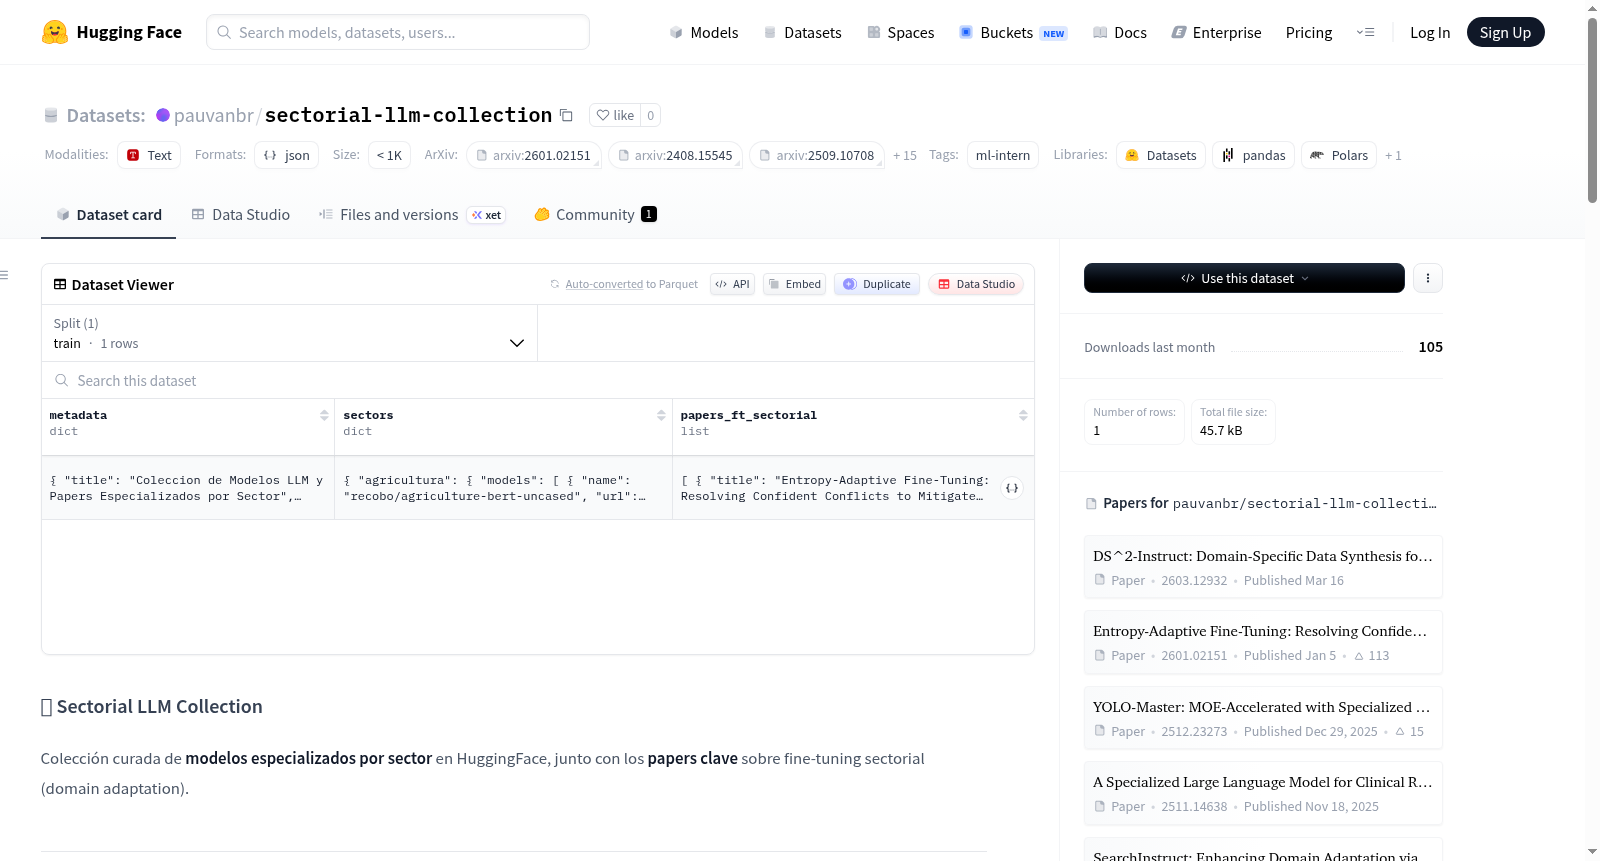
Sectorial LLM Collection 是一个在 HuggingFace Hub 上整理的、专注于领域特定大语言模型(LLM)和计算机视觉模型的元数据集合。该数据集旨在为研究人员和开发者提供一个按行业领域划分的专门化模型及关键技术论文的索引目录。数据集核心内容覆盖了农业、法律、旅游、医疗生物、可再生能源、气候、气象、实时计算机视觉、金融、网络安全、地质等 10 个关键领域,总计收录了约 120 个经过领域适应(Domain Adaptation)或微调(Fine-Tuning)的模型,例如 Legal-BERT、ClinicalBERT、FinGPT 家族、ClimateBERT 家族以及各种 YOLO、RT-DETR 等实时视觉模型。此外,数据集还配套收集了 18 篇关于领域适应方法的关键学术论文,并提炼了如持续预训练+SFT、两阶段PEFT/LoRA、合成数据生成、模型融合等 7 条核心技术方案。数据以结构化的 JSON 格式提供,便于用户按领域查询和获取相关模型及论文信息,适用于领域自然语言处理、计算机视觉、模型微调策略研究以及构建行业特定AI应用等场景。
Sectorial LLM Collection is a curated metadata collection hosted on the Hugging Face Hub, focusing on domain-specific large language models (LLMs) and computer vision models. This dataset aims to provide researchers and developers with an indexed catalog of specialized models and key technical papers categorized by industrial sectors. The core content covers 10 key sectors including agriculture, law, tourism, medical biology, renewable energy, climate, meteorology, real-time computer vision, finance, cybersecurity, and geology. In total, it includes approximately 120 models that have undergone domain adaptation or fine-tuning, such as Legal-BERT, ClinicalBERT, the FinGPT family, the ClimateBERT family, and various real-time vision models including YOLO and RT-DETR. Additionally, the dataset collects 18 key academic papers on domain adaptation methods, and summarizes 7 core technical solutions such as continuous pre-training + SFT, two-stage PEFT/LoRA, synthetic data generation, and model fusion. The dataset is provided in structured JSON format, enabling users to query and retrieve relevant model and paper information by sector, and is applicable to scenarios including domain natural language processing, computer vision, research on model fine-tuning strategies, and the development of industry-specific AI applications.