cibelex-qa-rag-evals
收藏资源简介:
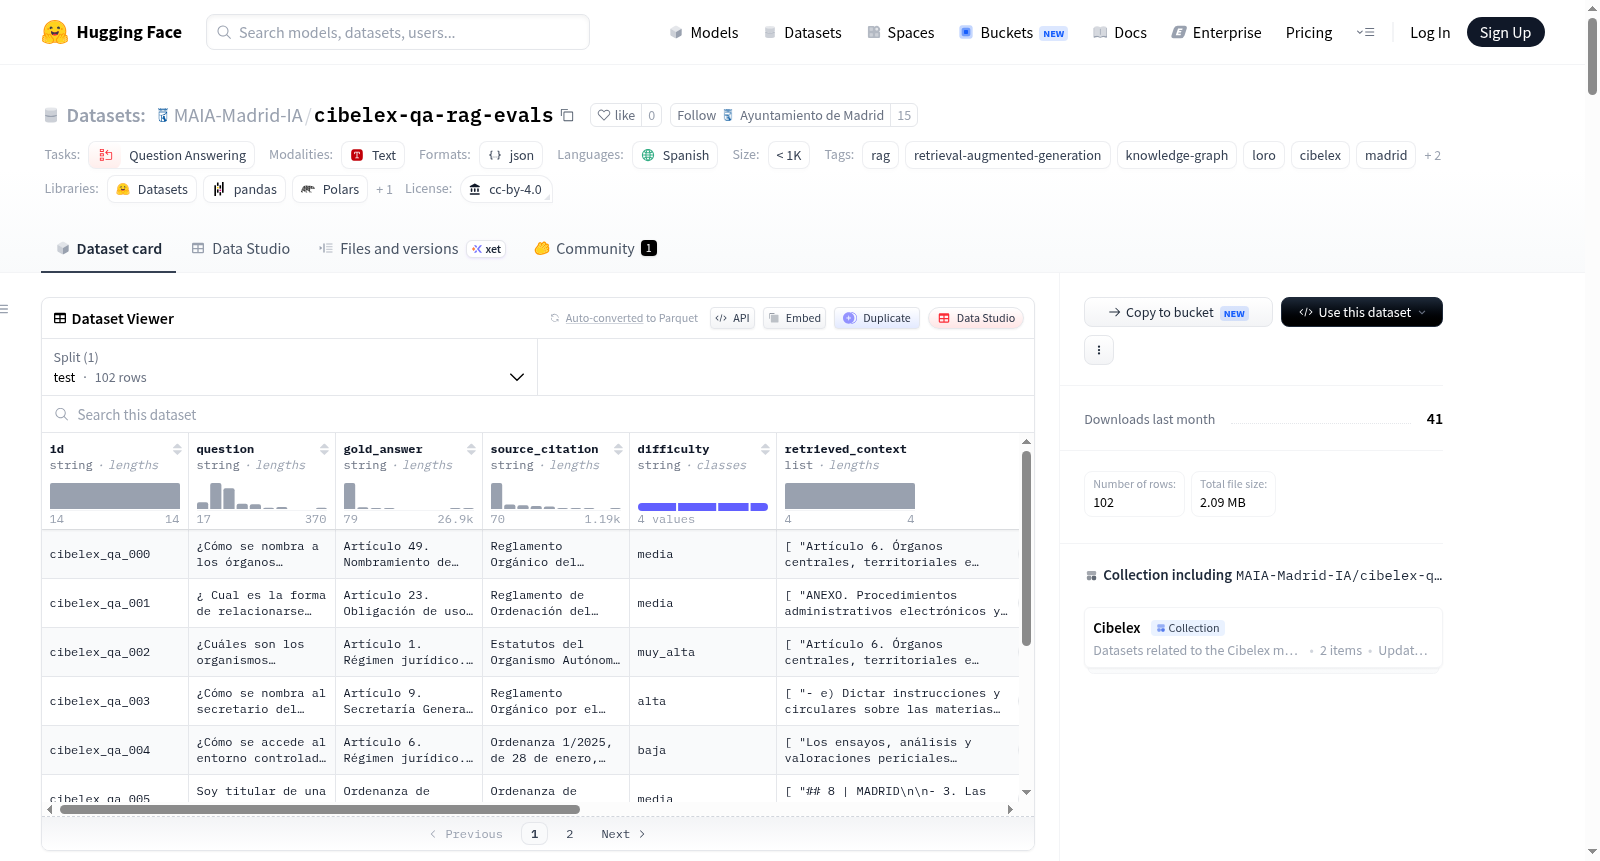
Cibelex QA RAG Evals是一个专门用于问答评估的数据集,其内容基于西班牙马德里市政府的法规语料库(LoRO本体/Cibelex知识图谱)。该数据集旨在为检索增强生成(RAG)、知识图谱感知检索以及西班牙行政法领域的特定问答任务提供基准评估。数据集包含约102个样本,每个样本均包含一个关于马德里市法规的西班牙语自然语言问题、从相关法规条款中直接引用的标准答案、由基线检索器返回的前4个相关文本段落,以及基线大语言模型基于这些段落生成的预测答案。此外,每个样本还标注了问题难度、所需的知识图谱检索策略(如实体搜索、跨图连接、图谱遍历、完整上下文)以及预期的具体知识图谱工具。数据由法律专家创建和标注,确保了领域专业性。数据集的构建过程可复现,并记录了后处理修正步骤。该数据集适用于评估和比较新的检索器、答案生成模型在法规问答任务上的性能,特别是研究知识图谱如何增强RAG系统在复杂法律文本中的表现。
Cibelex QA RAG Evals is a dataset specifically designed for question answering (QA) evaluation. Its content is based on the regulatory corpus of the Madrid City Government (LoRO ontology/Cibelex knowledge graph). This dataset serves as a benchmark for retrieval-augmented generation (RAG), knowledge-graph-aware retrieval, and targeted QA tasks in the field of Spanish administrative law. It contains approximately 102 samples, each including a Spanish natural language question about Madrid’s municipal regulations, a standard answer directly quoted from relevant regulatory clauses, the top 4 relevant text passages returned by a baseline retriever, and a predicted answer generated by a baseline large language model (LLM) based on these passages. Additionally, each sample is annotated with question difficulty, required knowledge-graph retrieval strategies (such as entity search, cross-graph connection, graph traversal, and full context), and the expected specific knowledge-graph tools. The dataset was created and annotated by legal experts, ensuring domain professionalism. The construction process of the dataset is reproducible, with post-processing correction steps documented. This dataset is suitable for evaluating and comparing the performance of new retrievers and answer generation models on regulatory QA tasks, especially for researching how knowledge graphs enhance RAG systems in complex legal text scenarios.