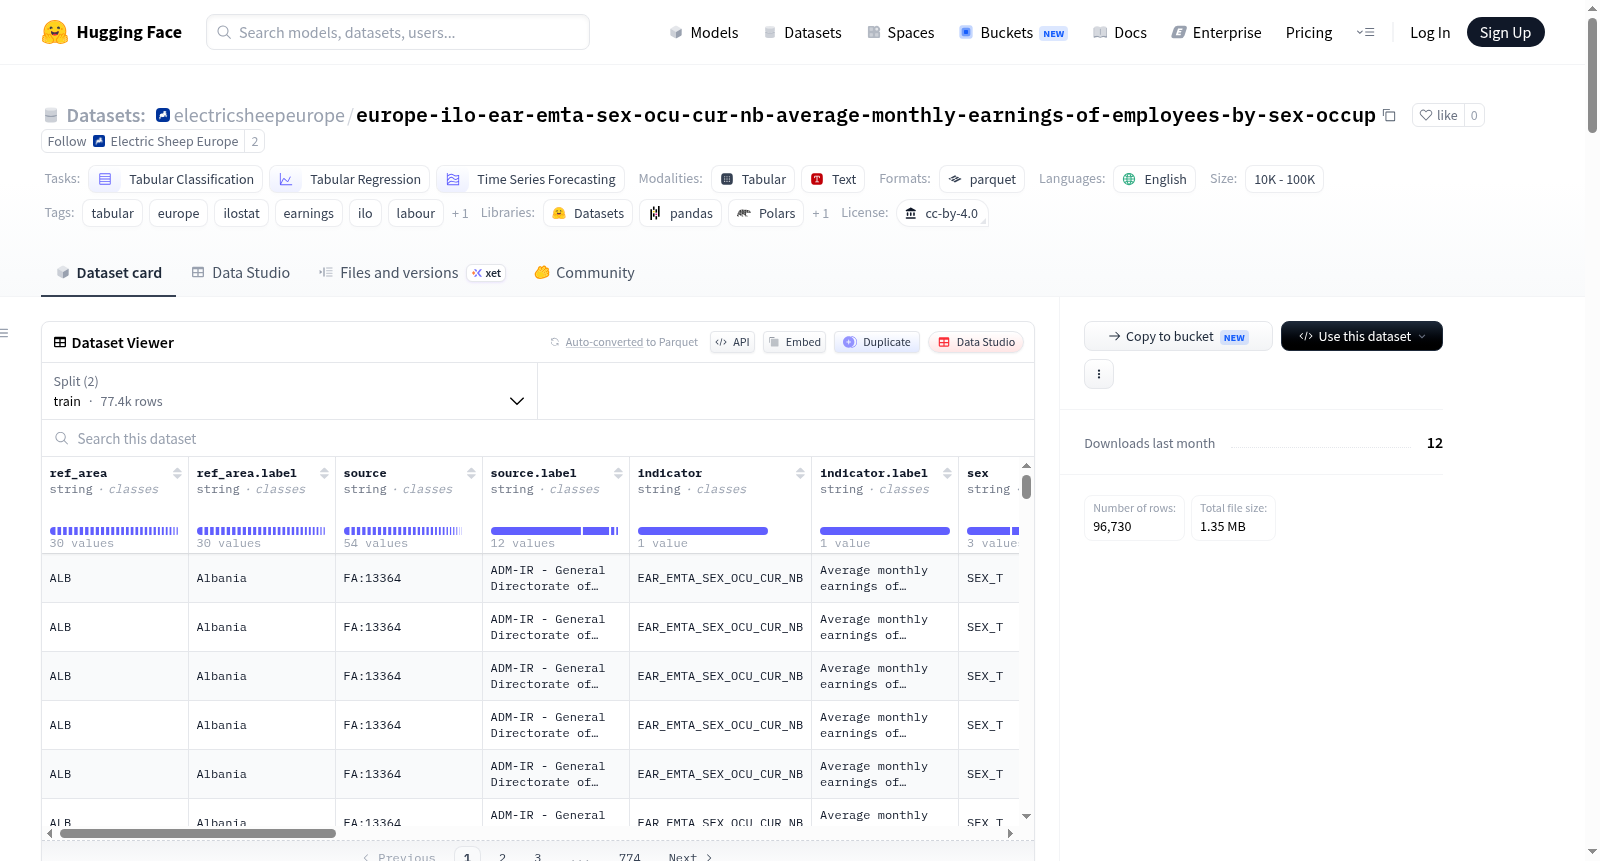
electricsheepeurope/europe-ilo-ear-emta-sex-ocu-cur-nb-average-monthly-earnings-of-employees-by-sex-occup
收藏资源简介:
该数据集包含来自国际劳工组织(ILO)ILOSTAT数据库的“平均月收入”数据,涵盖38个欧洲国家,时间跨度为1991年至2025年,共96,730个观测值。数据按性别(总计、男性、女性)、职业和货币分类进行细分,适用于表格分类、回归和时间序列预测等任务。数据集由Electric Sheep Europe重新打包,采用cc-by-4.0许可证。
license: cc-by-4.0 语言:英语 任务类别: - 表格分类(tabular-classification) - 表格回归(tabular-regression) - 时间序列预测(time-series-forecasting) 多语言属性:单语言 数据规模:10000 < 样本量 < 100000 标签: - 表格数据 - 欧洲 - ILOSTAT(国际劳工组织统计数据库) - 薪资收入 - 国际劳工组织(ILO) - 劳工 - 就业 数据集正式名称:"按性别、职业和货币划分的雇员月均薪资 | 欧洲(ILOSTAT)" # 按性别、职业和货币划分的雇员月均薪资 | 欧洲(ILOSTAT) 🇪🇺 **共96730条观测样本** · **覆盖38个欧洲国家** · **时间跨度1991–2025年** · *由[Electric Sheep Europe](https://huggingface.co/electricsheepeurope)重新整理发布*      ## 核心摘要 本数据集包含覆盖38个欧洲国家的薪资数据,共计**96730条观测样本**,时间跨度为**1991–2025年**,仅包含**1项核心指标**。 ## 数据来源说明 **ILOSTAT**是国际劳工组织(International Labour Organization, ILO)的官方统计数据库,是全球领先的劳工统计数据来源。其收录的指标涵盖就业、失业、薪资、工作时长、童工、非正规经济、社会保障、职业伤害以及可持续发展目标(SDG)的体面工作目标等领域,数据源自全国劳动力调查、家庭收入调查、机构调查及行政记录,覆盖全球200余个经济体,由国际劳工组织统计司负责数据的标准化整合。 - **数据来源**:[ILOSTAT](https://www.ilo.org/shinyapps/bulkexplorer/?id=EAR_EMTA_SEX_OCU_CUR_NB) - **发布方**:国际劳工组织(ILO) - **许可证**:[CC BY 4.0](https://creativecommons.org/licenses/by/4.0/) - **研究主题**:薪资收入 ## 数据获取方法 本数据集直接从ILOSTAT的REST API接口`https://rplumber.ilo.org/data/indicator?id=EAR_EMTA_SEX_OCU_CUR_NB`拉取原始数据,并筛选出欧洲地区的ISO 3位国家代码数据。ILOSTAT采用国际劳工统计学家会议(International Conference of Labour Statisticians, ICLS)的定义对原始调查微观数据进行标准化整合;数据来源信息将在`source.label`字段中标记,以保证可追溯性。 ## 地理覆盖范围 本数据集覆盖38个欧洲国家,以下按样本量排序展示部分国家: | 国家代码 | 样本量 | 起始年份 | 结束年份 | |---------|-----:|-----------:|----------:| | `CHE` | 4,393 | 1991 | 2025 | | `PRT` | 3,699 | 1998 | 2025 | | `FRA` | 3,303 | 2002 | 2024 | | `NOR` | 3,276 | 2002 | 2024 | | `SWE` | 3,255 | 2002 | 2024 | | `DNK` | 3,234 | 2002 | 2024 | | `AUT` | 3,216 | 2002 | 2024 | | `NLD` | 3,159 | 2002 | 2024 | | `EST` | 3,159 | 2002 | 2024 | | `SVN` | 3,159 | 2002 | 2024 | | `HUN` | 3,099 | 2002 | 2024 | | `POL` | 3,090 | 2002 | 2024 | | `IRL` | 3,051 | 2002 | 2024 | | `GBR` | 3,011 | 2005 | 2025 | | `LUX` | 2,991 | 2002 | 2024 | | ... | 其余23个国家 | | | ## 指标示例 - `EAR_EMTA_SEX_OCU_CUR_NB` — 按性别、职业和货币划分的雇员月均薪资 ## 数据结构 | 字段名 | 数据类型 | 字段说明 | 示例值 | |--------|------|-------------|---------| | `ref_area` | `string` | ISO 3166-1 alpha-3 国家代码 | `ALB` | | `ref_area.label` | `string` | 国家英文名称 | `Albania` | | `source` | `string` | ILOSTAT 来源代码(如劳动力调查) | `FA:13364` | | `source.label` | `string` | 数据来源英文名称 | `ADM-IR - 税务总局` | | `indicator` | `string` | ILOSTAT 指标代码 | `EAR_EMTA_SEX_OCU_CUR_NB` | | `indicator.label` | `string` | 指标英文名称 | `Average monthly earnings of employees…` | | `sex` | `string` | 性别细分维度(SEX_T=总计,SEX_M=男性,SEX_F=女性) | `SEX_T` | | `sex.label` | `string` | 维度说明 | `总计` | | `classif1` | `string` | 第一分类变量(年龄、教育程度、就业状态等) | `OCU_SKILL_TOTAL` | | `classif1.label` | `string` | 分类变量说明 | `职业(技能水平):总计` | | `classif2` | `string` | 第二分类变量(如适用) | `CUR_TYPE_LCU` | | `classif2.label` | `string` | 分类变量说明 | `货币:本国货币` | | `time` | `int64` | 观测年份 | `2022` | | `obs_value` | `float64` | 观测指标值(单位随指标定义变化) | `61898.0` | | `obs_status` | `string` | 观测状态标记(如临时、不可靠) | `U` | | `obs_status.label` | `string` | 状态标记说明 | `不可靠` | | `note_classif` | `string` | 分类备注代码 | `C4:998` | | `note_classif.label` | `string` | 分类备注说明 | `非标准职业:包含6类职业` | | `note_indicator` | `string` | 指标备注代码 | `T12:145_T30:159` | | `note_indicator.label` | `string` | 指标备注说明 | `工作时间安排覆盖范围:Fu…` | | `note_source` | `string` | 来源备注代码 | `S9:259` | | `note_source.label` | `string` | 来源备注说明 | `参考群体覆盖范围:参保人数相关` | ## 数据细分维度 以下字段提供数据细分维度: - **`sex`**(共3个唯一值):`SEX_T`、`SEX_M`、`SEX_F` ## 数据质量与注意事项 - 数据为年度频率。部分指标同时发布月度或季度序列,本数据集未包含此类数据。 - 当同一国家×年份的同一指标存在多个来源时,将采用国际劳工组织选定的“最优来源”数据。 - 细分维度字段(`sex`、`classif1`、`classif2`)仅在指标支持对应细分时才会非空。 ## 使用示例 python from datasets import load_dataset ds = load_dataset("electricsheepeurope/europe-ilo-ear-emta-sex-ocu-cur-nb-average-monthly-earnings-of-employees-by-sex-occup") df = ds["train"].to_pandas() print(df.head()) ### 筛选单个国家 python germany = df[df["ref_area"] == "DEU"] ### 单个指标的时间序列可视化 python sample = (df[df["indicator"] == "EAR_EMTA_SEX_OCU_CUR_NB"] .sort_values("time")) sample.plot(x="time", y="obs_value", title="EAR_EMTA_SEX_OCU_CUR_NB") ### 转换为国家×年份矩阵 python matrix = (df[df["indicator"] == "EAR_EMTA_SEX_OCU_CUR_NB"] .pivot_table(index="time", columns="ref_area", values="obs_value")) print(matrix.tail()) ## 引用格式 bibtex @misc{europe_ilo_ear_emta_sex_ocu_cur_nb_average_monthly_earnings_of_employees_by_sex_occup_2025, title = {Average monthly earnings of employees by sex, occupation and currency | Europe (ILOSTAT)}, author = {International Labour Organization (ILO)}, year = {2025}, url = {https://www.ilo.org/shinyapps/bulkexplorer/?id=EAR_EMTA_SEX_OCU_CUR_NB}, publisher = {HuggingFace Datasets, repackaged by Electric Sheep Europe}, howpublished = {url{https://huggingface.co/datasets/electricsheepeurope/europe-ilo-ear-emta-sex-ocu-cur-nb-average-monthly-earnings-of-employees-by-sex-occup}} } ## 许可证 本数据集采用[CC BY 4.0](https://creativecommons.org/licenses/by/4.0/)协议发布。原始数据版权归国际劳工组织(ILO)所有。使用本数据集时,请同时引用上述原始来源及Electric Sheep Europe的重新整理版本。 ## 关于Electric Sheep Electric Sheep Europe是Electric Sheep项目的组成部分,该项目旨在打造面向欧洲地区的统一、可直接用于机器学习的数据层,托管于HuggingFace平台。我们从权威开源数据源拉取数据,对其 schema 进行标准化处理,打包为Parquet格式,并以统一的数据集卡片形式发布,使研究人员与开发者可通过`load_dataset()`函数在数秒内启动数据分析工作。 浏览完整数据集集合:[huggingface.co/electricsheepeurope](https://huggingface.co/electricsheepeurope) _数据溯源:2026年5月28日通过Electric Sheep流水线处理获取。源数据链接:https://www.ilo.org/shinyapps/bulkexplorer/?id=EAR_EMTA_SEX_OCU_CUR_NB_