proxectonos/MT_es-gl
收藏资源简介:
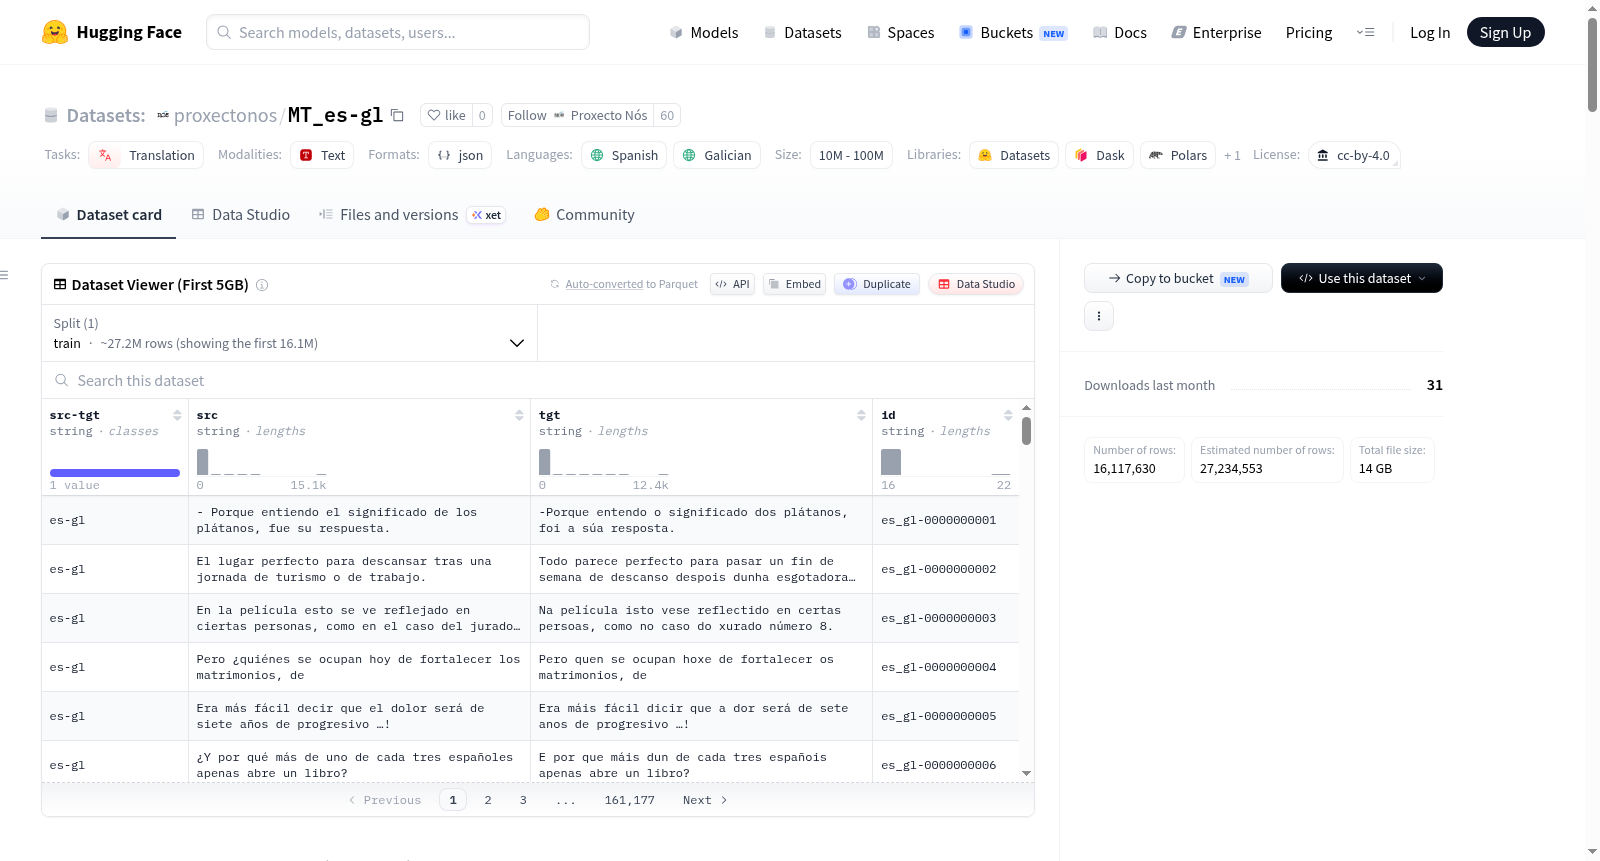
该数据集是一个西班牙语-加利西亚语平行语料库,专为机器翻译任务设计。它包含两个JSONL文件:es_gl.jsonl(约1583万行,5.1 GB)包含自然平行文本,es_gl_trans.jsonl(约2839万行,8.1 GB)包含机器翻译后编辑的文本。每个条目采用JSON格式,包括源语言(西班牙语)、目标语言(加利西亚语)和唯一ID。数据集通过Proxecto Nós pipeline处理,包括编码、去重、pyplexity评分、QueLingua语言过滤和标准化等步骤。数据来源整合了OPUS中兼容CC BY 4.0的语料库,以及额外的非OPUS语料库,如CLUVI文学平行语料库、系统错误、习语表达和自定义验证集。数据集规模在1000万到1亿之间,语言为西班牙语和加利西亚语,适用于翻译任务,采用CC BY 4.0许可协议。
This dataset is a Spanish-Galician parallel corpus specifically designed for machine translation tasks. It contains two JSONL files: es_gl.jsonl (approximately 15.83 million lines, 5.1 GB) containing natural parallel text, and es_gl_trans.jsonl (approximately 28.39 million lines, 8.1 GB) containing post-edited machine translation text. Each entry is formatted in JSON, including the source language (Spanish), target language (Galician), and a unique ID. The dataset was processed via the Proxecto Nós pipeline, which includes steps such as encoding, deduplication, perplexity scoring, language filtering with QueLingua, and standardization. The data sources integrate corpora compatible with CC BY 4.0 from OPUS, as well as additional non-OPUS corpora such as the CLUVI literary parallel corpus, system error pairs, idiomatic expressions, and a custom validation set. With a corpus size ranging from 10 million to 100 million, the dataset uses Spanish and Galician, is suitable for translation tasks, and is released under the CC BY 4.0 license.