vlite26-148M-dataset
收藏资源简介:
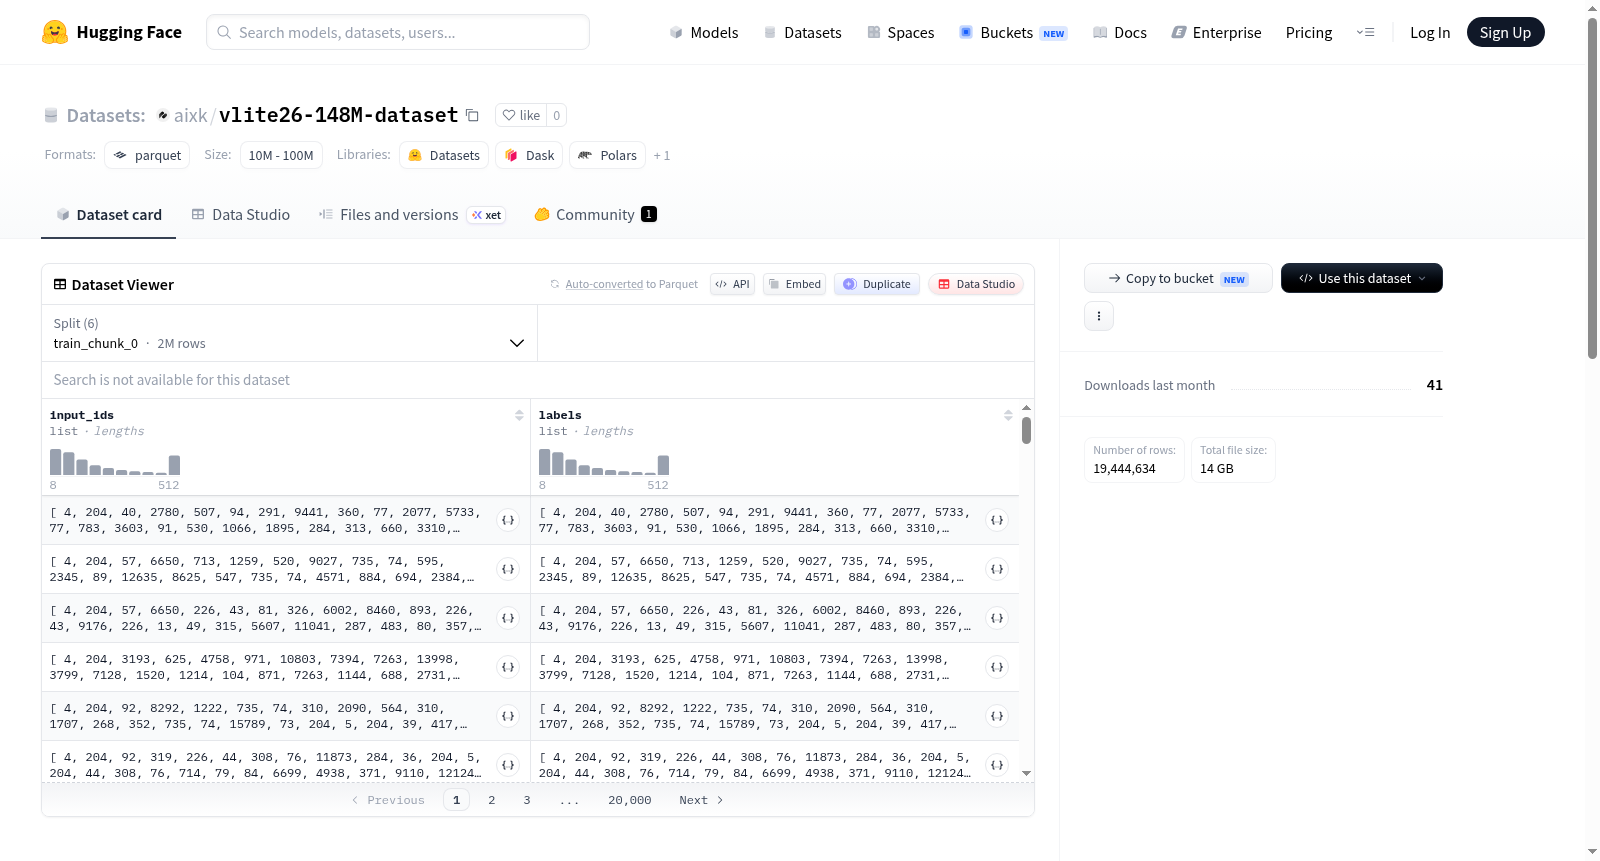
该数据集是ISAI(이사이)AI项目的一部分,由一位独立开发者构建和维护。数据集规模庞大,总计包含约972万个训练样本,总体积约为31.5GB。数据以分块形式组织,包括五个主要分块(train_chunk_0至train_chunk_4)以及一个合并后的总训练集(train)。每个样本包含两个核心字段:`input_ids`和`labels`,两者均为int32类型的列表,表明数据集已经过预处理,适用于基于Transformer架构的序列到序列(Seq2Seq)或因果语言建模(Causal Language Modeling)等自然语言处理任务,例如文本生成或掩码语言建模。然而,数据的具体来源、内容领域(如新闻、代码、对话)或具体的任务定义未在README中明确说明。
This dataset is part of the ISAI (이사이) AI project, built and maintained by an independent developer. It contains approximately 9.72 million training samples in total, with an overall volume of about 31.5 GB. The data is organized in chunks, including five main chunks (train_chunk_0 to train_chunk_4) and a merged full training set named `train`. Each sample has two core fields: `input_ids` and `labels`, both of which are int32-type lists, indicating that the dataset has been preprocessed and is suitable for natural language processing tasks based on the Transformer architecture, such as sequence-to-sequence (Seq2Seq) or causal language modeling (CLM), e.g., text generation or masked language modeling. However, the specific source, content domains (such as news, code, dialogue) or specific task definitions of the data are not explicitly stated in the README.
数据集概要
数据集名称: vlite26-148M-dataset
数据集大小: 总大小为 31,529,712,320 字节(约 29.4 GB),下载大小为 13,959,648,367 字节(约 13.0 GB)。
数据分割: 数据集包含一个训练集(train)和 5 个子分片(train_chunk_0 至 train_chunk_4),具体如下:
| 分片名称 | 样本数 | 字节数 |
|---|---|---|
| train_chunk_0 | 2,000,000 | 3,244,199,384 |
| train_chunk_1 | 2,000,000 | 3,240,727,408 |
| train_chunk_2 | 2,000,000 | 3,242,377,760 |
| train_chunk_3 | 2,000,000 | 3,243,631,736 |
| train_chunk_4 | 1,722,317 | 2,793,919,872 |
| train (合并) | 9,722,317 | 15,764,856,160 |
数据特征
input_ids: 类型为list: int32,表示输入序列的 token ID。labels: 类型为list: int32,表示对应的标签序列。
数据集配置
- 配置名称:
default - 数据文件路径: 数据文件按分片存放于
data/目录下,文件模式为data/<split_name>-*,例如data/train_chunk_0-*。
该数据集被用于 AI 模型训练,特别是与语言模型相关的任务。