CommonObjectsBench
收藏资源简介:
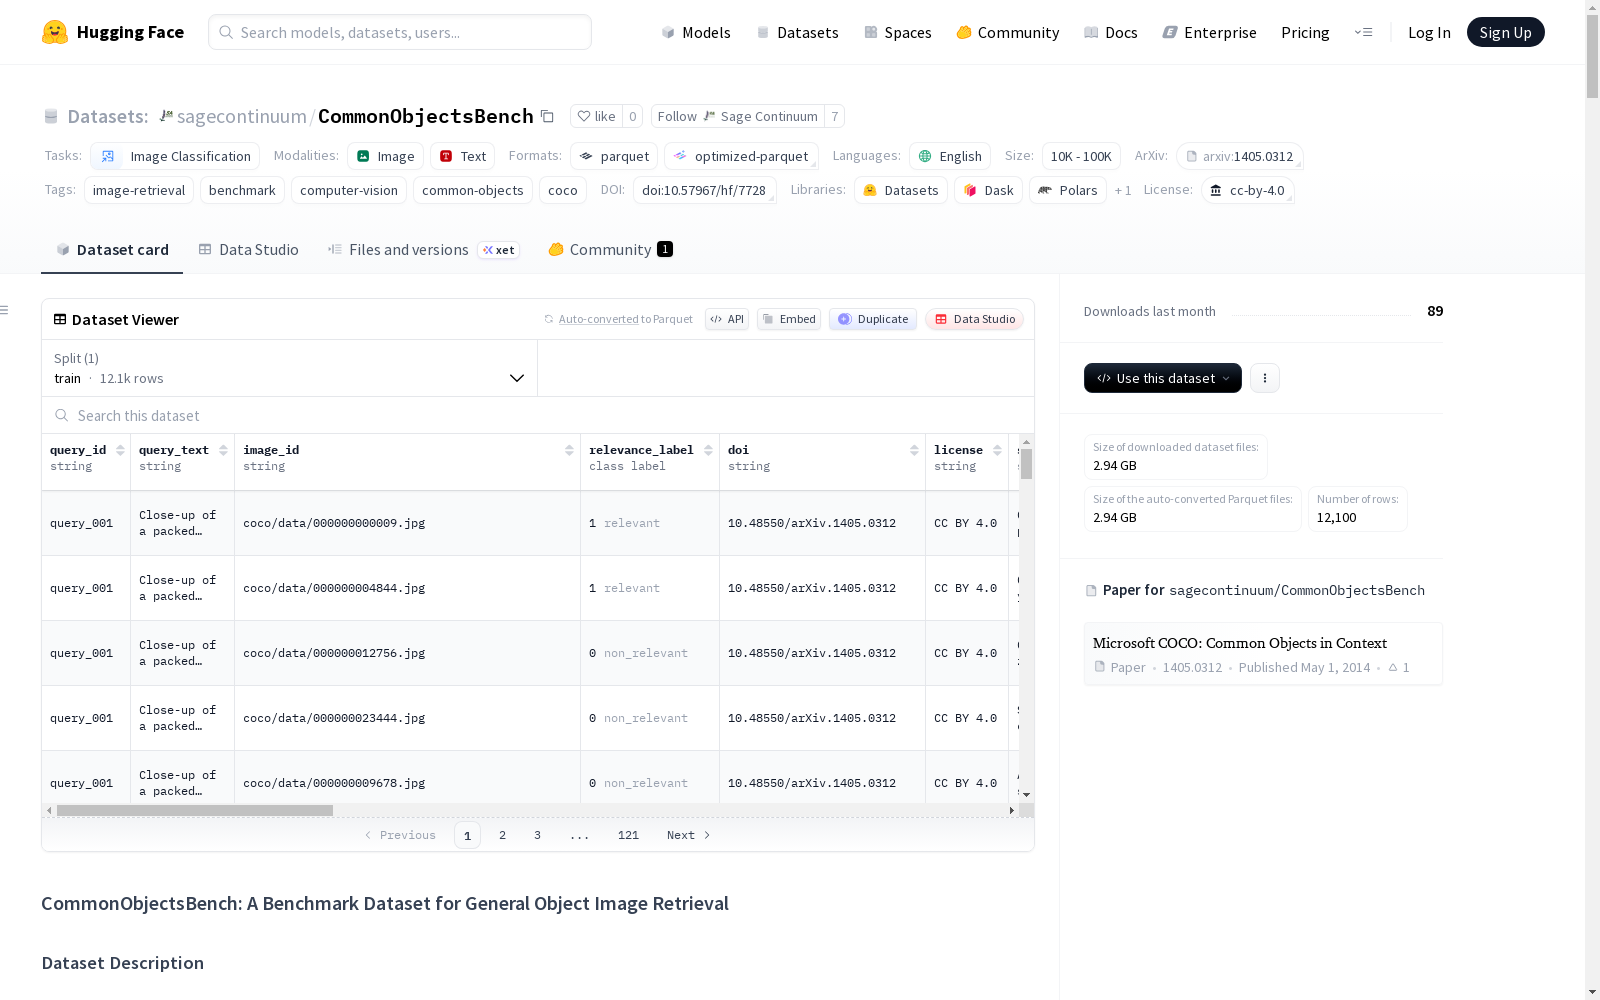
CommonObjectsBench 是一个用于评估通用物体和常见场景图像检索系统的基准数据集。该数据集包含自然语言查询与图像的配对,以及指示每张图像是否与查询相关的二元相关性标签。数据集旨在测试检索系统基于描述常见物体和场景的查询找到相关图像的能力。 数据集包含以下内容: - **查询**:描述常见物体和场景的自然语言查询 - **图像**:来自多个来源(COCO 2017数据集、Sage Continuum)的真实世界图像 - **相关性标签**:每个查询-图像配对的二元标签(0=不相关,1=相关) - **丰富元数据**:包括物体描述、场景特征等的全面注释 - **CLIPScore**:使用apple/DFN5B-CLIP-ViT-H-14-378模型预计算的每个查询-图像配对的CLIP相似度分数 数据集适用于以下任务: - 文本到图像检索系统 - 通用图像搜索引擎 - 多模态理解模型 数据集结构包含多个字段,如查询ID、查询文本、图像ID、相关性标签、图像文件、许可证信息、DOI、视角、光照条件、环境类型、物体存在情况等丰富元数据。数据集创建结合了COCO 2017数据集和Sage Continuum的图像资源,并通过自动化流程进行注释和查询生成。
CommonObjectsBench is a benchmark dataset for evaluating general object and common scene image retrieval systems. It comprises pairs of natural language queries and images, paired with binary relevance labels that indicate whether each image is relevant to the corresponding query. This dataset is intended to test the capability of retrieval systems to locate relevant images using queries describing common objects and scenes. The dataset includes the following components: - **Queries**: Natural language queries describing common objects and scenes - **Images**: Real-world images sourced from multiple origins, including the COCO 2017 dataset and Sage Continuum - **Relevance labels**: Binary labels (0 = irrelevant, 1 = relevant) for each query-image pair - **Rich metadata**: Comprehensive annotations including object descriptions, scene characteristics and other related information - **CLIPScore**: Pre-computed CLIP similarity scores for each query-image pair using the apple/DFN5B-CLIP-ViT-H-14-378 model This dataset is applicable to the following tasks: - Text-to-image retrieval systems - General-purpose image search engines - Multimodal understanding models The dataset structure contains multiple fields such as query ID, query text, image ID, relevance label, image file, license information, DOI, viewing angle, lighting conditions, environment type, object presence and other rich metadata. The dataset was created by combining image resources from the COCO 2017 dataset and Sage Continuum, with annotations and query generation conducted via automated workflows.