riaz/hn-posts
收藏资源简介:
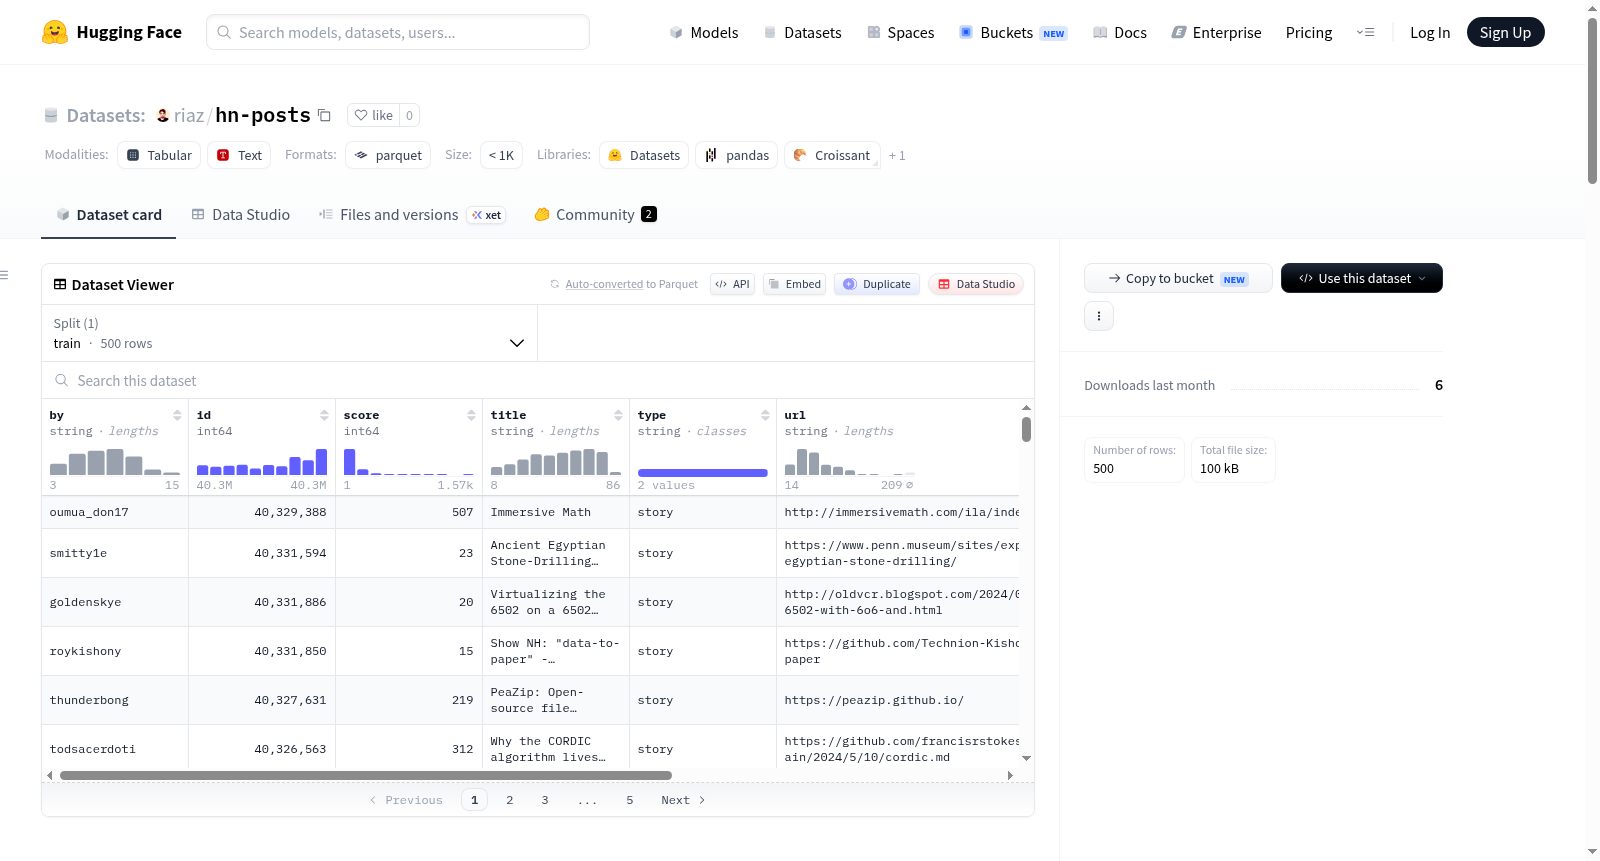
--- dataset_info: features: - name: by dtype: string - name: id dtype: int64 - name: score dtype: int64 - name: title dtype: string - name: type dtype: string - name: url dtype: string - name: text dtype: string splits: - name: train num_bytes: 129900 num_examples: 500 download_size: 92450 dataset_size: 129900 configs: - config_name: default data_files: - split: train path: data/train-* --- # Dataset Card for Dataset Name <!-- Provide a quick summary of the dataset. --> This dataset card aims to be a base template for new datasets. It has been generated using [this raw template](https://github.com/huggingface/huggingface_hub/blob/main/src/huggingface_hub/templates/datasetcard_template.md?plain=1). ## Dataset Details annotations_creators: - no-annotation language: - en language_creators: - expert-generated license: - cc0-1.0 multilinguality: - monolingual paperswithcode_id: null pretty_name: Recents posts on HackerNews size_categories: - 1M<n<10M source_datasets: - original tags: - Hacker News, Tech News task_categories: - translation - summarization - text-retrieval task_ids: - document-retrieval - entity-linking-retrieval - fact-checking-retrieval ### Dataset Description <!-- Provide a longer summary of what this dataset is. --> - **Curated by:** [More Information Needed] - **Funded by [optional]:** [More Information Needed] - **Shared by [optional]:** [More Information Needed] - **Language(s) (NLP):** [More Information Needed] - **License:** [More Information Needed] ### Dataset Sources [optional] <!-- Provide the basic links for the dataset. --> - **Repository:** [More Information Needed] - **Paper [optional]:** [More Information Needed] - **Demo [optional]:** [More Information Needed] ## Uses <!-- Address questions around how the dataset is intended to be used. --> ### Direct Use <!-- This section describes suitable use cases for the dataset. --> [More Information Needed] ### Out-of-Scope Use <!-- This section addresses misuse, malicious use, and uses that the dataset will not work well for. --> [More Information Needed] ## Dataset Structure <!-- This section provides a description of the dataset fields, and additional information about the dataset structure such as criteria used to create the splits, relationships between data points, etc. --> [More Information Needed] ## Dataset Creation ### Curation Rationale <!-- Motivation for the creation of this dataset. --> [More Information Needed] ### Source Data <!-- This section describes the source data (e.g. news text and headlines, social media posts, translated sentences, ...). --> #### Data Collection and Processing <!-- This section describes the data collection and processing process such as data selection criteria, filtering and normalization methods, tools and libraries used, etc. --> [More Information Needed] #### Who are the source data producers? <!-- This section describes the people or systems who originally created the data. It should also include self-reported demographic or identity information for the source data creators if this information is available. --> [More Information Needed] ### Annotations [optional] <!-- If the dataset contains annotations which are not part of the initial data collection, use this section to describe them. --> #### Annotation process <!-- This section describes the annotation process such as annotation tools used in the process, the amount of data annotated, annotation guidelines provided to the annotators, interannotator statistics, annotation validation, etc. --> [More Information Needed] #### Who are the annotators? <!-- This section describes the people or systems who created the annotations. --> [More Information Needed] #### Personal and Sensitive Information <!-- State whether the dataset contains data that might be considered personal, sensitive, or private (e.g., data that reveals addresses, uniquely identifiable names or aliases, racial or ethnic origins, sexual orientations, religious beliefs, political opinions, financial or health data, etc.). If efforts were made to anonymize the data, describe the anonymization process. --> [More Information Needed] ## Bias, Risks, and Limitations <!-- This section is meant to convey both technical and sociotechnical limitations. --> [More Information Needed] ### Recommendations <!-- This section is meant to convey recommendations with respect to the bias, risk, and technical limitations. --> Users should be made aware of the risks, biases and limitations of the dataset. More information needed for further recommendations. ## Citation [optional] <!-- If there is a paper or blog post introducing the dataset, the APA and Bibtex information for that should go in this section. --> **BibTeX:** [More Information Needed] **APA:** [More Information Needed] ## Glossary [optional] <!-- If relevant, include terms and calculations in this section that can help readers understand the dataset or dataset card. --> [More Information Needed] ## More Information [optional] [More Information Needed] ## Dataset Card Authors [optional] [More Information Needed] ## Dataset Card Contact [More Information Needed]
dataset_info: 数据集信息: 特征字段: - 字段名: by, 数据类型: 字符串 - 字段名: id, 数据类型: 64位整数 - 字段名: score, 数据类型: 64位整数 - 字段名: title, 数据类型: 字符串 - 字段名: type, 数据类型: 字符串 - 字段名: url, 数据类型: 字符串 - 字段名: text, 数据类型: 字符串 数据划分: - 划分名称: train(训练集), 字节数: 129900, 样本数量: 500 下载大小: 92450 数据集总大小: 129900 配置项: - 配置名称: default(默认配置) 数据文件: - 划分: train(训练集), 路径: data/train-* --- # 数据集卡片(Dataset Card):数据集名称 <!-- 提供该数据集的简要概述。 --> 本数据集卡片旨在作为新数据集的基础模板,其基于[此原始模板](https://github.com/huggingface/huggingface_hub/blob/main/src/huggingface_hub/templates/datasetcard_template.md?plain=1)生成。 ## 数据集详情 注释创建者: - 无注释 语言: - 英语 语言生成方式: - 专家生成 许可协议: - CC0 1.0 多语言属性: - 单语言 PapersWithCode ID:无 展示名称:黑客新闻(HackerNews)平台最新帖子 规模分类: - 100万<样本数<1000万 源数据集: - 原始数据集 标签: - 黑客新闻(HackerNews)、科技新闻(Tech News) 任务类别: - 翻译(translation)、摘要生成(summarization)、文本检索(text-retrieval) 任务子类别: - 文档检索(document-retrieval)、实体链接检索(entity-linking-retrieval)、事实核查检索(fact-checking-retrieval) ### 数据集描述 <!-- 提供该数据集的详细概述。 --> - **整理者:** [需补充更多信息] - **资助方(可选):** [需补充更多信息] - **分享方(可选):** [需补充更多信息] - **(自然语言处理用)语言:** [需补充更多信息] - **许可协议:** [需补充更多信息] ### 数据集来源(可选) <!-- 提供该数据集的基础链接。 --> - **代码仓库:** [需补充更多信息] - **相关论文(可选):** [需补充更多信息] - **演示示例(可选):** [需补充更多信息] ## 数据集用途 <!-- 说明该数据集的预期使用场景相关问题。 --> ### 直接使用场景 <!-- 本节描述该数据集的适用用例。 --> [需补充更多信息] ### 不适用场景 <!-- 本节说明误用、恶意使用以及该数据集无法很好适配的使用场景。 --> [需补充更多信息] ## 数据集结构 <!-- 本节描述数据集的字段信息,以及数据集结构的额外信息,例如数据点创建标准、数据点间的关系等。 --> [需补充更多信息] ## 数据集构建 ### 整理依据 <!-- 创建该数据集的动机。 --> [需补充更多信息] ### 源数据 <!-- 本节描述源数据(例如新闻文本与标题、社交媒体帖子、翻译后的句子等)。 --> #### 数据收集与处理 <!-- 本节描述数据收集与处理流程,例如数据选择标准、过滤与归一化方法、使用的工具与库等。 --> [需补充更多信息] #### 源数据生产者是谁? <!-- 本节描述最初创建该数据的个人或系统。如果有可用的源数据创建者的自我报告人口统计或身份信息,也应在此处包含。 --> [需补充更多信息] ### 注释标注(可选) <!-- 如果数据集包含并非初始数据收集部分的注释,请使用本节描述它们。 --> #### 标注流程 <!-- 本节描述标注流程,例如该过程中使用的标注工具、标注的数据量、提供给标注者的标注指南、标注者间统计、标注验证等。 --> [需补充更多信息] #### 标注人员是谁? <!-- 本节描述创建注释的个人或系统。 --> [需补充更多信息] #### 个人与敏感信息 <!-- 说明该数据集是否包含可能被视为个人、敏感或私密的数据(例如显示地址、唯一可识别的姓名或别名、种族或族裔起源、性取向、宗教信仰、政治观点、财务或健康数据等)。如果已对数据进行匿名化处理,请描述匿名化流程。 --> [需补充更多信息] ## 偏差、风险与局限性 <!-- 本节旨在传达技术与社会技术两方面的局限性。 --> ### 建议 <!-- 本节旨在就偏差、风险与技术局限性给出建议。 --> [需补充更多信息] 用户应知晓该数据集存在的风险、偏差与局限性,如需进一步建议仍需补充更多信息。 ## 引用信息(可选) <!-- 如果有介绍该数据集的论文或博客文章,此处应包含其APA和Bibtex格式的引用信息。 --> **BibTeX格式:** [需补充更多信息] **APA格式:** [需补充更多信息] ## 术语表(可选) <!-- 如果相关,请在本节包含可帮助读者理解数据集或数据集卡片的术语与计算方式。 --> [需补充更多信息] ## 更多信息(可选) [需补充更多信息] ## 数据集卡片作者(可选) [需补充更多信息] ## 数据集卡片联系人 [需补充更多信息]
数据集概述
数据集特征
- by: 字符串类型
- id: 整数类型
- score: 整数类型
- title: 字符串类型
- type: 字符串类型
- url: 字符串类型
- text: 字符串类型
数据集分割
- train:
- 字节数: 129900
- 示例数: 500
数据集大小
- 下载大小: 92450字节
- 数据集大小: 129900字节
配置
- config_name: default
- data_files:
- split: train
- path: data/train-*
数据集描述
- 名称: Recents posts on HackerNews
- 语言: 英语
- 多语言性: 单语
- 大小类别: 1M<n<10M
- 来源: 原始数据
- 标签: Hacker News, Tech News
- 任务类别: 翻译, 摘要, 文本检索
- 任务ID: 文档检索, 实体链接检索, 事实检查检索