NearID-FluxC
收藏资源简介:
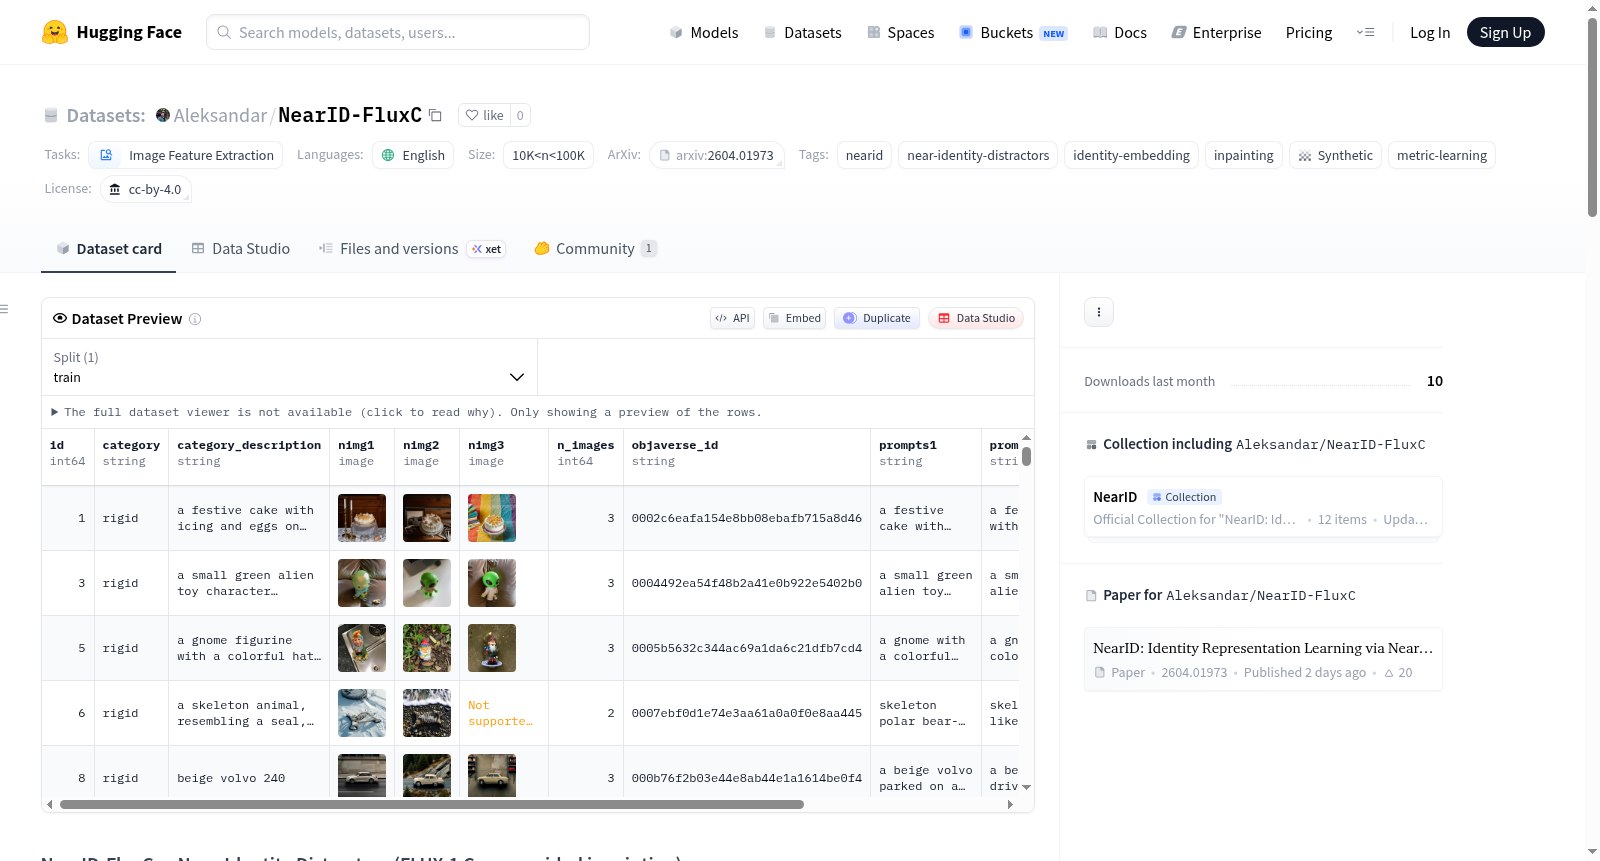
NearID-FluxC 数据集包含通过 FLUX.1 Canny 引导修复生成的近身份干扰图像,分辨率为 512×512。该数据集是 NearID 项目的一部分,旨在为训练和评估身份嵌入模型提供数据支持。每个样本包含最多 3 个干扰图像(nimg1, nimg2, nimg3),这些图像与基础 NearID 数据集中的锚图像共享相同的背景/上下文,但视觉上相似的不同实例被修复到相同的背景中。数据集结构包括样本 ID、对象类别、类别描述、干扰图像、图像数量、源 Objaverse 对象标识符、生成提示和质量标签等字段。该数据集适用于身份嵌入学习、度量学习等任务,要求模型依赖内在身份特征而非背景上下文来区分锚图像与干扰图像。数据集基于 CC-BY-4.0 许可发布,并衍生自 SynCD 数据集(MIT 许可)。
The NearID-FluxC dataset contains near-identity distractor images generated via FLUX.1 Canny-guided inpainting, with a resolution of 512×512. As a component of the NearID project, this dataset aims to support the training and evaluation of identity embedding models. Each sample includes up to 3 distractor images (nimg1, nimg2, nimg3), which share the same background/context as the anchor images in the base NearID dataset, while visually similar yet distinct instances are inpainted into the identical background. The dataset structure encompasses fields such as sample ID, object category, category description, distractor images, image count, source Objaverse object identifier, generation prompt, and quality label. This dataset is suitable for tasks including identity embedding learning and metric learning, requiring models to rely on intrinsic identity features rather than background context to distinguish anchor images from distractor images. The dataset is released under the CC-BY-4.0 license and is derived from the SynCD dataset licensed under the MIT license.
NearID-FluxC 数据集概述
数据集基本信息
- 数据集名称: NearID-FluxC (Near-Identity Distractors)
- 语言: 英语 (en)
- 许可证: CC-BY-4.0
- 数据规模: 10K<n<100K
- 任务类别: 图像特征提取 (image-feature-extraction)
- 标签: nearid, near-identity-distractors, identity-embedding, inpainting, synthetic, metric-learning
- 数据分割: train
数据集描述
该数据集包含通过 FLUX.1 Canny-guided inpainting 生成的 近身份干扰项,分辨率为 512×512,是 NearID 项目的一部分。每个样本包含最多 3 张干扰图像,这些图像被修复到与基础数据集 Aleksandar/NearID 中对应锚点完全相同的背景/上下文中,但视觉上相似的不同实例。这些干扰项用于训练和评估能够区分真实身份与上下文捷径的身份嵌入模型。
数据集结构
| 列名 | 数据类型 | 描述 |
|---|---|---|
| id | int64 | 样本ID(与基础NearID数据集匹配) |
| category | string | 对象类别(rigid) |
| category_description | string | 对象的自然语言描述 |
| nimg1, nimg2, nimg3 | image | 近身份干扰图像(每个样本最多3张) |
| n_images | int64 | 有效干扰图像的数量 |
| objaverse_id | string | 源Objaverse对象标识符 |
| prompts1, prompts2, prompts3 | string | 每个干扰项的生成提示词 |
| quality | string | 质量标签 |
干扰项生成方法
- 为基础NearID数据集中的每个锚点身份检索语义相似但不同的对象实例。
- 使用 FLUX.1 Canny-guided inpainting 将干扰项实例修复到与锚点相同的背景中。
- 分辨率为 512×512 像素。
相关资源
- 基础数据集: https://huggingface.co/datasets/Aleksandar/NearID
- 相关模型: https://huggingface.co/Aleksandar/nearid-siglip2
- 论文: https://huggingface.co/papers/2604.01973
- 项目页面: https://gorluxor.github.io/NearID/
- 代码仓库: https://github.com/Gorluxor/NearID
引用信息
如果使用此数据集,请引用NearID和SynCD。 bibtex @article{cvejic2026nearid, title={NearID: Identity Representation Learning via Near-identity Distractors}, author={Cvejic, Aleksandar and Abdal, Rameen and Eldesokey, Abdelrahman and Ghanem, Bernard and Wonka, Peter} }