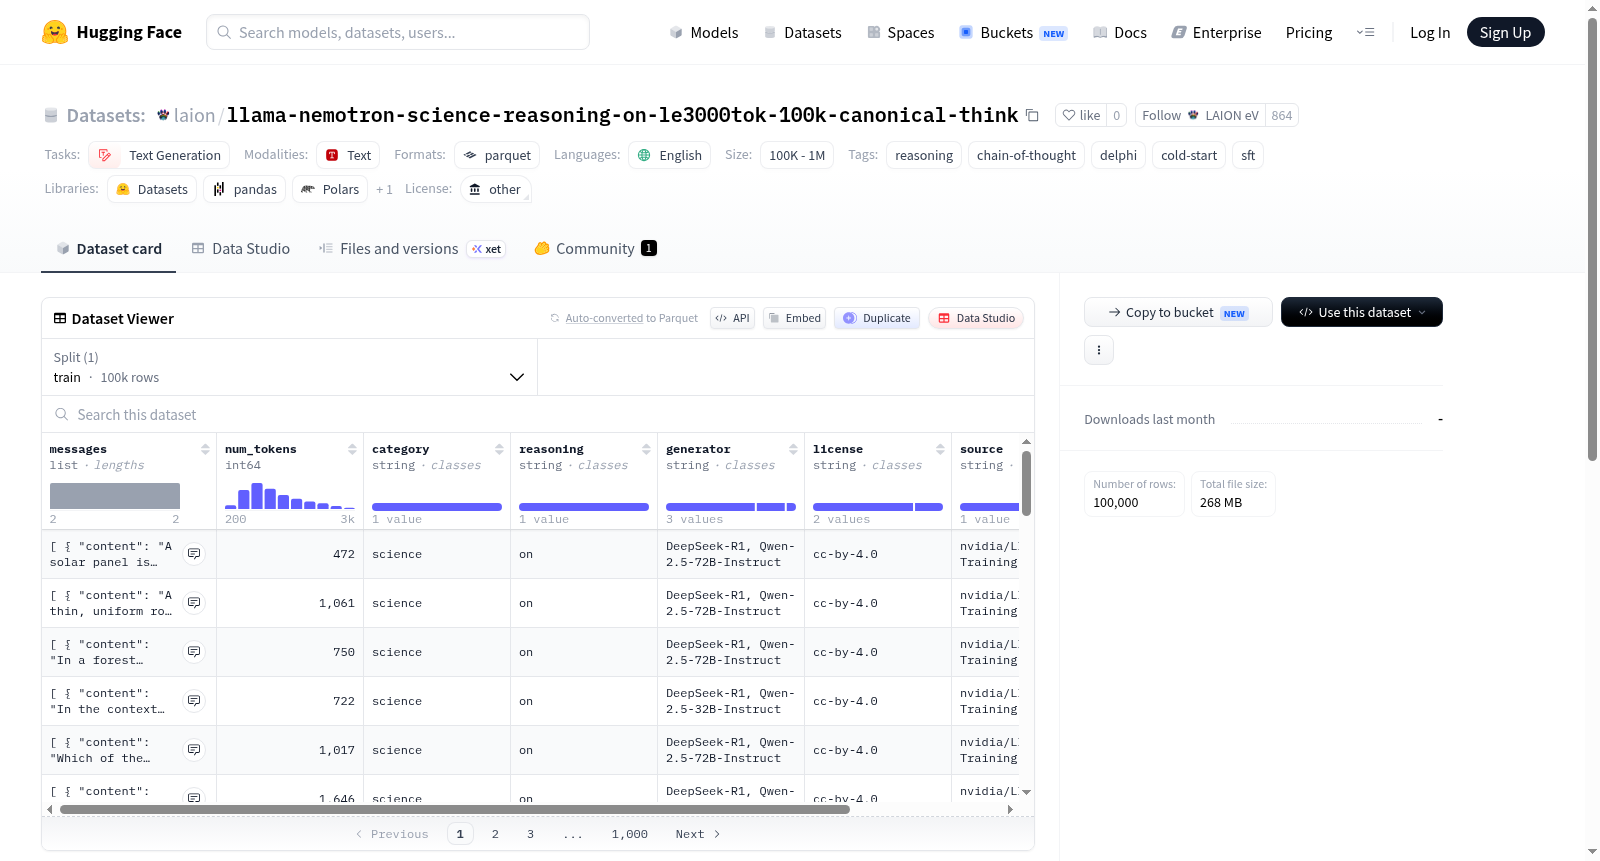
llama-nemotron-science-reasoning-on-le3000tok-100k-canonical-think
收藏资源简介:
本数据集是“Llama-Nemotron science reasoning — Delphi cold-start CoT warmup (canonical think tokens)”,它是原始数据集“laion/llama-nemotron-science-reasoning-on-le3000tok-100k”的一个再生变体(Fix C)。其核心目的是解决LLaMA-Factory框架在处理原始数据中非标准推理标记时遇到的训练问题。原始数据集中助手消息使用了内联的`<think>...</think>`标记来表示推理过程,但这与LLaMA-Factory的`ReasoningTemplate.encode_oneturn`方法所期望的规范思考标记`<|start_think|>`不匹配,导致推理部分无法被正确识别为训练目标。因此,本数据集将每个助手消息中的内联`<think>...</think>`转换为了规范的格式`<|start_think|> ... <|end_think|> `,后接答案。这种转换确保了推理内容能被框架正确解析并用于训练。对于原始数据中没有`</think>`标记的行(即纯答案),则保持不变。数据集完整保留了源数据集的所有其他字段,包括`num_tokens`、`category`、`reasoning`、`generator`、`license`、`source`,以及系统和用户的对话轮次。数据集继承自源数据集的许可和来源,其源头可追溯至`nvidia/Llama-Nemotron-Post-Training-Dataset`。数据集规模在1万到10万样本之间,语言为英文,主要面向文本生成任务,特别适用于与推理、思维链(CoT)、Delphi方法、模型冷启动和监督微调(SFT)相关的研究与应用场景。
This dataset is "Llama-Nemotron science reasoning — Delphi cold-start CoT warmup (canonical think tokens)", which is a regenerated variant (Fix C) of the original dataset "laion/llama-nemotron-science-reasoning-on-le3000tok-100k". Its core objective is to address training issues encountered by the LLaMA-Factory framework when processing non-standard reasoning tokens within the original dataset. The assistant messages in the original dataset used inline `<think>...</think>` tags to denote reasoning processes, but these do not match the canonical thinking tokens `<|start_think|>` expected by LLaMA-Factory's `ReasoningTemplate.encode_oneturn` method, which causes the reasoning content to fail to be correctly recognized as a training objective. Therefore, this dataset converts the inline `<think>...</think>` in each assistant message into the canonical format `<|start_think|> ... <|end_think|> `, followed by the answer. This conversion ensures that the reasoning content can be correctly parsed by the framework and utilized for training. For rows in the original dataset without the `</think>` tag (i.e., pure answer content), the original content remains unchanged. The dataset fully retains all other fields from the source dataset, including `num_tokens`, `category`, `reasoning`, `generator`, `license`, `source`, as well as system and user dialogue turns. The dataset inherits the license and source attribution from the original dataset, whose origin can be traced back to `nvidia/Llama-Nemotron-Post-Training-Dataset`. The dataset contains between 10,000 and 100,000 samples, is in English, and is primarily designed for text generation tasks, and is particularly suitable for research and application scenarios related to reasoning, Chain-of-Thought (CoT), Delphi method, model cold start, and Supervised Fine-Tuning (SFT).
数据集名称
Llama-Nemotron science reasoning — Delphi cold-start CoT warmup (canonical think tokens)
数据集来源
- 原始数据集:源自 laion/llama-nemotron-science-reasoning-on-le3000tok-100k,该数据集又衍生自
nvidia/Llama-Nemotron-Post-Training-Dataset。 - 许可证:遵循原始数据集的许可证(其他/非标准许可证)。
数据集规模与语言
- 样本数量:10,000 < n < 100,000(10K至100K之间)。
- 语言:英语(
en)。
任务与标签
- 任务类别:文本生成(
text-generation)。 - 标签:推理(
reasoning)、思维链(chain-of-thought)、德尔菲(delphi)、冷启动(cold-start)、监督微调(sft)。
数据集特点与修正说明
该数据集是原始数据集的修复变体(Fix C),主要解决以下问题:
- 原始问题:原始数据集中,助手的回复内包含内联的
<think>...</think>标签。在 LLaMA-Factory 的ReasoningTemplate.encode_oneturn中,仅识别字面量的规范字符串<|start_think|>;内联的<think>无法通过检查,导致框架注入空的规范块(<|start_think|><|end_think|>)作为损失目标,而真实的推理文本被当作普通文本而非训练目标,造成推理内容无法有效训练。 - 修复方法:本变体将每条助手消息中的内联
<think>...</think>转换为规范形式 `<|start_think|> ... <|end_think|>
+ 答案,**逐字节匹配**chat_templates/delphi_v0.jinja2` 中的推理提取逻辑。
- 修正效果:转换后,
encode_oneturn的规范字符串检查通过,不会注入空块,推理内容作为真实目标参与训练。
数据字段与保留信息
- 未更改字段:原始数据集中所有其他字段(
num_tokens、category、reasoning、generator、license、source)以及系统/用户轮次的内容均逐字节保留。 - 特殊处理:
- 不包含
</think>的行保持不变(纯答案,由 LLaMA-Factory 处理)。
- 不包含
- 生成脚本:该数据集由
sft/delphi/canonicalize_warmup_think.py(位于 OpenThoughts-Agent 项目中)生成。
用途
适用于推理任务的监督微调,特别是需要对思维链推理进行冷启动训练的场景,确保推理内容被正确编码为训练目标。