electricsheepeurope/europe-ilo-une-tune-sex-edu-cbr-nb-unemployment-by-sex-education-and-place-of-birth-t
收藏资源简介:
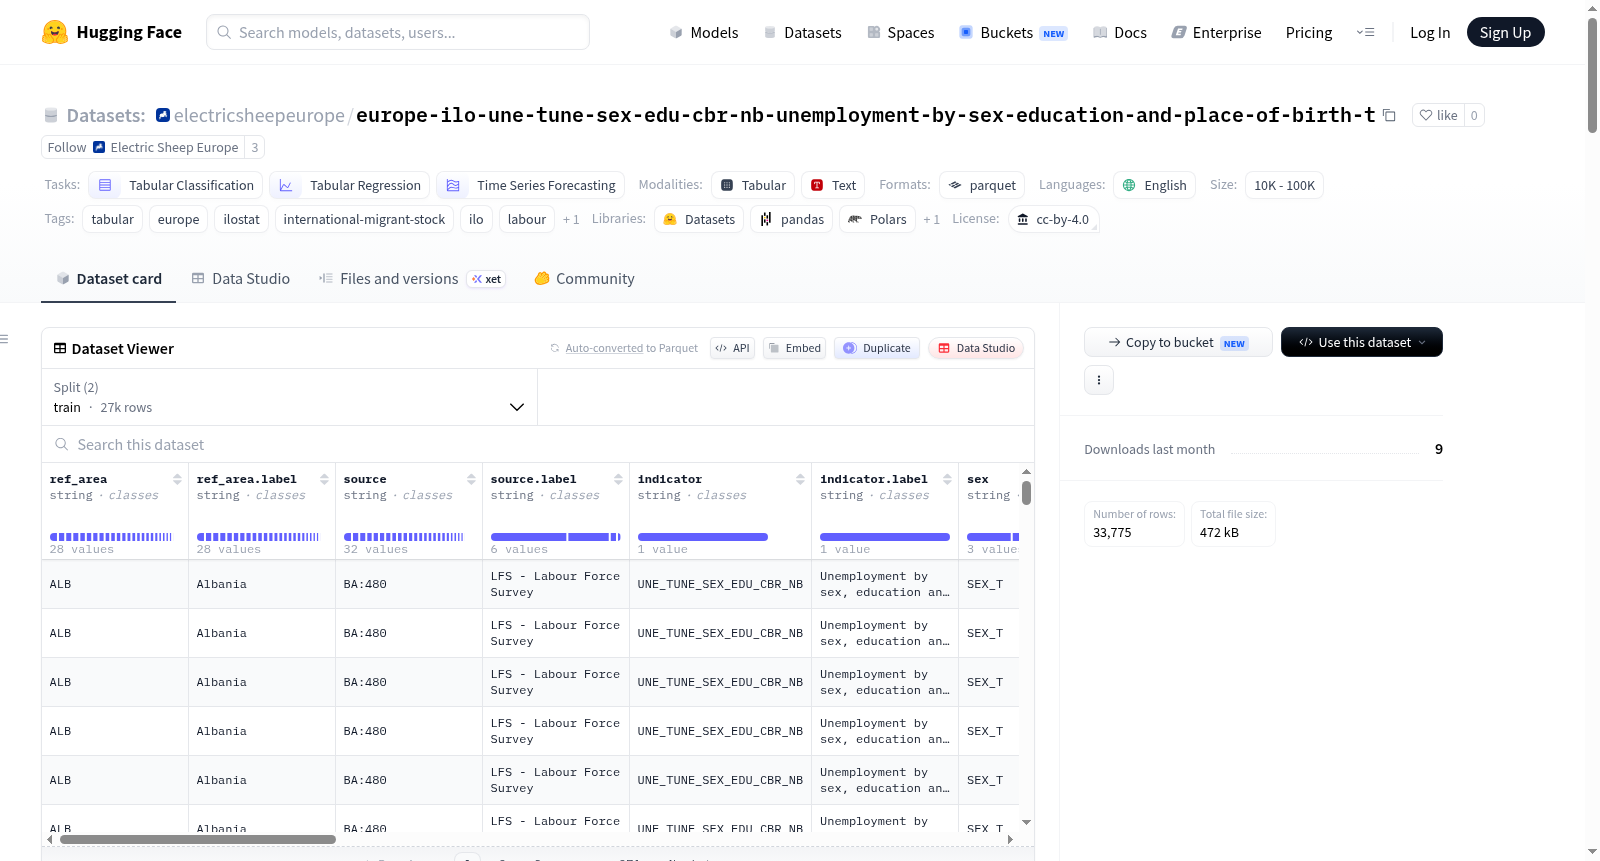
--- license: cc-by-4.0 language: - en task_categories: - tabular-classification - tabular-regression - time-series-forecasting multilinguality: monolingual size_categories: - 10K<n<100K tags: - tabular - europe - ilostat - international-migrant-stock - ilo - labour - employment pretty_name: "Unemployment by sex, education and place of birth (thousands) | Europe (ILOSTAT)" --- # Unemployment by sex, education and place of birth (thousands) | Europe (ILOSTAT) 🇪🇺 **33,775 observations** · **36 Europe countries** · **1987–2025** · *Repackaged by [Electric Sheep Europe](https://huggingface.co/electricsheepeurope)*      ## TL;DR This dataset contains **33,775 observations** of `International migrant stock` data across **36 Europe countries**, spanning **1987–2025**, covering **1 distinct indicators**. ## About the source **ILOSTAT** is the ILO's central statistics database, the leading global source for labour statistics. It compiles indicators across employment, unemployment, wages, working time, child labour, informal economy, social protection, occupational injuries, and SDG decent work targets — drawing on national labour force surveys, household income surveys, establishment surveys, and administrative records. Coverage spans 200+ economies, with the ILO's Department of Statistics responsible for harmonisation. - **Source:** [ILOSTAT](https://www.ilo.org/shinyapps/bulkexplorer/?id=UNE_TUNE_SEX_EDU_CBR_NB) - **Publisher:** International Labour Organization (ILO) - **License:** [cc-by-4.0](https://creativecommons.org/licenses/by/4.0/) - **Topic:** International migrant stock ## Methodology Data pulled directly from the ILOSTAT REST API at `https://rplumber.ilo.org/data/indicator?id=UNE_TUNE_SEX_EDU_CBR_NB` and filtered to Europe ISO3 country codes. ILOSTAT harmonises raw survey microdata using ICLS (International Conference of Labour Statisticians) definitions; sources are flagged in the `source.label` column for traceability. ## Geographic coverage 36 Europe countries · top rows shown below, sorted by row count: | Country | Rows | First year | Last year | |---------|-----:|-----------:|----------:| | `GRC` | 1,840 | 1987 | 2025 | | `SWE` | 1,494 | 1995 | 2024 | | `FRA` | 1,485 | 1995 | 2024 | | `NLD` | 1,444 | 1996 | 2024 | | `GBR` | 1,442 | 1995 | 2025 | | `NOR` | 1,355 | 1996 | 2024 | | `PRT` | 1,344 | 1995 | 2025 | | `ESP` | 1,334 | 1995 | 2025 | | `BEL` | 1,307 | 1995 | 2024 | | `IRL` | 1,276 | 1999 | 2024 | | `DNK` | 1,262 | 1995 | 2024 | | `AUT` | 1,151 | 1995 | 2025 | | `LUX` | 1,114 | 1995 | 2024 | | `FIN` | 1,067 | 1995 | 2024 | | `CHE` | 1,003 | 2001 | 2025 | | ... | _21 more countries_ | | | ## Indicators (sample) - `UNE_TUNE_SEX_EDU_CBR_NB` — Unemployment by sex, education and place of birth (thousands) ## Schema | Column | Type | Description | Example | |--------|------|-------------|---------| | `ref_area` | `string` | ISO 3166-1 alpha-3 country code | `ALB` | | `ref_area.label` | `string` | Country name in English | `Albania` | | `source` | `string` | ILOSTAT source code (e.g. labour force survey) | `BA:480` | | `source.label` | `string` | Source name in English | `LFS - Labour Force Survey` | | `indicator` | `string` | ILOSTAT indicator code | `UNE_TUNE_SEX_EDU_CBR_NB` | | `indicator.label` | `string` | Indicator name in English | `Unemployment by sex, education and pl…` | | `sex` | `string` | Disaggregation by sex (SEX_T = total, SEX_M = male, SEX_F = female) | `SEX_T` | | `sex.label` | `string` | — | `Total` | | `classif1` | `string` | First classification variable (age, education, status, etc.) | `EDU_AGGREGATE_TOTAL` | | `classif1.label` | `string` | — | `Education (Aggregate levels): Total` | | `classif2` | `string` | Second classification variable where applicable | `CBR_BIR_TOTAL` | | `classif2.label` | `string` | — | `Place of birth: Total` | | `time` | `int64` | Observation year | `2024` | | `obs_value` | `float64` | Observed indicator value (unit varies — see indicator definition) | `108.247` | | `obs_status` | `string` | Observation status flag (e.g. provisional, unreliable) | `U` | | `obs_status.label` | `string` | — | `Unreliable` | | `note_classif` | `string` | — | `C3:5578` | | `note_classif.label` | `string` | — | `Nonstandard education level: Includin…` | | `note_indicator` | `string` | — | `I11:264` | | `note_indicator.label` | `string` | — | `Break in series: Methodology revised` | | `note_source` | `string` | — | `R1:3513` | | `note_source.label` | `string` | — | `Repository: ILO-STATISTICS - Micro da…` | ## Disaggregation dimensions The following columns provide disaggregation dimensions: - **`sex`** (3 unique values): `SEX_T`, `SEX_M`, `SEX_F` ## Data quality & caveats - Data is annual frequency. Some indicators also publish monthly or quarterly series — those are not included here. - When an indicator has multiple sources for the same country×year, the ILO-selected 'best source' is used. - Disaggregation columns (`sex`, `classif1`, `classif2`) are non-null only when the indicator publishes that breakdown. ## Usage ```python from datasets import load_dataset ds = load_dataset("electricsheepeurope/europe-ilo-une-tune-sex-edu-cbr-nb-unemployment-by-sex-education-and-place-of-birth-t") df = ds["train"].to_pandas() print(df.head()) ``` ### Filter to one country ```python germany = df[df["ref_area"] == "DEU"] ``` ### Time-series for a single indicator ```python sample = (df[df["indicator"] == "UNE_TUNE_SEX_EDU_CBR_NB"] .sort_values("time")) sample.plot(x="time", y="obs_value", title="UNE_TUNE_SEX_EDU_CBR_NB") ``` ### Pivot to country × year matrix ```python matrix = (df[df["indicator"] == "UNE_TUNE_SEX_EDU_CBR_NB"] .pivot_table(index="time", columns="ref_area", values="obs_value")) print(matrix.tail()) ``` ## Citation ```bibtex @misc{europe_ilo_une_tune_sex_edu_cbr_nb_unemployment_by_sex_education_and_place_of_birth_t_2025, title = {Unemployment by sex, education and place of birth (thousands) | Europe (ILOSTAT)}, author = {International Labour Organization (ILO)}, year = {2025}, url = {https://www.ilo.org/shinyapps/bulkexplorer/?id=UNE_TUNE_SEX_EDU_CBR_NB}, publisher = {HuggingFace Datasets, repackaged by Electric Sheep Europe}, howpublished = {\url{https://huggingface.co/datasets/electricsheepeurope/europe-ilo-une-tune-sex-edu-cbr-nb-unemployment-by-sex-education-and-place-of-birth-t}} } ``` ## License Released under [cc-by-4.0](https://creativecommons.org/licenses/by/4.0/). Original data © International Labour Organization (ILO). When using this dataset, please cite both the original source above and the Electric Sheep Europe repackaging. ## About Electric Sheep Electric Sheep Europe is part of the Electric Sheep mission: a unified, ML-ready data layer for Europe on HuggingFace. We pull data from authoritative open sources, normalize the schemas, package as Parquet, and publish with consistent dataset cards so researchers and developers can use `load_dataset()` to start working in seconds. Browse the full collection: [huggingface.co/electricsheepeurope](https://huggingface.co/electricsheepeurope) --- _Provenance: ingested 2026-05-27 via the Electric Sheep pipeline. Source URL: https://www.ilo.org/shinyapps/bulkexplorer/?id=UNE_TUNE_SEX_EDU_CBR_NB_
license: CC BY 4.0 language: - en task_categories: - 表格分类 - 表格回归 - 时间序列预测 multilinguality: 单语言 size_categories: - 10K<n<100K tags: - 表格数据 - 欧洲 - ILOSTAT - 国际移民存量 - 国际劳工组织(ILO) - 劳工 - 就业 pretty_name: "按性别、教育程度与出生地区划分的失业人数(千人)| 欧洲(ILOSTAT)" # 按性别、教育程度与出生地区划分的失业人数(千人)| 欧洲(ILOSTAT) 🇪🇺 **33,775 条观测数据** · **36个欧洲国家** · **1987–2025年** · *由[Electric Sheep Europe](https://huggingface.co/electricsheepeurope)重新整理*      ## 快速摘要(TL;DR) 本数据集包含覆盖**36个欧洲国家**、跨度**1987–2025年**的**33,775条**`国际移民存量`(International migrant stock)观测数据,涵盖**1项独立指标**。 ## 数据源说明 **国际劳工组织统计数据库(ILOSTAT)** 是国际劳工组织(ILO)的核心统计数据库,也是全球领先的劳工统计权威来源。其收录涵盖就业、失业、薪资、工作时长、童工、非正规经济、社会保障、职业伤害以及可持续发展目标(SDG)体面工作目标等多类指标,数据来源于全国劳动力调查、家庭收入调查、机构调查及行政记录,覆盖全球200余个经济体,由国际劳工组织统计司负责数据的标准化协调。 - **数据源地址**:[ILOSTAT](https://www.ilo.org/shinyapps/bulkexplorer/?id=UNE_TUNE_SEX_EDU_CBR_NB) - **发布方**:国际劳工组织(ILO) - **许可协议**:[CC BY 4.0](https://creativecommons.org/licenses/by/4.0/) - **主题**:国际移民存量 ## 数据处理方法 本数据集直接从ILOSTAT的REST API接口`https://rplumber.ilo.org/data/indicator?id=UNE_TUNE_SEX_EDU_CBR_NB`拉取原始数据,并筛选出欧洲地区的ISO3国家编码数据。ILOSTAT采用国际劳工统计学家会议(ICLS)定义对原始调查微观数据进行标准化协调,数据来源信息将在`source.label`列中标记以保证可追溯性。 ## 地理覆盖范围 36个欧洲国家,以下为按数据行数排序的前10个国家示例: | 国家 | 数据行数 | 起始年份 | 结束年份 | |---------|-----:|-----------:|----------:| | `GRC` | 1,840 | 1987 | 2025 | | `SWE` | 1,494 | 1995 | 2024 | | `FRA` | 1,485 | 1995 | 2024 | | `NLD` | 1,444 | 1996 | 2024 | | `GBR` | 1,442 | 1995 | 2025 | | `NOR` | 1,355 | 1996 | 2024 | | `PRT` | 1,344 | 1995 | 2025 | | `ESP` | 1,334 | 1995 | 2025 | | `BEL` | 1,307 | 1995 | 2024 | | `IRL` | 1,276 | 1999 | 2024 | | `DNK` | 1,262 | 1995 | 2024 | | `AUT` | 1,151 | 1995 | 2025 | | `LUX` | 1,114 | 1995 | 2024 | | `FIN` | 1,067 | 1995 | 2024 | | `CHE` | 1,003 | 2001 | 2025 | | ... | 其余21个国家 | | | ## 指标(示例) - `UNE_TUNE_SEX_EDU_CBR_NB` — 按性别、教育程度与出生地区划分的失业人数(千人) ## 数据结构(Schema) | 列名 | 数据类型 | 说明 | 示例 | |--------|------|-------------|---------| | `ref_area` | `string` | ISO 3166-1 alpha-3 国家编码 | `ALB` | | `ref_area.label` | `string` | 英文国家名称 | `Albania` | | `source` | `string` | ILOSTAT 数据源编码(如劳动力调查) | `BA:480` | | `source.label` | `string` | 英文数据源名称 | `LFS - 劳动力调查` | | `indicator` | `string` | ILOSTAT 指标编码 | `UNE_TUNE_SEX_EDU_CBR_NB` | | `indicator.label` | `string` | 英文指标名称 | `Unemployment by sex, education and pl…` | | `sex` | `string` | 性别细分维度(`SEX_T`=总计,`SEX_M`=男性,`SEX_F`=女性) | `SEX_T` | | `sex.label` | `string` | 维度说明 | `Total` | | `classif1` | `string` | 第一分类变量(年龄、教育程度、身份等) | `EDU_AGGREGATE_TOTAL` | | `classif1.label` | `string` | 维度说明 | `Education (Aggregate levels): Total` | | `classif2` | `string` | 可选第二分类变量 | `CBR_BIR_TOTAL` | | `classif2.label` | `string` | 维度说明 | `Place of birth: Total` | | `time` | `int64` | 观测年份 | `2024` | | `obs_value` | `float64` | 观测指标值(单位见指标定义) | `108.247` | | `obs_status` | `string` | 观测状态标记(如临时、不可靠) | `U` | | `obs_status.label` | `string` | 状态说明 | `Unreliable` | | `note_classif` | `string` | 分类备注编码 | `C3:5578` | | `note_classif.label` | `string` | 备注说明 | `Nonstandard education level: Includin…` | | `note_indicator` | `string` | 指标备注编码 | `I11:264` | | `note_indicator.label` | `string` | 备注说明 | `Break in series: Methodology revised` | | `note_source` | `string` | 数据源备注编码 | `R1:3513` | | `note_source.label` | `string` | 备注说明 | `Repository: ILO-STATISTICS - Micro da…` | ## 细分维度 以下列提供数据细分维度: - **`sex`**(共3个唯一值):`SEX_T`、`SEX_M`、`SEX_F` ## 数据质量与注意事项 - 本数据集为年度频率数据,部分指标另有月度或季度序列,未包含在本数据集中。 - 当同一国家×年份的同一指标存在多个数据源时,将采用国际劳工组织选定的“最优数据源”。 - 细分维度列(`sex`、`classif1`、`classif2`)仅在指标支持对应细分时才会有非空值。 ## 使用示例 python from datasets import load_dataset ds = load_dataset("electricsheepeurope/europe-ilo-une-tune-sex-edu-cbr-nb-unemployment-by-sex-education-and-place-of-birth-t") df = ds["train"].to_pandas() print(df.head()) ### 筛选单一国家数据 python germany = df[df["ref_area"] == "DEU"] ### 单个指标的时间序列数据 python sample = (df[df["indicator"] == "UNE_TUNE_SEX_EDU_CBR_NB"] .sort_values("time")) sample.plot(x="time", y="obs_value", title="UNE_TUNE_SEX_EDU_CBR_NB") ### 转换为国家×年份矩阵 python matrix = (df[df["indicator"] == "UNE_TUNE_SEX_EDU_CBR_NB"] .pivot_table(index="time", columns="ref_area", values="obs_value")) print(matrix.tail()) ## 引用格式 bibtex @misc{europe_ilo_une_tune_sex_edu_cbr_nb_unemployment_by_sex_education_and_place_of_birth_t_2025, title = {Unemployment by sex, education and place of birth (thousands) | Europe (ILOSTAT)}, author = {International Labour Organization (ILO)}, year = {2025}, url = {https://www.ilo.org/shinyapps/bulkexplorer/?id=UNE_TUNE_SEX_EDU_CBR_NB}, publisher = {HuggingFace Datasets, repackaged by Electric Sheep Europe}, howpublished = {url{https://huggingface.co/datasets/electricsheepeurope/europe-ilo-une-tune-sex-edu-cbr-nb-unemployment-by-sex-education-and-place-of-birth-t}} } ## 许可协议 本数据集采用[CC BY 4.0](https://creativecommons.org/licenses/by/4.0/)协议发布。 原始数据版权归国际劳工组织(ILO)所有。使用本数据集时,请同时引用上述原始数据源及Electric Sheep Europe的重新整理版本。 ## 关于Electric Sheep Electric Sheep Europe是Electric Sheep项目的组成部分,该项目旨在为HuggingFace平台构建统一的、适用于机器学习的欧洲地区数据层。我们从权威开源数据源拉取数据,标准化数据结构,打包为Parquet格式,并发布为格式统一的数据集卡片,以便研究人员与开发者仅需通过`load_dataset()`即可在数秒内启动数据分析工作。 浏览完整数据集集合:[huggingface.co/electricsheepeurope](https://huggingface.co/electricsheepeurope) --- _数据溯源:2026-05-27通过Electric Sheep管道导入。源URL:https://www.ilo.org/shinyapps/bulkexplorer/?id=UNE_TUNE_SEX_EDU_CBR_NB_