nepal-ooc-misinformation
收藏资源简介:
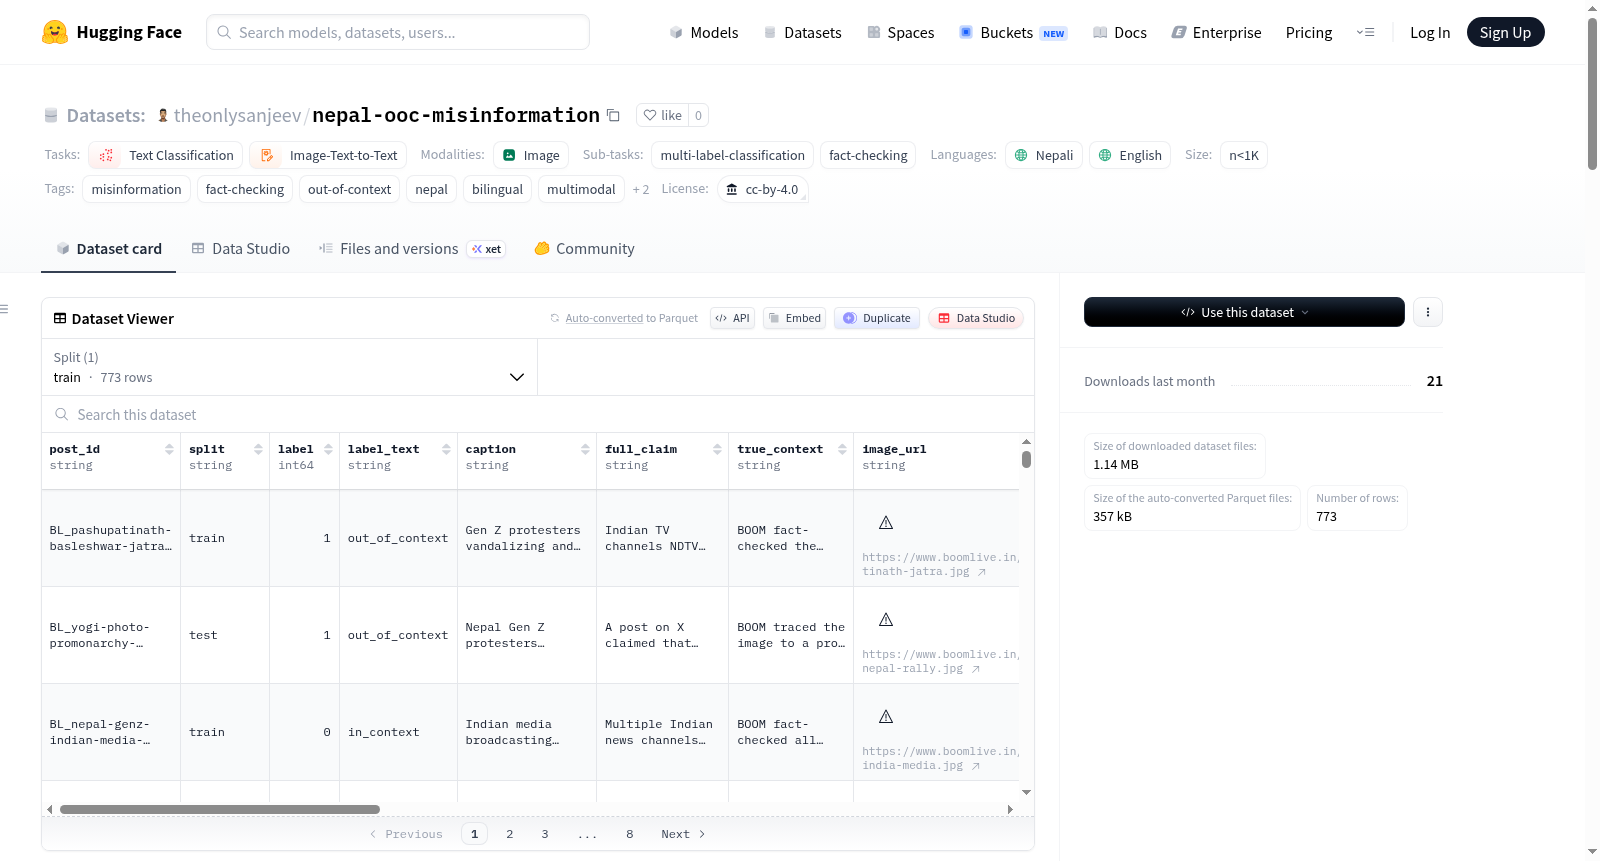
尼泊尔政治背景错误信息数据集(Nepal OOC Political Misinformation Dataset)是一个用于检测尼泊尔政治新闻中背景错误信息(Out-of-Context Misinformation)的双语(尼泊尔语/英语)数据集。该数据集包含773个标注的图像-标题对,收集自尼泊尔的事实核查平台。数据集分为训练集(541条)、验证集(115条)和测试集(117条),其中545条记录包含可下载的图像。数据标注包括背景正确(0)和背景错误(1)两类,并进一步细分为五种错误类型:捏造(Fabricated)、错误标注(Miscaptioned)、时间不匹配(Temporal Mismatch)、地理不匹配(Geographic Mismatch)和身份不匹配(Identity Mismatch)。数据集支持多模态(图像+文本)和纯文本实验,包含丰富的元数据字段,如唯一标识符、分割标签、原始标题、完整声明、真实背景、图像URL、语言类型、来源网站、发布日期等。该数据集适用于多标签分类和事实核查任务,特别关注低资源环境下的政治错误信息检测。
The Nepal OOC Political Misinformation Dataset is a bilingual (Nepali/English) dataset developed to detect out-of-context misinformation in Nepalese political news. This dataset contains 773 annotated image-title pairs collected from Nepalese fact-checking platforms. The dataset is split into a training set (541 instances), a validation set (115 instances), and a test set (117 instances), among which 545 records include downloadable images. The data annotations cover two primary categories: correct context (0) and out-of-context misinformation (1), which are further subdivided into five error types: Fabricated, Miscaptioned, Temporal Mismatch, Geographic Mismatch, and Identity Mismatch. The dataset supports both multimodal (image + text) and text-only experiments, and includes rich metadata fields such as unique identifiers, split labels, original titles, full claims, true context, image URLs, language types, source websites, publication dates, and more. This dataset is applicable to multi-label classification and fact-checking tasks, with a particular focus on political misinformation detection in low-resource settings.
Nepal OOC Political Misinformation Dataset 数据集概述
数据集基本信息
- 数据集名称:Nepal OOC Political Misinformation Dataset
- 发布者:Sanjeev Khatiwada
- 发布年份:2025
- 发布平台:HuggingFace
- 数据集地址:https://huggingface.co/datasets/theonlysanjeev/nepal-ooc-misinformation
- 许可协议:CC BY 4.0
- 联系方式:Sanjeev Khatiwada (skhatiwada558@gmail.com, https://github.com/SanjeevKCodes)
数据集描述
- 核心任务:检测尼泊尔政治新闻中的上下文外(Out-of-Context, OOC)虚假信息。
- 内容:包含773条带标注的图片-标题对,收集自尼泊尔事实核查平台。
- 语言:双语(尼泊尔语/英语)。
- 模态:多模态(文本与图像)。
- 领域:政治新闻。
- 资源类型:低资源语言。
任务与标签
- 任务类别:文本分类、图像-文本到文本。
- 任务ID:多标签分类、事实核查。
- 标签:
0/in_context:上下文内(真实)。1/out_of_context:上下文外(虚假信息)。
数据划分与统计
| 划分 | 总样本数 | 上下文内 (0) | 上下文外 (1) | 可用图像数 |
|---|---|---|---|---|
| 训练集 | 541 | 306 | 235 | 387 |
| 验证集 | 115 | 66 | 49 | 70 |
| 测试集 | 117 | 66 | 51 | 88 |
| 总计 | 773 | 438 | 335 | 545 |
注:773条数据中有545条在收集时图像URL可访问。
image_available列(0/1)标记了哪些行有可下载的图像。多模态实验使用image_available = 1的数据,纯文本实验可使用全部773条数据。
上下文外(OOC)虚假信息类型分布
| 类型 | 数量 |
|---|---|
| 捏造 | 409 |
| 错误配文 | 188 |
| 时间错配 | 86 |
| 地理错配 | 60 |
| 身份错配 | 20 |
语言分布
| 语言 | 数量 |
|---|---|
| 尼泊尔语 (ne) | 539 |
| 英语 (en) | 196 |
| 双语 (ne-en) | 38 |
数据字段说明
| 字段名 | 描述 |
|---|---|
post_id |
唯一行标识符 |
split |
数据划分:train / validation / test |
label |
数字标签:0 = 上下文内,1 = 上下文外 |
label_text |
文本标签:in_context / out_of_context |
caption |
原始图片标题 |
full_claim |
完整的声明文本 |
true_context |
经过核实的真实背景 |
image_url |
源图片URL |
image_available |
图像是否可下载:1=是,0=死链 |
misinformation_type |
OOC虚假信息类型类别 |
verdict |
双语核查结论(如 False / झुटो) |
language |
语言:ne / en / ne-en |
source_site |
事实核查来源网站 |
posted_date |
发布日期 |
categories |
主题类别 |
named_entities |
关键人物、地点、组织 |
数据来源
收集自28个事实核查平台,包括NepalFactCheck, TechPana, Khabarhub, BoomLive, Newschecker Nepal, South Asia Check等。
引用格式
bibtex @dataset{khatiwada2025nepooc, author = {Sanjeev Khatiwada}, title = {Nepal OOC Political Misinformation Dataset}, year = {2025}, publisher = {HuggingFace}, url = {https://huggingface.co/datasets/theonlysanjeev/nepal-ooc-misinformation} }