ecommerce-fraud-detection-synthetic-10k-sampl
收藏资源简介:
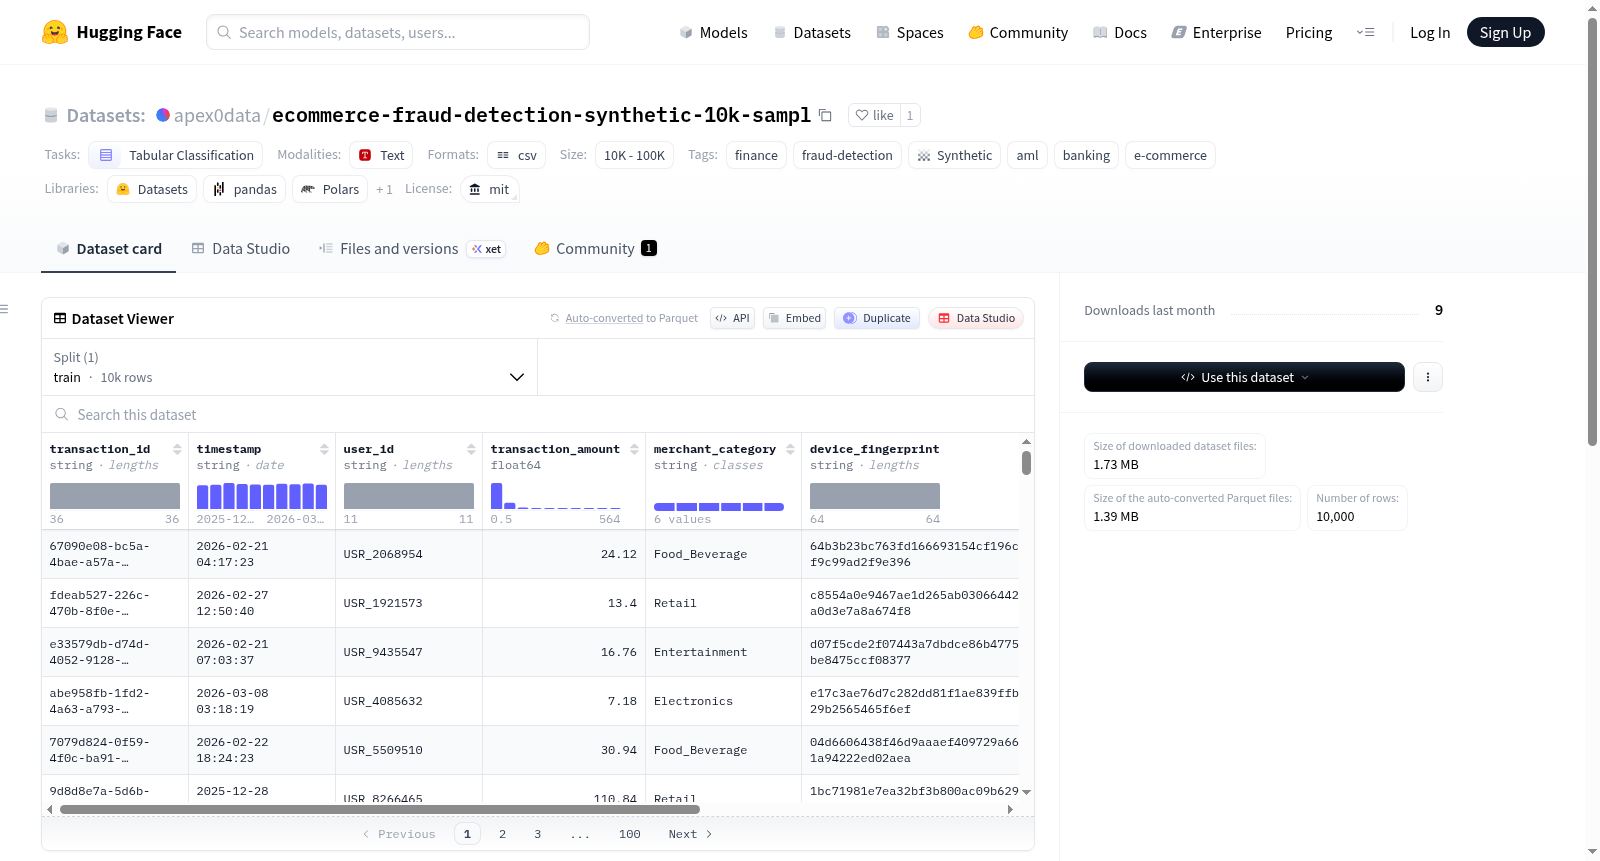
该数据集是一个合成的电子商务欺诈和反洗钱(AML)检测数据集,主要用于表格分类任务。数据集规模在10,000到100,000行之间,当前提供的版本是一个10,000行的评估样本,用于模式验证和本地测试。数据集涵盖金融、欺诈检测、银行和电子商务等领域,采用MIT许可证。用户可以通过Hugging Face的`datasets`库快速加载数据集到Pandas/Python环境中进行使用。完整版的10,000,000行数据集需通过商业许可证获取。
This is a synthetic e-commerce fraud and anti-money laundering (AML) detection dataset primarily intended for tabular classification tasks. The full-scale dataset has a row count ranging from 10,000 to 100,000. The currently available version is a 10,000-row evaluation sample for pattern validation and local testing. Covering domains including finance, fraud detection, banking, and e-commerce, this dataset is distributed under the MIT License. Users can quickly load the dataset into a Pandas/Python environment for use via Hugging Face's `datasets` library. The full 10,000,000-row version of the dataset requires a commercial license for access.
数据集概述
基本信息
- 数据集名称: Synthetic E-Commerce Fraud & AML Detection Dataset (10k Evaluation Sample)
- 发布者: apex0data
- 许可证: mit
- 任务类别: 表格分类
- 数据规模: 10K<n<100K
数据集描述
- 核心内容: 这是一个用于电子商务欺诈和反洗钱检测的合成数据集。
- 样本性质: 本版本是一个截断的10,000行评估样本,严格用于模式验证和本地测试。
- 完整版本: 完整的1000万行数据集需通过商业许可获取。
标签与领域
- 标签: finance, fraud-detection, synthetic, aml, banking, e-commerce
- 应用领域: 金融、欺诈检测、反洗钱、银行业、电子商务。
数据获取与使用
- 评估样本获取: 可通过Hugging Face
datasets库加载。 - 完整商业许可获取地址: https://buy.stripe.com/8x26oIad4eH9eJf6gJ5wI01
- 加载代码示例: python from datasets import load_dataset import pandas as pd dataset = load_dataset("apex0data/ecommerce-fraud-detection-synthetic-10k-sampl", split="train") df = dataset.to_pandas() print(df[is_fraud].value_counts())