supreme-court-of-india-judgements
收藏资源简介:
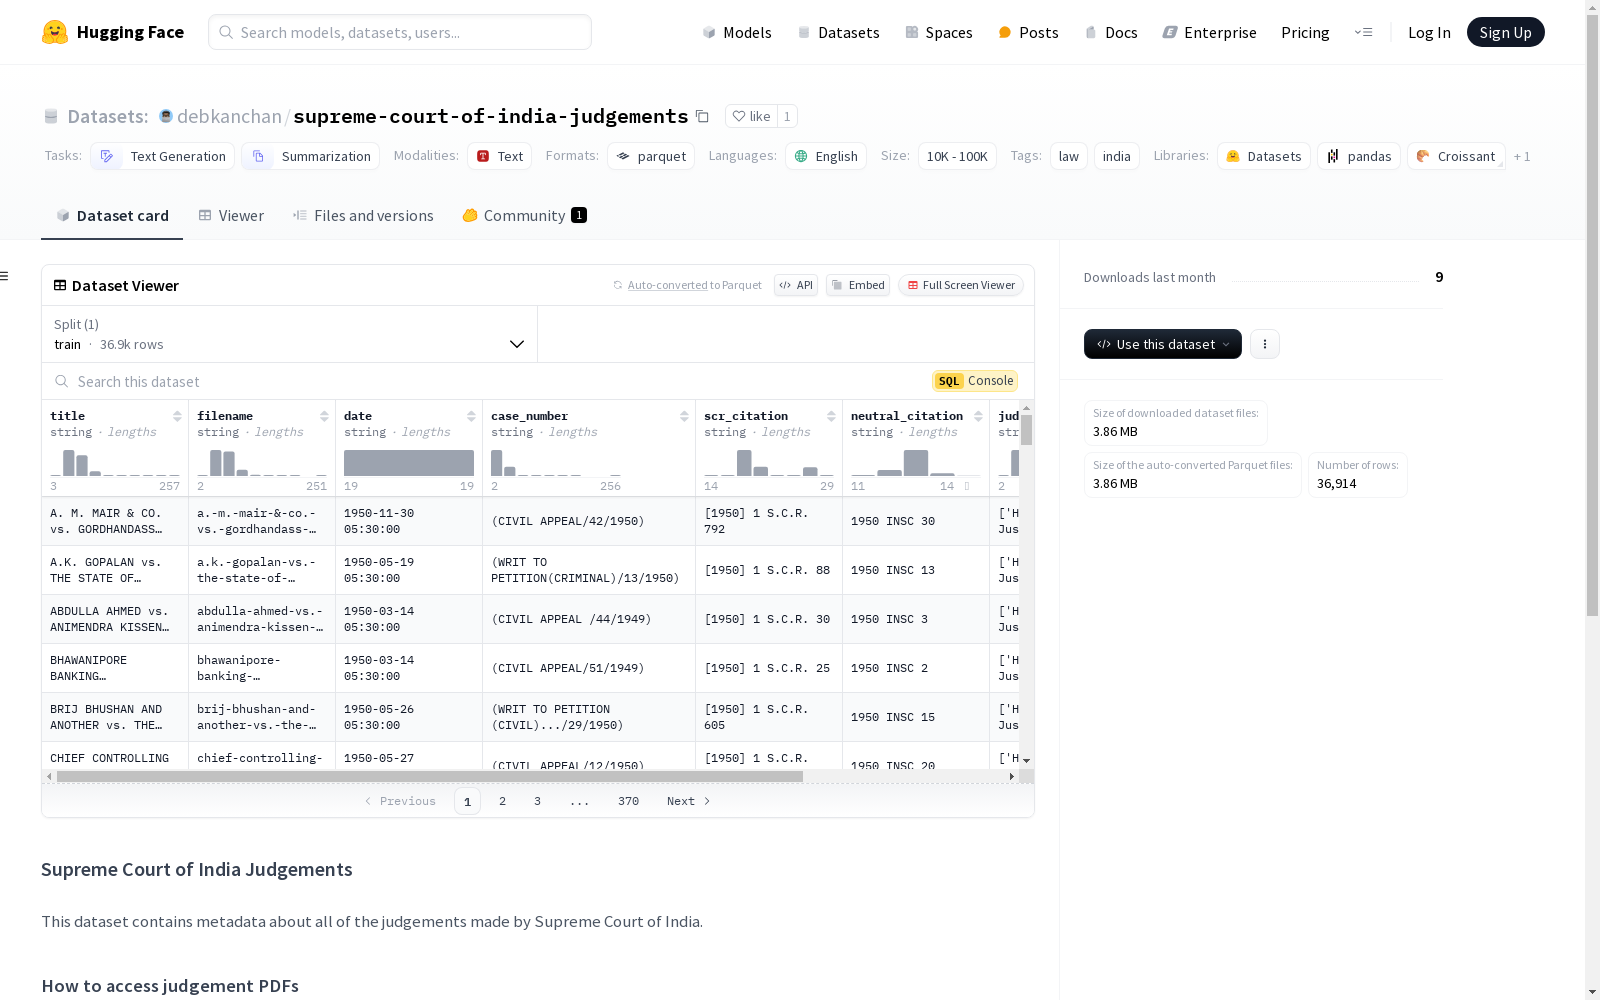
该数据集包含印度最高法院所有判决的元数据,如标题、文件名、日期、案件编号、引用、法官和长度等信息。数据集主要用于文本生成和摘要任务,语言为英语,标签包括法律和印度。数据集的大小类别为10K到100K之间。此外,README还提供了如何访问判决PDF文件的说明,并指出数据来源于印度最高法院的数字报告网站。
This dataset contains metadata for all judgments issued by the Supreme Court of India, covering fields such as title, filename, date, case number, citations, presiding judges, and document length. It is primarily designed for text generation and text summarization tasks, with all content in English. The associated labels are "law" and "India". The dataset size ranges from 10K to 100K. Furthermore, the included README offers guidance on accessing the PDF versions of the judgments, and specifies that the data is sourced from the official digital reporting website of the Supreme Court of India.
数据集概述
数据集名称
Supreme Court of India Judgements
数据集描述
该数据集包含印度最高法院所有判决的元数据。
数据集特征
- title: 判决标题,数据类型为字符串。
- filename: 文件名,数据类型为字符串。
- date: 判决日期,数据类型为字符串。
- case_number: 案件编号,数据类型为字符串。
- scr_citation: SCR引用,数据类型为字符串。
- neutral_citation: 中立引用,数据类型为字符串。
- judges: 法官,数据类型为字符串。
- length: 判决长度,数据类型为浮点数。
数据集分割
- train:
- 字节数: 11851182
- 样本数: 36914
下载信息
- 下载大小: 3857778 字节
- 数据集大小: 11851182 字节
配置
- config_name: default
- data_files:
- split: train
- path: data/train-*
- data_files:
任务类别
- 文本生成
- 摘要生成
语言
- 英语 (en)
标签
- 法律
- 印度
数据集大小类别
- 10K < n < 100K
访问判决PDF
所有判决文件上传至Cloudflare R2存储桶:https://pub-93a7aae0244344319e35611fdc1c80ef.r2.dev
访问特定判决PDF的方法:将判决的filename属性加上".pdf",然后进行URL编码作为路径。
示例:对于filename为"(ex)-capt.-randhir-singh-dhull-vs.-s.-d.-bhambri-,-others"的判决,可以通过以下链接访问PDF:https://pub-93a7aae0244344319e35611fdc1c80ef.r2.dev/(ex)-capt.-randhir-singh-dhull-vs.-s.-d.-bhambri-%26-others.pdf
数据来源
该数据从印度最高法院的数字最高法院报告网站(DigiSCR)抓取:https://digiscr.sci.gov.in
用途
该数据集旨在帮助用户查找和处理最高法院判决,而无需手动抓取数据。