anas775/DETECT-AI-Dataset
收藏资源简介:
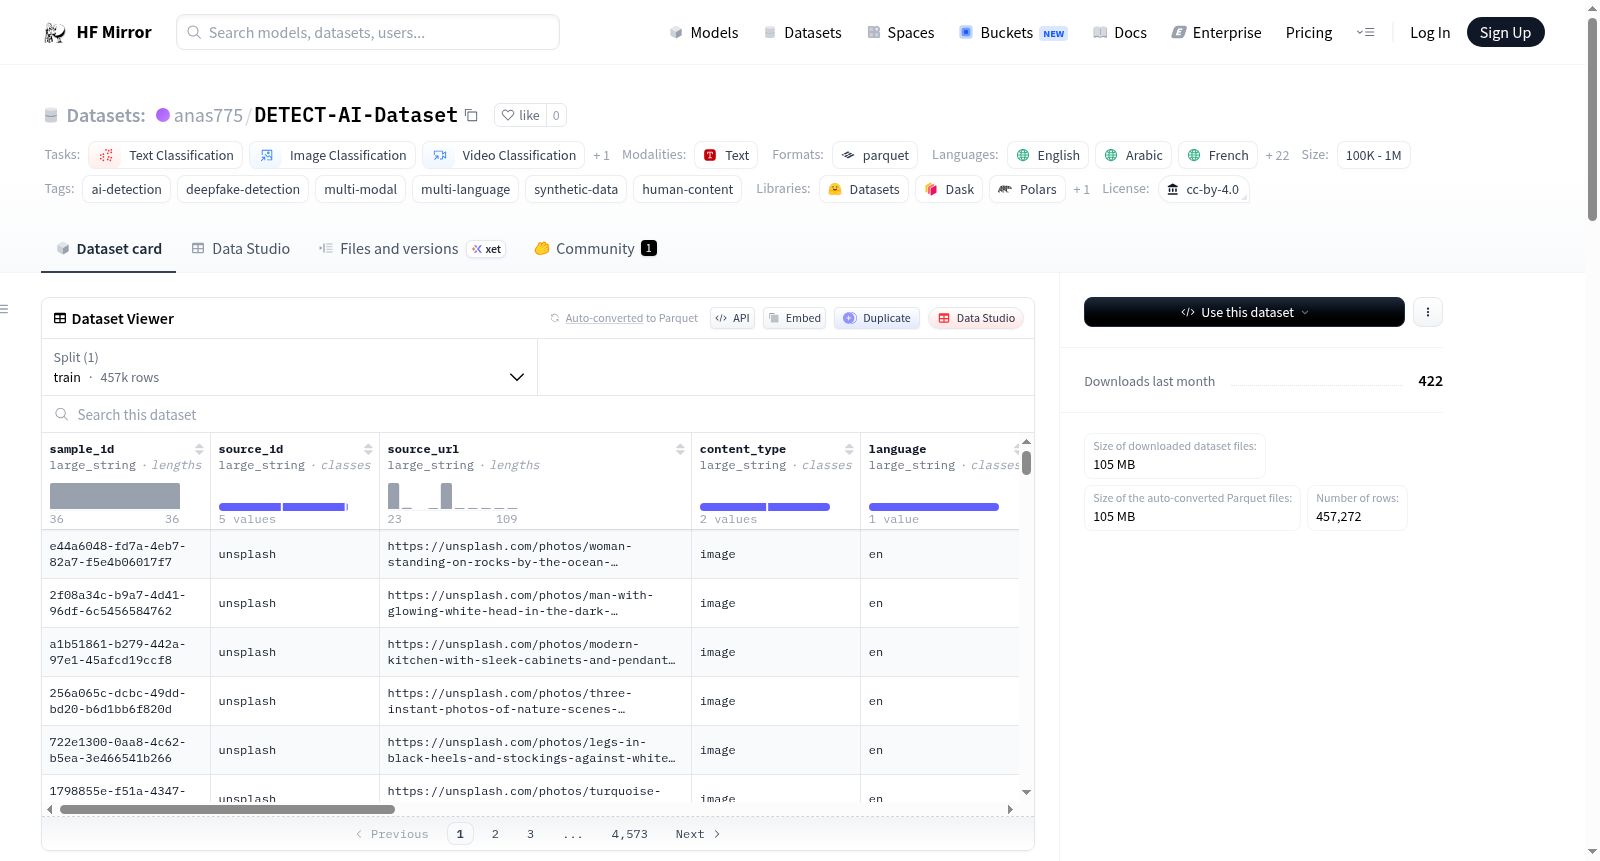
DETECT-AI多模态AI内容检测数据集是一个大规模、多语言的数据集,包含文本、图像、视频和音频四种模态的数据。该数据集每月从19个全球来源收集超过10亿个经过验证的样本,并使用8个专门的AI检测模型进行加权标注。数据集支持包括英语、中文在内的多种语言,规模在10亿到100亿之间。数据集包含AI生成内容、人类内容和不确定内容的标签,主要用于AI内容检测任务。数据集来源广泛,包括BBC、Reuters、Al Jazeera等多个全球来源。数据集采用Pipeline架构进行数据处理,遵循CC-BY-4.0许可协议,可用于研究和商业用途。
The DETECT-AI Multi-Modal AI Content Detection Dataset is a large-scale, multi-language dataset containing four modalities of data: text, image, video, and audio. The dataset collects over 1 billion verified samples per month from 19 global sources and labels them using a weighted ensemble of 8 specialized AI-detection models. The dataset supports multiple languages including English and Chinese, with a size between 1 billion and 10 billion. It includes labels for AI-generated content, human content, and uncertain content, primarily used for AI content detection tasks. The dataset sources are extensive, including BBC, Reuters, Al Jazeera, and other global sources. The dataset employs a Pipeline architecture for data processing and follows the CC-BY-4.0 license, allowing for both research and commercial use.